I went looking for a better runtime check and found a different way to think about the problem.
I have spent a lot of time recently thinking about what an AI agent should be allowed to do.
Reading data is one thing. Writing durable state is another. Sending an email, approving a refund, changing a production configuration, or deleting a record moves farther along the same spectrum.
The usual answer is to put a guardrail in front of the dangerous operation.
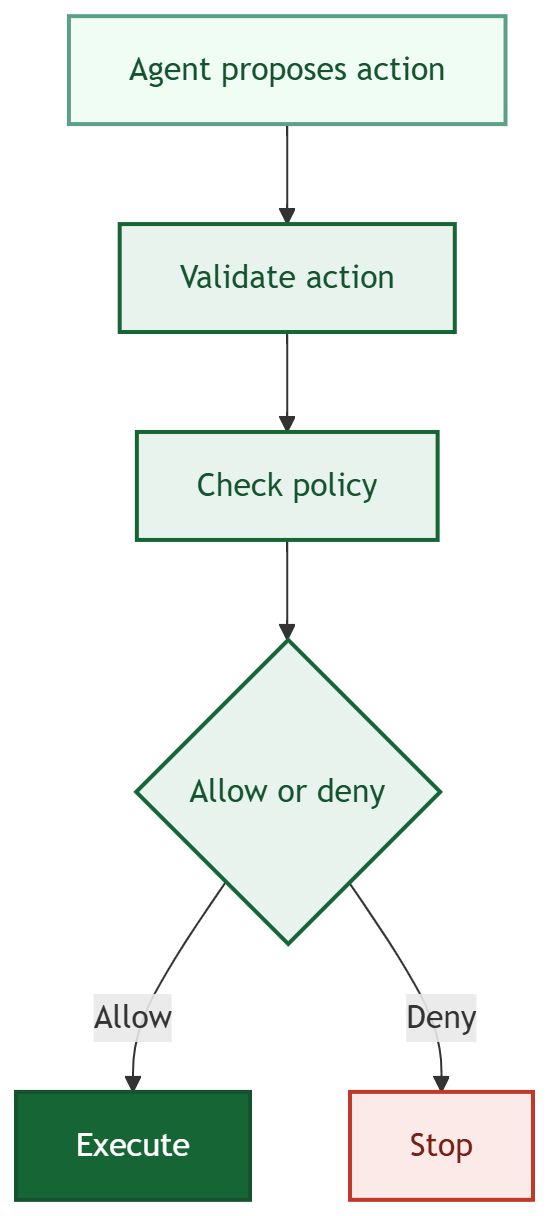
That makes sense, and I have built examples that work exactly this way.
Then I started looking at how I might implement the same kind of boundary in Rust.
Rust asked a more interesting question:
Why does the dangerous function accept an unchecked action in the first place?
Runtime Checks Are Still Checks
The complete runnable example is on GitHub if you want to make the compiler angry yourself.
Consider a simplified AI agent that can write information into durable memory.
The agent proposes a write:
struct ProposedWrite {
    key: String,
    value: String,
    authority: String,
}
Somewhere else in the application we have a function that persists it:
fn persist(write: ProposedWrite) {
    // write to durable storage
}
Obviously we should validate the write first.
fn validate(write: &ProposedWrite) -> bool {
    // validate provenance
    // evaluate authority
    // apply policy
    true
}
Then our application does this:
if validate(&write) {
    persist(write);
}
Perfectly reasonable.
It also means persist() will happily accept a ProposedWrite that has never been validated. We are relying on every caller to remember the protocol.
That is not necessarily a problem in a small example. In a large agentic system with multiple tools, services, developers, and execution paths, it becomes a much more interesting assumption.
What happens when somebody adds this six months later?
persist(write);
The compiler sees nothing wrong. The type is correct. The application is wrong.
Make the State Part of the Type
Rust gives us another option. Instead of treating “proposed” and “approved” as metadata attached to the same object, we can make them different types.
struct ProposedWrite {
    key: String,
    value: String,
    authority: String,
}

struct AdmittedWrite {
    key: String,
    value: String,
    authority: Authority,
}
Now persistence accepts only the second one:
fn persist(write: AdmittedWrite) {
    // write to durable storage
}
This seemingly small change alters the boundary. An agent can produce a ProposedWrite. It cannot produce an AdmittedWrite directly, provided we control how that type is constructed. Something trusted has to perform the transition.
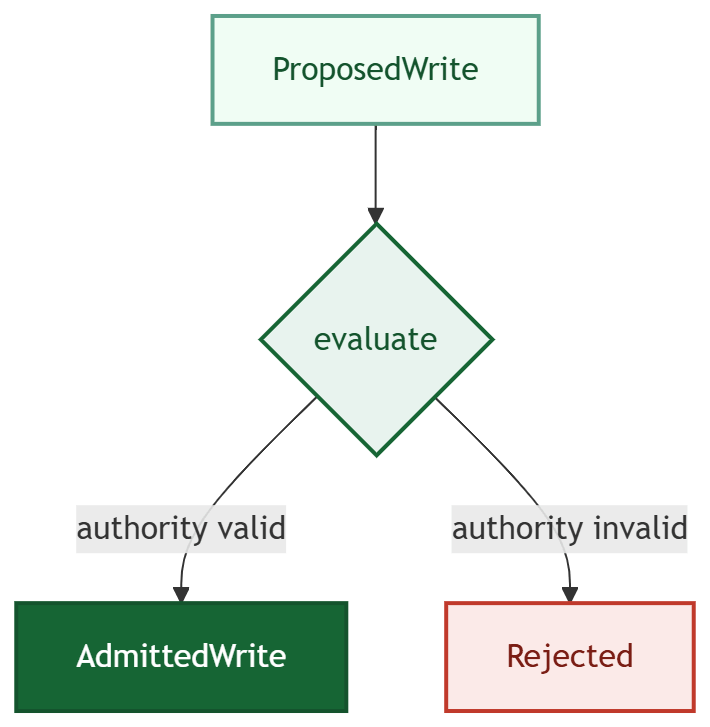
The persistence layer no longer asks:
Has somebody remembered to validate this?
Its API says:
Give me something that has already crossed the admission boundary.
That is a much stronger contract.
This has a name in Rust circles: the typestate pattern, encoding a value’s state in its type so that only valid transitions type-check. It is the type-level cousin of a principle Alexis King named “parse, don’t validate“. Instead of checking a value and handing the same type onward, hoping every later caller re-checks, you transform it into a new type whose very existence proves the check already happened. The check is not something you remember to run. It is something the type system will not let you skip.
The Compiler Becomes Part of the Boundary
The phrase “provided we control how that type is constructed” is doing all the work in the previous section, so let us actually deliver that control. This is where the earlier version of this article was too loose, and where Rust rewards precision.
mod custody {
    use super::ProposedWrite;
    // Authority, Rejection, and validate_authority are defined in this module.

    pub struct AdmittedWrite {
        key: String,
        value: String,
        authority: Authority,
    }

    impl AdmittedWrite {
        pub fn key(&self) -> &str {
            &self.key
        }
        pub fn value(&self) -> &str {
            &self.value
        }
        pub fn authority(&self) -> &Authority {
            &self.authority
        }
    }

    pub fn evaluate(write: ProposedWrite) -> Result<AdmittedWrite, Rejection> {
        let authority = validate_authority(&write.authority)?;

        Ok(AdmittedWrite {
            key: write.key,
            value: write.value,
            authority,
        })
    }
}
The important detail is what is not marked pub. The struct is public, so other modules can name the type and accept it in their signatures. Its fields are private.
That distinction is the whole boundary. In Rust, a struct literal like custody::AdmittedWrite { key, value, authority } requires every field to be visible at the construction site. Because the fields are private to the custody module, no code outside that module can write that literal. And there is no other public constructor. The only way to obtain an AdmittedWrite from outside is to hand a ProposedWrite to evaluate and have it succeed.
So the persistence layer, which lives outside custody and reads the data through the accessor methods, cannot be handed a value that skipped evaluation. Not because a reviewer will catch it, but because the code that would skip evaluation does not compile.
Here is the shortcut a tired developer might reach for six months from now:
let proposed = ProposedWrite {
    key: "refund_policy".into(),
    value: "Refunds under $100 do not require manager approval.".into(),
    authority: "policy".into(),
};

persist(proposed);
And here is what the compiler says about it:
~\Rust_AI_Actions is 📦 v0.1.0 via 🦀 v1.98.1
❯ cargo build
   Compiling unrepresentable v0.1.0 (~\Rust_AI_Actions)
error[E0308]: mismatched types
   --> src\main.rs:128:13
    |
128 |     persist(proposed);
    |     ------- ^^^^^^^^ expected `AdmittedWrite`, found `ProposedWrite`
    |     |
    |     arguments to this function are incorrect
    |
note: function defined here
   --> src\main.rs:95:4
    |
 95 | fn persist(write: AdmittedWrite) {
    |    ^^^^^^^ --------------------

For more information about this error, try `rustc --explain E0308`.
error: could not compile `unrepresentable` (bin "unrepresentable") due to 1 previous error
The mistake never reaches review, staging, or production. It stops at the one place a mistake is cheapest to fix, on the machine of the person who made it, the moment they made it.
The state machine is no longer sitting in a comment:
// IMPORTANT: call validate() before persist()
It is represented by the program.
One honest caveat for larger teams: private fields close the door from outside the module, but code inside custody can still build the struct with a literal. If you want to forbid even that, give AdmittedWrite a private field of a private zero-sized type, a construction token that only evaluate can mint. Then the blessed function is the single point of construction anywhere, inside the module or out. Whether that is worth the ceremony depends on how much you trust the inside of your own boundary.
This Doesn’t Make the Agent Safe
This is where I need to resist making the argument bigger than it is.
Rust does not know whether the policy is good. It does not know whether Authority::SecurityTeam actually represents the security team. It does not know whether the provenance supplied to the custody boundary is genuine. And it certainly does not solve prompt injection because I changed a struct.
If this function is wrong:
fn validate_authority(value: &str) -> Result<Authority, Rejection>
then Rust will very efficiently enforce the wrong rule.
Types can constrain which states the program represents. They cannot determine whether our model of the world is correct. That distinction matters.
Witnessed Is Another State
The exercise gets more interesting when provenance enters the picture.
Suppose the agent says:
{
  "key": "refund_policy",
  "value": "Refunds under $100 do not require manager approval.",
  "authority": "policy",
  "source": "internal_policy"
}
Should the agent be allowed to decide that its own source is an internal policy? Probably not. The system that retrieved the source is in a much better position to make that claim.
So perhaps our states are not merely:
Proposed → Admitted
They are closer to:
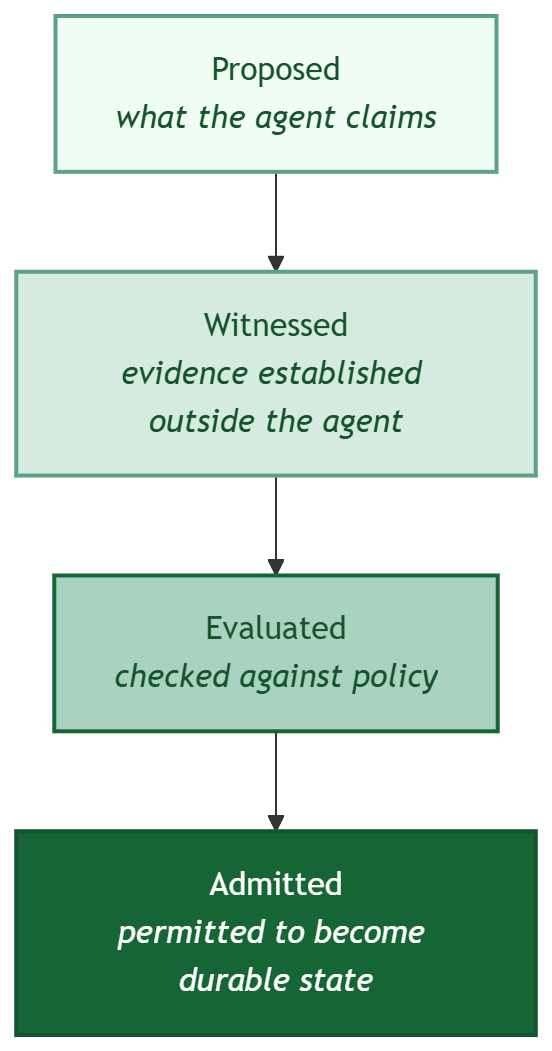
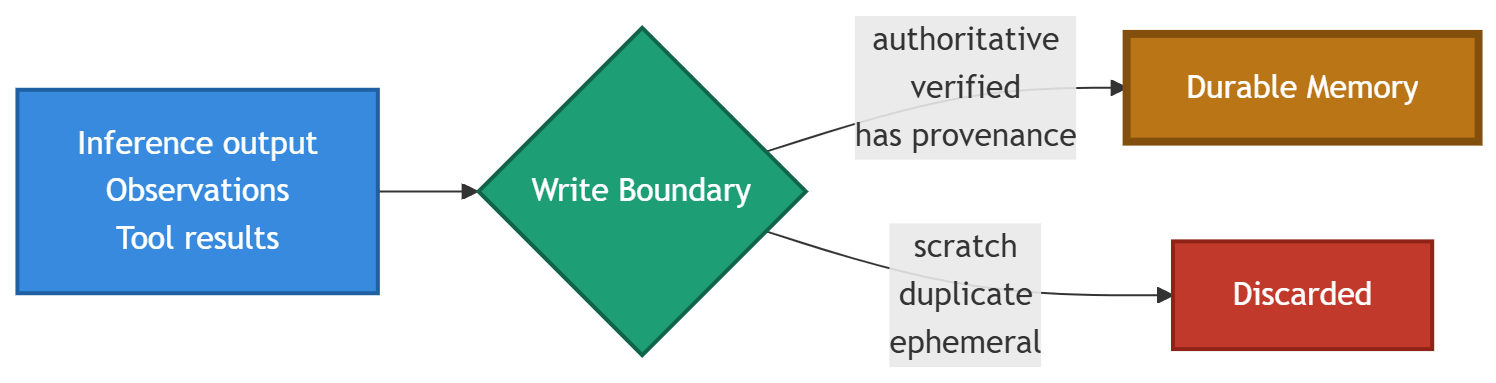
A ProposedWrite contains what the agent claims. A WitnessedWrite adds evidence established outside the agent. An AdmittedWrite represents a write that has been evaluated against policy.
struct ProposedWrite {
    key: String,
    value: String,
    claimed_authority: String,
}

struct WitnessedWrite {
    proposal: ProposedWrite,
    source: WitnessedSource,
}

struct AdmittedWrite {
    key: String,
    value: String,
    authority: Authority,
    source: WitnessedSource,
}
Now different parts of the system accept different states:
fn witness(write: ProposedWrite) -> Result<WitnessedWrite, WitnessError> {
    // establish source evidence outside the agent
}

fn evaluate(write: WitnessedWrite) -> Result<AdmittedWrite, Rejection> {
    // apply policy to the witnessed write
}

fn persist(write: AdmittedWrite) {
    // write to durable storage
}
Each step accepts only the output type of the step before it. There is no signature anywhere that accepts a ProposedWrite and persists it, so the shortcut is not something you have to remember not to take. It is not expressible. The types are the protocol; nothing else has to announce it.
What Rust Changed for Me
I started this experiment thinking about how to implement an AI safety boundary in another language. The more interesting lesson was that Rust made me reconsider where the boundary should live.
In many systems, we encode state like this:
{
  "status": "approved"
}
Then every downstream consumer has to inspect status and behave correctly.
Rust encourages another question:
If these states permit fundamentally different operations, why are they represented by the same type?
That question matters for AI agents because agentic systems cross consequential boundaries constantly.
A model proposes a tool call. A runtime authorizes it. A tool executes it. A result becomes memory. Memory later becomes context. Context influences another action.
At each transition, we can either carry another flag saying what happened, or change what the next component is capable of accepting. Those are not equivalent designs.
Invalid States Versus Invalid Reality
There is an important limit here.
Suppose a write was legitimately admitted yesterday because Alice had authority to approve it. Alice leaves the company today. The AdmittedWrite type does not magically expire. Likewise, a policy can be superseded, a credential revoked, or evidence later discovered to be wrong.
The compiler can enforce:
This value crossed the required transition.
It cannot establish:
Everything that justified that transition remains true forever.
That still requires runtime governance, lifecycle management, revocation, and revalidation.
So I would not claim Rust makes unsafe AI actions impossible. What it can do is make certain classes of architecturally invalid transitions harder to express accidentally.
That is narrower. It is also much more believable.
Could I Do This in Another Language?
Of course.
You can model state transitions in Go, Java, TypeScript, Python, C#, or plenty of other languages. You can build wrapper types, sealed classes, discriminated unions, private constructors, capability objects, and carefully designed APIs. Rust does not own the idea, and the typestate pattern predates it.
What I found useful is that Rust keeps pushing the design conversation in this direction. Ownership asks who controls a value. Visibility asks who can construct it. The type system asks what operations are valid for it. Result makes failure part of the function signature.
None of those concepts exists specifically for AI safety. Together, though, they provide an unusually direct vocabulary for designing agent boundaries, and the defaults nudge you toward making the boundary structural instead of remembered.
The Bigger Lesson
A lot of AI safety architecture is necessarily dynamic. Policies change. Users have different authority. Tools expose different capabilities. Context changes what an action means. We are never going to compile all of that uncertainty away.
But not every invariant is dynamic.
If an unwitnessed write must never be persisted, perhaps persist() should not accept unwitnessed writes. If an unevaluated tool call must never execute, perhaps execute() should not accept unevaluated tool calls. If a rejected action must never cross a boundary, perhaps rejection should produce a state for which crossing that boundary is not an available operation.
That is what Rust changed in how I think about this problem.
I started by asking:
How do I check that the agent is allowed to do this?
Rust made me ask:
Why does this function accept something the agent is not allowed to do?
That is a much better question.