Context Hydration: When Memory Becomes Voice

Part 7 of the Building the AI Memory Stack series

Back in Part 1, I made a promise: memory eventually becomes voice.

Up to this point, we’ve built the architecture that makes trustworthy memory possible.

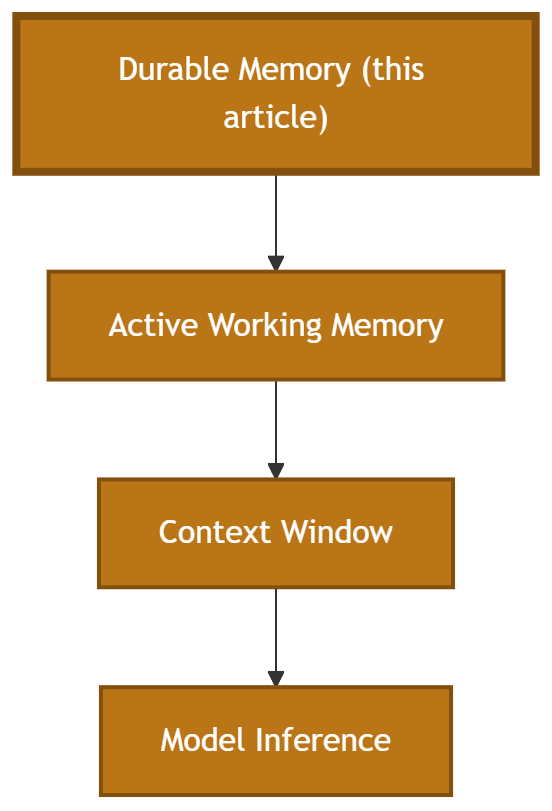
The Context Window executes work.

Active Working Memory assembles the state required for that work.

Durable Memory preserves knowledge worth keeping.

The Reasoning Ledger explains how decisions were made.

Write-Side Custody ensures only trustworthy information becomes institutional memory.

Forensic Receipts make that memory provable.

All of that effort leads to one inevitable question:

How does cold, trustworthy memory become useful reasoning again?

The answer is Context Hydration.
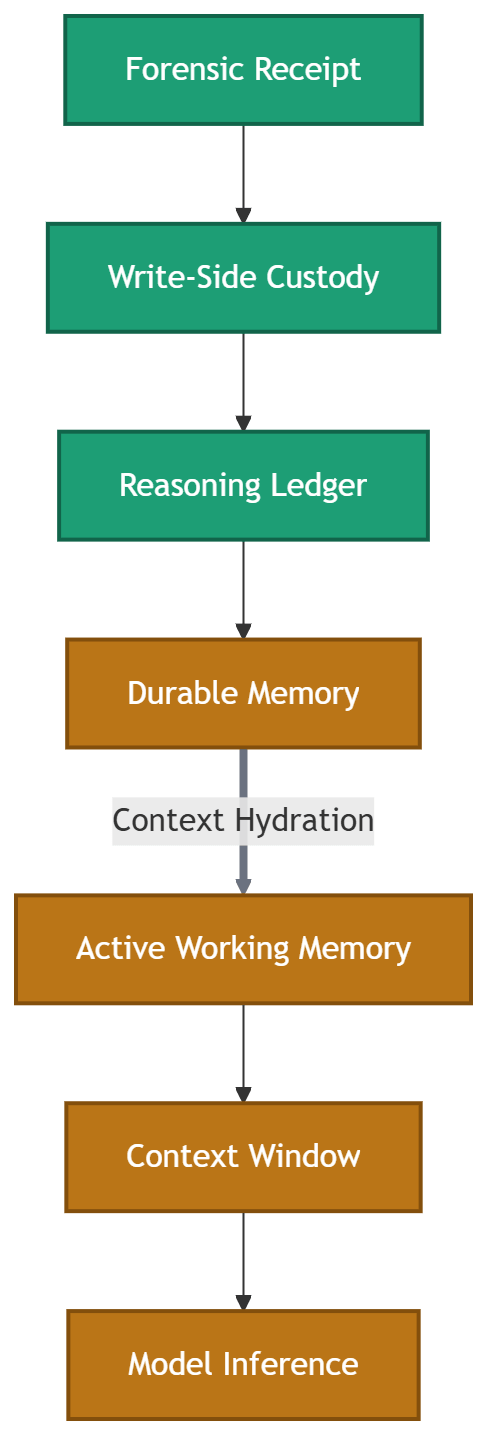
Flowchart showing the AI Memory Stack flow from Forensic Receipt down to Model Inference, highlighting the Context Hydration transition between Durable Memory and Active Working Memory.

Notice that Context Hydration is not another layer. It is the transition that lifts stored memory back into active reasoning, the arrow rather than the box.

Memory That Never Returns Isn’t Very Useful

Imagine an engineering handbook containing thousands of Architecture Decision Records. Every decision has provenance, every revision has history, and every document was validated before it entered long-term storage. It’s a remarkable archive.

Until an AI agent needs to answer a question.

At that moment, none of that durable knowledge matters until some of it is restored into working memory. Stored knowledge is inert. Reasoning requires living context.

Hydration Is More Than Retrieval

Traditional retrieval systems ask one question:

“Which documents are relevant?”

Context Hydration asks a different one:

“Which verified knowledge deserves to consume tokens for this task?”

Those questions sound similar, but architecturally they are very different.

Retrieval finds. Hydration restores.

The Hydration Boundary

The Sovereign Systems Specification calls this transition the Hydration Boundary.

Flowchart mapping the five sequential steps across the Hydration Boundary, from Durable Memory to the Context Window.

Before information crosses that boundary, the system asks:

  • Has this information been verified?
  • Is it still authoritative?
  • Does this task actually require it?
  • Is there a cheaper representation?
  • What is the token cost of restoring it?

Hydration is not a bulk export. It is deliberate reconstruction.

Verification Before Expansion

One subtle architectural decision matters enormously: the system should verify memory before expanding it into prompts. Verification is cheap; context windows are expensive. Hydrating untrusted information wastes both compute and attention.

The cheapest token is the one you never have to generate.

Hydrate Only What the Task Needs

One of the biggest misconceptions in agent design is that bigger context automatically produces better answers. Usually it produces more distraction.

Every additional document competes for the model’s attention.

Every unnecessary paragraph increases the Context Tax.

Every observation collected “just in case” contributes to the Observer’s Tax.

Good hydration isn’t about restoring everything. It’s about restoring enough.

Latency Is Part of the Architecture

Hydration has a cost. Verification, retrieval, expansion, and serialization all take time, and every layer adds latency.

That doesn’t make hydration a bad idea. It makes it an architectural tradeoff rather than an implementation detail.

The question isn’t “Can we hydrate this?” The better question is:

“Is this memory worth paying to restore?”

When Memory Becomes Voice

This is the promise we began with. Memory has no value sitting on disk. It becomes valuable only when trusted knowledge crosses the Hydration Boundary and becomes reasoning once again.

That is the moment memory becomes voice.

Looking Ahead

We’ve now assembled the complete AI Memory Stack. The final two articles zoom out.

The next explores the hidden economic costs of prompt-centric architectures: the Prose Tax, the Retrieval Tax, and the broader fiscal architecture of modern AI systems.

Because building trustworthy memory is only half the challenge. Operating it efficiently is the other half.

Facebooktwitterredditlinkedinmail

Durable Memory: Why Vector Databases Aren’t Enough

Part 3 of the Building the AI Memory Stack series

After finishing Part 2, I noticed something.

The browser tabs I had open while writing it were gone. The temporary notes were gone. The diagrams existed only while I was drafting.

The article remained.

That is the question underneath this entire post. Why did one thing survive when everything else disappeared?

A reader asked a version of it directly:

“If Active Working Memory is assembled for each task, where does all of that information come from?”

Most conversations stop at a simple answer.

“The vector database.”

That answer isn’t wrong.

It’s just incomplete.

A vector database is one implementation of durable memory. It is not the architectural definition of durable memory.

Those are very different ideas.

Durable Memory Is Curated

If Active Working Memory is RAM, Durable Memory is not simply “disk.”

Flow diagram showing Durable Memory feeding Active Working Memory, which supplies the Context Window used for Model Inference.

Disk stores everything.

Durable Memory stores what the system intentionally decides to preserve.

Durable Memory is not a place. It’s a policy.

That is a much narrower responsibility.

A durable memory layer may contain:

  • Specifications
  • User preferences
  • Signed evidence
  • Architecture Decision Records
  • Policies
  • Verified observations
  • Structured domain knowledge
  • Historical interactions

Notice what is missing.

  • Scratch calculations
  • Intermediate reasoning
  • Temporary tool output
  • Duplicate information
  • Ephemeral context

Those things may have been useful.

That does not mean they deserve to survive.

What Survives Matters

Human memory works the same way.

You don’t remember every sentence you read yesterday.

You remember what became worth remembering.

Agentic systems face exactly the same problem.

Not everything that passes through inference deserves to become memory.

Consider the kind of task from the last article: an agent maintaining an SDK. In a single pass it might retrieve several Architecture Decision Records, read a dozen Git commits, inspect a couple of open issues, call three tools, and generate intermediate summaries along the way.

When the task finishes, should all of that become memory?

Of course not.

Durable Memory is not everything the system observed. It is what the system intentionally decided was worth preserving.

Memory Is a Write Problem

One pattern I’ve noticed across many AI systems is that enormous effort goes into retrieval.

Teams debate embedding strategies, chunk sizes, hybrid search, semantic similarity, and re-ranking pipelines.

Yet comparatively little attention is paid to the opposite question.

Should this be remembered at all?

That is fundamentally a write-side decision.

Traditional software engineers already make this decision every day. We don’t check temporary variables into Git. We don’t commit compiler output. We don’t version our cache directories. We deliberately preserve the artifacts that represent knowledge and discard the ones that existed only to complete today’s work.

Durable Memory asks an agentic system to make the same distinction.

Every stored artifact becomes future context.

Every stored artifact has a maintenance cost.

Every stored artifact competes for future retrieval.

Every write is a promise to your future retrieval system.

Memory is not free simply because storage is inexpensive.

A system that remembers everything eventually remembers nothing particularly well.

The specification has a name for that failure state: the Digital Attic, where everything is kept and nothing can be found.

And when a Digital Attic gets queried, it hands your application a poisoned working set—a mix of current requirements, obsolete notes, and conflicting observations.

When that un-sieved context hits the context window, the system falls into Agentic Thrashing: spending precious inference cycles attempting to reconcile contradictory history rather than making forward progress.

The Difference Between Storage and Memory

This is why I think storage and memory should be treated as separate architectural concepts.

Storage answers:

Can we keep this?

Memory answers:

Should we keep this?

Those are different questions.

A filesystem stores.

A database stores.

An object store stores.

Durable Memory decides.

The Write Boundary

In traditional software architecture we spend a great deal of time discussing APIs.

In agentic systems, I increasingly think the more important boundary is the write boundary, what the specification calls Write-Side Custody.

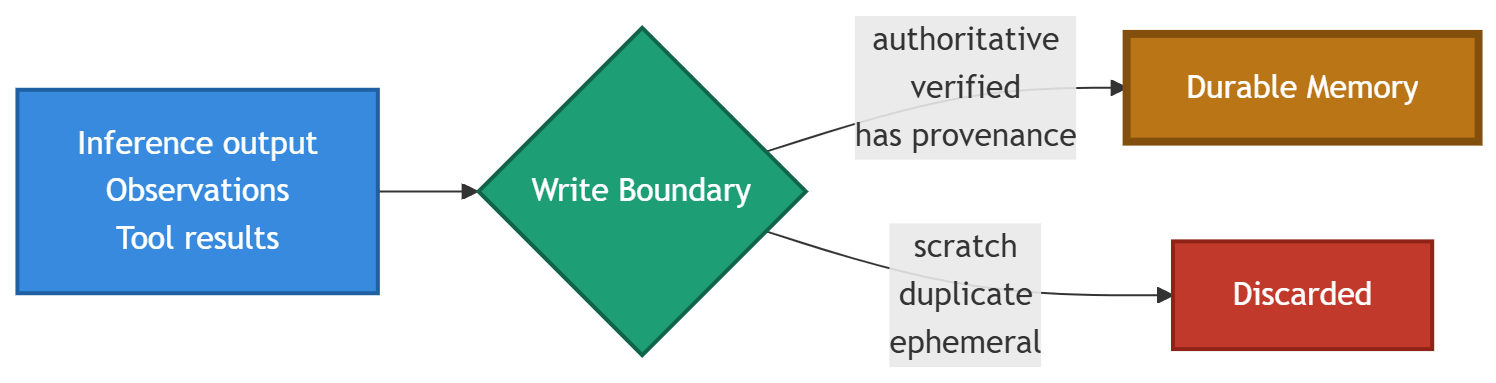
Write boundary flow showing inference output, observations, and tool results evaluated before persistence. Authoritative, verified information with provenance enters Durable Memory, while scratch, duplicate, and ephemeral information is discarded.

Every piece of information attempting to cross into Durable Memory should answer questions such as:

  • Is this authoritative?
  • Is it verified?
  • Does it duplicate existing knowledge?
  • Does it expire?
  • Can its provenance be established?
  • Is it useful outside the current task?

Those questions determine whether something becomes memory or remains temporary context.

This Is Where Provenance Begins

This is also the point where the Sovereign Systems Specification begins to diverge from many AI architectures.

A memory that cannot explain why it exists is difficult to trust.

If an observation enters Durable Memory, the system should be able to answer:

  • Who created it?
  • When?
  • Under what authority?
  • Based on what evidence?
  • Has it changed?
  • Can it be verified?

Without those answers, Durable Memory slowly becomes institutional folklore rather than institutional knowledge.

Information without provenance is just gossip.

Durable Memory Is an Architectural Responsibility

Just as the previous article argued that Active Working Memory is more than prompt construction, Durable Memory is more than persistent storage.

It is memory as infrastructure: the architectural responsibility for deciding what knowledge deserves to outlive the task that created it.

That responsibility shapes every article that follows.

Deciding what deserves to survive is only the beginning.

The next question is whether the path that produced that knowledge can itself be examined.

That is where Part 4 begins.

Facebooktwitterredditlinkedinmail