Part 9 of the Building the AI Memory Stack series
This series began with a deceptively simple observation: a context window is not memory.
That idea evolved into an architectural model for building AI systems that remember, explain, verify, and restore information responsibly. Along the way we explored the purpose of the Context Window, the role of Active Working Memory, the permanence of Durable Memory, the accountability provided by the Reasoning Ledger, the trust established through Write-Side Custody, the cryptographic evidence supplied by Forensic Receipts, the restoration performed by Context Hydration, and the economic realities introduced by architectural taxes.
Those individual ideas are not isolated concepts. Together they form a coherent system.
Six Architectural Responsibilities
The AI Memory Stack is not six storage technologies layered on top of one another.
It is six architectural responsibilities every trustworthy AI system must answer.
| Responsibility | Question | Sovereign Concept |
|---|---|---|
| Execution | What can I see right now? | Context Window |
| Assembly | What matters right now? | Active Working Memory |
| Preservation | What should survive? | Durable Memory |
| Explanation | Why did this happen? | Reasoning Ledger |
| Integrity | Should this become truth? | Write-Side Custody |
| Evidence | Can I prove it? | Forensic Receipt |
Each responsibility exists because it solves a different problem. Durable Memory cannot explain why a decision was made. A Reasoning Ledger cannot prove its records have not been modified. A Context Window cannot preserve institutional knowledge. Together they create a system that is substantially more capable than any individual component.
Teaching Order Versus Runtime
Throughout this series we intentionally walked down through the stack, beginning with the familiar idea of prompts before gradually uncovering the deeper responsibilities beneath them.
A production system operates in the opposite direction.
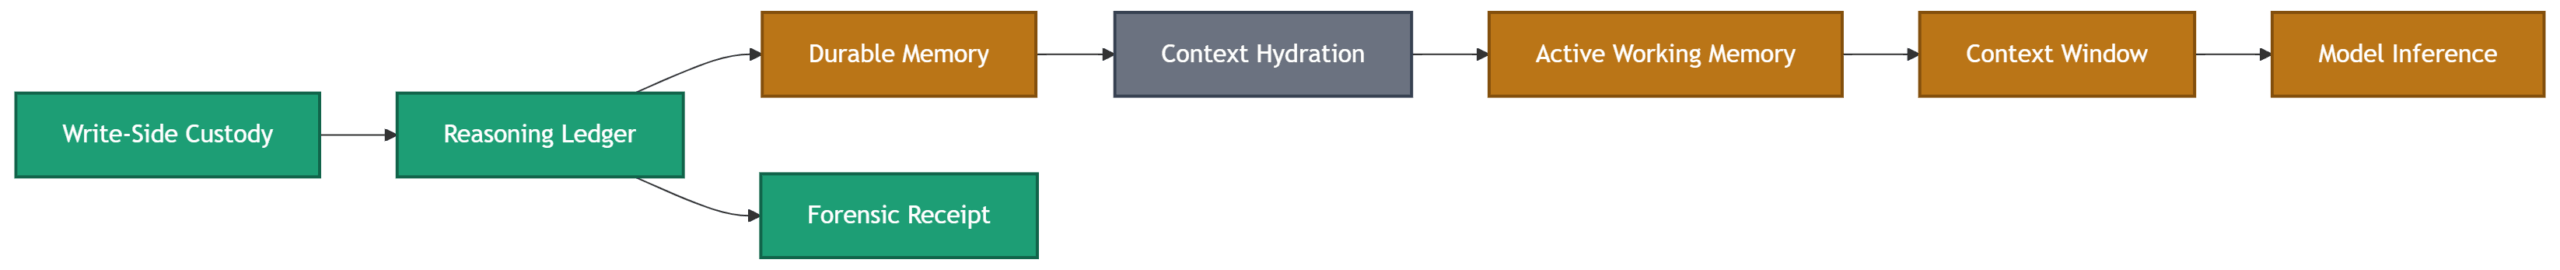
New information first passes through Write-Side Custody, where it is sieved and evaluated before becoming institutional knowledge. The reasoning behind the decision is recorded in the Reasoning Ledger, that record is sealed with a Forensic Receipt, and the verified knowledge is committed to Durable Memory. Later, Context Hydration reconstructs only the verified information required for the current task, placing it into Active Working Memory before it reaches the Context Window.
Teaching order optimizes understanding.
Runtime order optimizes execution.
From Architecture to Implementation
Throughout this series the discussion has intentionally remained architecture-first. None of these responsibilities require a particular programming language, framework, model provider, or database.
Architectures should outlive implementations.
Implementations are how architectures prove themselves.
The Sovereign SDK is intended to be a reference implementation of the Sovereign Systems Specification rather than a single monolithic AI framework. Instead of hiding every responsibility behind one package, it decomposes the architecture into focused components that mirror the boundaries defined by the specification.
That distinction matters.
The SDK is not the specification.
It is one implementation of it.
Responsibilities Become Components
The reference SDK organizes these responsibilities along the information lifecycle, from the moment an observation is captured to the moment it informs reasoning. Each package owns one boundary in that progression.
| Stage | Package | Status | Purpose |
|---|---|---|---|
| Capture | sovereign-sdk-sensor |
Active | Capture observations at the Point of Genesis |
| Classification | sovereign-sdk-edge |
Active | Route, classify, and preserve locality |
| Optimization | sovereign-sdk-sieve |
Active | Reduce Prose Tax while preserving meaning |
| Evidence | sovereign-sdk-ledger |
Active | Generate immutable Forensic Receipts |
| Governance | sovereign-sdk-airlock |
Active | Govern outbound boundary crossings |
| Memory | sovereign-sdk-vault |
Planned | Long-term memory custody and retention |
The responsibilities this series named map onto that lifecycle. The write boundary the series called Write-Side Custody runs across the capture, classification, and optimization stages, where observations are validated and stripped of Prose Tax before they are trusted. Forensic Receipts are minted by the ledger. Outbound governance runs through the airlock. Durable Memory is the vault, the single piece still on the roadmap. Assembly, explanation, and hydration compose these packages in the application layer above them.
You don’t have to take the architecture on faith. The Sovereign Memory Demo, the flagship reference implementation, shows the stack running end to end: audited institutional memory retrieval with local, tamper-evident ledger custody. You can browse it and the demonstrations that follow it from the demos index.
As the SDK grows, packages may change names, implementations will evolve, and new capabilities will emerge. The architectural responsibilities, however, remain stable. A Rust implementation, a Go implementation, or a Java implementation could all faithfully implement the same architecture while looking completely different internally.
That is one of the primary goals of the Sovereign Systems Specification: separating enduring architectural ideas from temporary implementation details.
Earlier in this series we observed that a context window is not memory. The SDK is the architectural consequence of that observation. Rather than trying to solve every problem inside the prompt, it distributes responsibilities across specialized components that preserve, explain, verify, govern, and restore information throughout its lifecycle.
Memory Is Infrastructure
The central argument of this series has never been that prompts are unimportant.
Prompts matter.
Models matter.
Retrieval matters.
What this series argues is that they are only part of a larger system.
Thinking in terms of Memory as Infrastructure changes the design conversation. Instead of asking how to fit more information into a prompt, we begin asking how information should be accepted, preserved, verified, restored, governed, and ultimately communicated back to a model.
Those are architectural questions.
And architectural questions tend to outlive technology cycles.
Final Thoughts
Every generation of software eventually discovers that the difficult problem is not computation.
It is memory.
Databases changed how applications remembered.
Version control changed how teams remembered.
Observability changed how operators remembered.
Artificial intelligence is forcing us to rethink how intelligent systems remember.
Larger context windows are one answer.
Better memory architecture is another.
This series has argued that the second answer will ultimately matter more.
Prompts are temporary.
Memory endures.
The future of AI belongs to systems that remember well.