A companion to Part 4 of the Building the AI Memory Stack series. Part 4.5 of the series.
Part 4 argued that agentic systems need a Reasoning Ledger: a layer that preserves why a decision happened, not just what was decided. The comment thread that followed turned into something more specific and more useful, a working design conversation about what a single ledger record should actually contain. This piece consolidates that. Several of the strongest ideas below arrived from other people, and I have tried to credit them where they land.
The easy version of this article is a schema. Here are the fields, copy them, done.
I want to resist that, because the field list is the least durable thing I could hand you. Implementations differ, field names drift, and a record shape copied without its reasoning becomes cargo-cult structure that nobody maintains. The useful thing is the set of design tensions that decide what belongs in the record and what does not. Get those right and you can derive the fields yourself. Get them wrong and no schema will save you.
So this is principles first, record second. At the end there is a worked record and a field reference, tagged for what is core and what is genuinely optional.
A Starting Point
Here is the baseline record from Part 4. It is a reasonable start and, as the thread quickly established, incomplete in instructive ways.
reasoning_ledger:
  decision: "Approve deployment"
  timestamp: 2026-03-14T09:22:00Z
  evidence:
    - artifact: ADR-014
      authority: architecture-review
      version: 3
    - artifact: security-policy
      authority: security-team
      version: 7
  tools:
    - GitHub
    - CI pipeline
  approvals:
    - release manager
  outcome: approved
Every principle below is, in effect, a thing this record does not yet say.
Principle 1: The Ledger Witnesses, It Does Not Enforce
The first tension is architectural, and it is the one I would defend hardest. A reasoning ledger must not be able to block, veto, or gate the action it records. Its job is to preserve what happened and what evidence surrounded it. The moment the ledger can prevent an action, it stops being an independent witness and becomes part of the mechanism it is supposed to describe, and its own records stop being examinable as neutral fact.
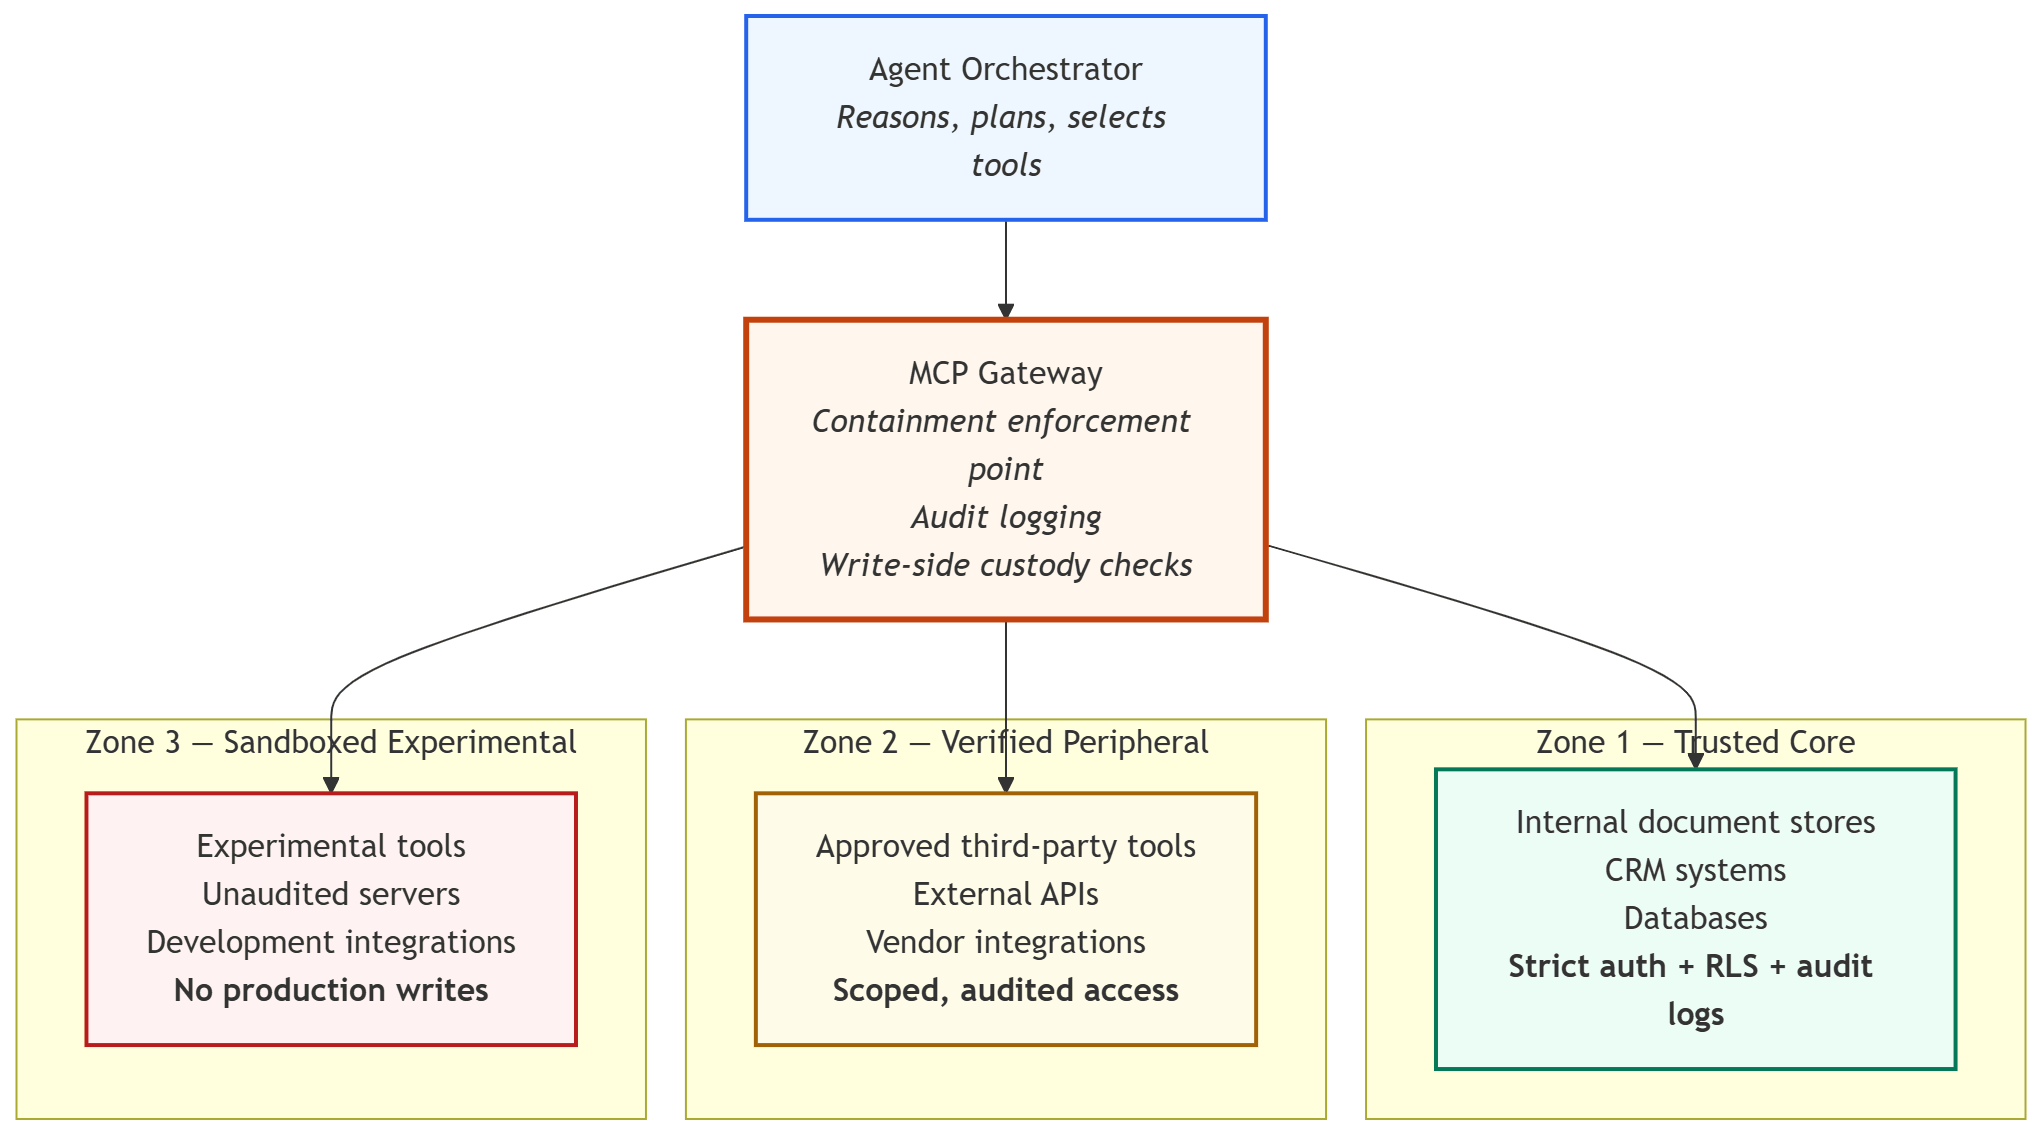
This came up when pm25coder noted, correctly, that a ledger that only narrates can quietly become fiction, and that trust comes from being able to gate rather than merely describe. I agree with the diagnosis and draw the boundary one step earlier: enforcement is real and necessary, but it belongs at the policy and tool boundary, not inside the witness. The ledger preserves that the boundary was evaluated and what it returned. The boundary decides whether the action proceeds.
The practical consequence for the record: a ledger entry can contain a policy_evaluated result showing that a check ran and what it concluded, but it never contains the enforcement decision as its own authority. It reports; it does not rule.
Core. This is not a field, it is a constraint on the whole design.
Principle 2: Supersession Is a New Event, Never a Rewrite
A superseded decision should become a new record that points back at the old one. It should never overwrite the original. “We decided A, and later decided B instead” is two events with a relationship between them, not one field that changed value.
This matters because “wrong now” does not mean “was never decided then.” If you rewrite the March record when you change course in August, you have destroyed the ability to answer whether the March decision was reasonable given what was known in March. The noisier history is the correct trade. Compaction can always produce a clean current-state projection later, but once you have rewritten the historical evidence, you cannot reconstruct it.
This is the same append-only discipline that makes Forensic Receipts useful: preserve what was decided under which evidence and authority, then record the superseding decision as its own event with its own receipt.
Core.
Principle 3: Record How the Authority Was Obtained, Not Just Which One
The baseline record says version: 7. That tells a future reader what supposedly governed. It does not tell them how the system established that version 7 was authoritative at decision time, and those are very different trust claims.
Self-Correcting Systems and pm25coder arrived at this from opposite directions and met in the middle: a policy version fetched fresh from its authority at 09:22, a version read from a five-minute cache, and a version inherited from session state can produce identical version: 7 fields while supporting completely different claims about what the system could reasonably have known. The fix is to treat the authority fetch itself as a recorded event. The record should say which source was consulted, when, what came back, and whether cached state was involved.
This also exposes the sharpest failure mode in the thread, the one an otherwise perfect ledger cannot catch on its own. If the external authority moved to version 8 an hour before your decision and nothing in your system observed that change, the record faithfully captures version 7 and stays perfectly self-consistent. It is a flawless account of a decision that was already wrong when it was made. The record cannot flag this, because there is no edge to preserve; nothing inside the system ever saw the change. Recording how the version was obtained at least lets a later examiner distinguish “we checked and got stale data” from “we never checked.”
Core for the fact of how evidence was obtained. The revalidation mechanism that catches silent version drift lives outside the record, and Principle 7 covers it.
Principle 4: Relationships Need Two Clocks
If you ever want to reconstruct what the system could have known at a past moment, every relationship in the ledger needs two timestamps, not one. This is standard bitemporal modeling, and Giulio D’Erme named exactly why it is not optional here.
Valid time is when a fact was true in the world. Transaction time is when your system asserted or learned the relationship. If a supersession edge carries only a single date, replaying last March will show March’s decision annotated with August’s supersessions, and the decision-maker will look like they ignored a policy that did not yet exist. You will have judged a past decision using knowledge that arrived in the future, which is the precise thing a reasoning ledger exists to prevent.
So a supersession or correction relationship carries both valid_time (when the new state became true) and asserted_at (when the system recorded the edge). Reconstruction filters on asserted_at to see only what was knowable then.
Core for any ledger whose purpose includes reconstructing historical decision context. If you genuinely only ever query current state, you can defer this, but that is a smaller ambition than most of these systems have.
Principle 5: Preserve What Lost, Not Just What Won
A ledger that records only the evidence supporting the final decision is a post-hoc justification engine wearing an audit trail. You can reconstruct why the decision looked reasonable, and you have quietly lost what competed with it, what failed a threshold, and what stayed unresolved.
GnomeMan4201 made this case from the investigation side, and it reframed the record for me. An immutable ledger can preserve history perfectly and still preserve a biased history if the losing evidence never gets written. The distinction between “we chose A because of X” and “we chose A because of X, rejected B because of Y, and could not resolve Z” is enormous when someone later asks whether the decision was defensible given what was actually known.
The fields this implies: alternatives_considered with a rejection_reason for each, disconfirmed_by for evidence that actively cut against the chosen path, and unknowns or scope_limitations for what the system could not resolve at decision time.
A scoping note, in answer to Kartik N V J K, who asked whether to capture rejected branches: capture the alternatives that were explicit parts of the decision process, not an exhaustive reconstruction of every path the model internally considered. If the agent evaluated three tools and rejected two on policy grounds, those rejections are observable decision evidence and belong in the record. The model’s private deliberation does not. Observable reasoning is architecture; private reasoning belongs to the model.
Optional, escalating to Core with stakes. For a low-consequence decision, surviving evidence may be enough. For anything a human will later audit, defend, or be held accountable for, treat these as required. The higher the stakes, the more the losing evidence matters.
Principle 6: The Trigger Is a First-Class Field
pm25coder offered the most immediately practical field in the thread, from running a live decision ledger: the thing people actually read first, months later, is not the outcome. It is what provoked the decision. A timestamped complaint, an incident, a threshold breach, a human request. When every record carries its trigger, “why did we change this” becomes a search rather than an archaeology project, and the audit trail starts writing itself.
It is easy to bury the trigger inside an evidence list. Do not. Promote it to its own field, because it is the field that makes the record findable by the question a future reader will actually bring to it.
Core. Small field, disproportionate value.
Principle 7: Some Things Belong Outside the Record
Two mechanisms the thread kept reaching for are real and necessary, and they do not go in the ledger entry. Naming them keeps the record honest about what it is.
The first is revalidation. A ledger cannot observe a change in the outside world that never entered the system, so something outside the ledger has to periodically re-fetch referenced authorities and emit a fresh observation. pm25coder described this as a periodic “still current” or “stale” marker, which is a clean way to put it. The important framing: the revalidation job runs outside the ledger, and its result becomes a new event the ledger preserves. The ledger never claims continuous authority between checks, only that authority was observed at particular moments.
The second is retrieval. Giulio D’Erme and arun rajkumar converged on the point that a ledger gets read at exactly one moment, when someone is about to change the thing the reasoning was about, and that nobody goes looking for a constraint they have never hit. A well-structured record that is never surfaced is not much better than no record. The fix is to make the decision history an obligation on retrieval rather than an obligation on the reader: when a query surfaces the artifact a decision governed, the decision rides along, asked for or not.
That is what I have started calling separate custody, one interface. The ledger stays independently governed, so it cannot be edited in the same operation that changes what it witnesses. But the retrieval layer reunites the artifact and its decision history when the relationship becomes relevant, so no one has to know the ledger exists to benefit from it. Both properties matter, and they pull in opposite directions, which is exactly why they belong to different layers.
Core as principles, external as mechanisms. Neither is a field in the record.
A Worked Record
Applying the core principles to the baseline, a fuller record looks closer to this. The optional fields from Principle 5 are included and marked, since this is the kind of consequential decision where they earn their place.
reasoning_ledger:
  decision_id: dep-2026-03-14-0922
  decision: "Approve deployment"
  decided_at: 2026-03-14T09:22:00Z

  trigger:                                 # Principle 6
    type: incident
    ref: INC-2291
    observed_at: 2026-03-14T08:55:00Z

  evidence:
    - artifact: ADR-014
      authority: architecture-review
      version: 3
      obtained:                            # Principle 3
        source: adr-service
        method: re-derived
        retrieved_at: 2026-03-14T09:21:40Z
    - artifact: security-policy
      authority: security-team
      version: 7
      obtained:
        source: policy-cache
        method: cached
        retrieved_at: 2026-03-14T09:21:41Z
        cache_age_seconds: 240

  policy_evaluated:                        # Principle 1 (reports, does not rule)
    - check: dirty-tree-guard
      result: pass

  alternatives_considered:                 # Principle 5 (optional, stakes-dependent)
    - option: "Defer to next window"
      rejection_reason: "Incident severity exceeded defer threshold"
  disconfirmed_by: []
  unknowns:
    - "Downstream cache warm state not verified"

  relationships:                           # Principle 4 (two clocks)
    - type: supersedes
      target: dep-2026-02-02-1130
      valid_time: 2026-03-14T09:22:00Z
      asserted_at: 2026-03-14T09:22:00Z

  approvals:
    - release-manager
  outcome: approved
Field Reference
For quick use, here is the same thing as a reference, tagged.
Core fields. decision_id, decision, decided_at, trigger, evidence (with per-item authority, version, and an obtained block recording source, method, and retrieval time), outcome, and, for any relationship, both valid_time and asserted_at.
Optional fields, escalating to core with stakes. alternatives_considered with rejection_reason, disconfirmed_by, unknowns, scope_limitations.
Optional, context-dependent. confidence assessments, tools used, and policy_evaluated results where a boundary check ran. Useful, but not every decision needs them, and an empty one is worse than an absent one.
Not fields at all. Enforcement decisions, revalidation jobs, and integrity guarantees. These are mechanisms that surround the ledger, not contents of the record.
The Honest Limit
It is worth ending where the design genuinely runs out, because pretending otherwise is how ledgers get oversold.
A perfect record can tell you exactly what the system knew and did. It cannot retroactively give the system knowledge it never acquired. If the world changed and no observation of that change ever crossed your boundary, the ledger will contain a flawless, self-consistent account of a decision that was already wrong. Revalidation narrows that gap. It does not close it. Auditability is a property of what was observed, not a guarantee that everything relevant was.
That is not a reason to skip the record. It is a reason to be precise about what the record proves. It witnesses observation, not omniscience.
Looking Ahead
This piece is about what a record should contain and the principles that decide it. It has deliberately said almost nothing about whether the record can be trusted not to have been altered after the fact. That is a separate problem with its own answer, Write-Side Custody, and it is where Part 5 goes next. Designing the record and guaranteeing its integrity are different jobs, and keeping them apart is itself one of the design principles.
With thanks to the commenters whose contributions shaped this: GnomeMan4201 on disconfirming evidence, pm25coder on the trigger field and authority-fetch-as-event, Giulio D’Erme on two clocks and retrieval as an obligation, Self-Correcting Systems on provenance of the version, arun rajkumar on where the record lives, Tae Kim on evidence chains under audit, and Kartik N V J K on rejected branches. The record is better for the argument.