Frameworks Are Institutional Memory

I stored passwords in plaintext on a floppy disk in the 1980s. Recently, a coding agent made a version of the same mistake.

When I was running bulletin board systems in the 1980s, password management could be remarkably straightforward.

A user created an account. They chose a password. The BBS needed to determine whether the password they entered later was the same one they had chosen.

So you stored it.

In plaintext.

On a floppy disk.

Hard drives were expensive and hardly universal in the hobbyist computing world I inhabited, so there was nothing strange about application data living on floppies. The important thing was that the software could retrieve the password and compare it against whatever the user typed the next time they called in.

Something like this was perfectly understandable:

KEN|swordfish
SARAH|password123
MIKE|enterprise

There was, of course, a slight problem.

The person running the BBS could read everybody’s passwords.

So people started solving that. Maybe the password should not be stored exactly as the user entered it. A substitution cipher or some other homegrown transformation could at least stop someone from casually opening the user file and reading every credential.

Problem solved.

Well. One problem solved.

The transformation might be reversible. Two users choosing the same password produced the same stored value. A compromised file exposed everyone at once. Users reused those passwords elsewhere. Password recovery introduced an entirely separate collection of problems.

Each solution exposed another question.

Over the following decades, “store a password” accumulated an extraordinary amount of engineering knowledge.

Today, saying an application needs authentication describes far more than comparing one string against another. It means hashing, salts, password reset, expiring tokens, single-use tokens, session invalidation, account enumeration, brute-force protection, cookie attributes, CSRF, rate limiting, and a long list of other concerns depending on the threat model.

A developer can still build all of that from scratch.

The more interesting question is whether they should.

The Code You Don’t Know You Need

The first thing developers learn about frameworks is that they save us from writing code.

That is true, and it undersells them badly.

A mature framework does not merely contain code somebody else wrote. It contains decisions somebody else already had to make, edge cases somebody else already hit, vulnerabilities somebody else already discovered, and fixes somebody else already learned were necessary.

A mature framework is partly institutional memory encoded as software.

Take authentication. The happy path is not conceptually difficult:

User submits credentials
        ↓
Find account
        ↓
Check password
        ↓
Create session
        ↓
Return success

A relatively inexperienced developer can understand that flow and implement a version of it.

Production authentication is not hard because the happy path is hard. It is hard because of everything surrounding the happy path.

How should the password be stored? What happens after repeated failed attempts? Can an attacker determine whether a username exists by comparing error messages? What happens to existing sessions after a password change? How long should a reset token remain valid? What happens after it is used? Can it be replayed? What attributes belong on the session cookie?

The developer writing authentication for the first time does not necessarily know to ask any of that.

A mature framework often does.

That is a very different kind of value from saving keystrokes.

Abstractions Change Who Has to Think

Software has always progressed partly by taking things that required specialized knowledge and putting them behind abstractions.

Assembly gave me extraordinary control over what the processor did. It was also a tremendous pain. Higher-level languages let us express more sophisticated ideas without manually considering every instruction. C retained substantial control over memory and execution while being far more productive. Later languages and runtimes provided increasingly sophisticated abstractions for memory management, type safety, concurrency primitives, and networking. Libraries and frameworks moved the boundary again. Managed platforms moved it again.

None of those layers made the layer underneath disappear.

Your Python application still causes a processor to execute machine instructions. Your Django application still communicates over networks. Your application on a managed platform still runs on computers somewhere.

What the abstraction changes is who has to think about those things routinely.

Control and Responsibility Arrive Together

Developers sometimes discuss control as though it were an unqualified good.

C gives me more control over memory. Running directly on infrastructure gives me more control than a managed platform. Writing SQL gives me more control than an ORM. Building against browser automation primitives gives me more control than a higher-level testing abstraction.

All of those statements can be true.

But control has a twin that gets mentioned far less often: responsibility.

If you control memory allocation, you are responsible for memory allocation. If you control your infrastructure, you are responsible for configuring, securing, observing, updating, and troubleshooting it. If you control every selector in an end-to-end test suite, you own every selector when the application changes.

You could write your inventory API in C. Manage the networking, parse HTTP, handle allocation, implement routing, serialization, authentication, database connectivity, concurrency, and error handling yourself. You would have an enormous amount of control, and you would have volunteered for an enormous number of problems that Flask, FastAPI, Django, Rails, Spring, and others have spent years making uninteresting.

The trade is not:

abstraction versus control

It is closer to:

less control and less responsibility versus more control and more responsibility

Sometimes the additional control is worth the additional responsibility. Sometimes it is not.
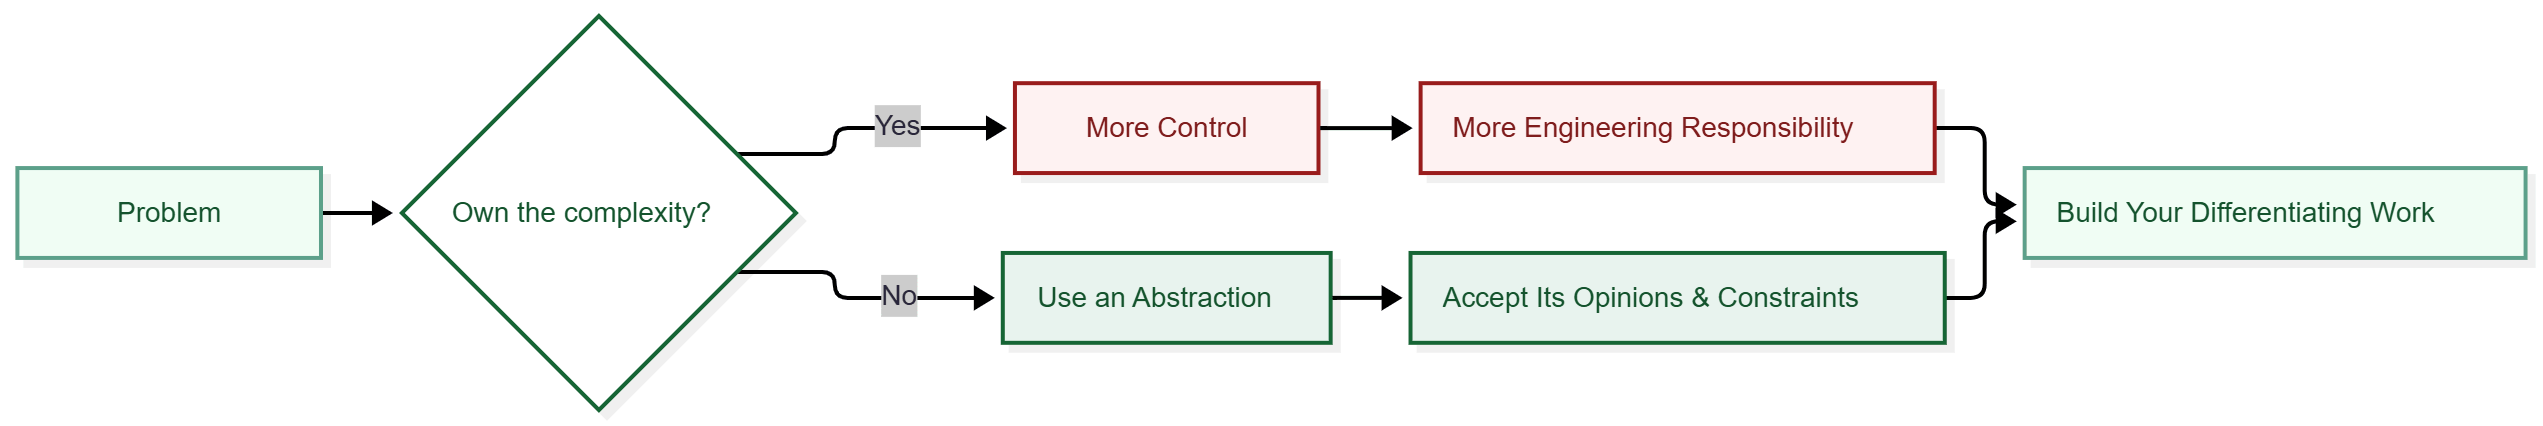
Flowchart showing the choice between owning complexity for greater control and engineering responsibility, or using an abstraction while accepting its opinions and constraints. Both paths lead toward building the work that differentiates the product.

Using the abstraction does not make you less of an engineer. Building the lower layer yourself does not automatically make you a better one. The skill is recognizing which problems deserve your attention, while understanding what you surrendered to have the others solved for you.

Opinions Are Part of the Product

“Opinionated” sometimes gets used as a criticism.

It certainly can be one. If a framework’s opinions conflict with your application’s fundamental requirements, you will spend more time fighting it than benefiting from it.

But an opinion is also a decision you do not have to make. A framework with an established approach to authentication, migrations, forms, routing, validation, sessions, and project structure has removed that many questions from your team’s agenda, and mature defaults usually carry years of accumulated experience with them.

The other side of the bargain is that somebody else has partially decided what your options look like.

Using MongoDB with Django was a long-running example. Django’s data layer was built around assumptions that fit relational databases particularly well, and getting MongoDB underneath it was possible through various third-party approaches, though “interesting” would be a charitable description of that experience. You were making one architectural choice while using a framework whose opinions had been designed around another.

What happened next supports the argument better than the complaint did. MongoDB shipped an official Django backend in public preview in early 2025, and it now handles embedded models, queryable encryption, geospatial lookups, and most of what the third-party packages struggled with. The framework’s opinions were not overturned. They were extended, by people willing to do the work of reconciling the document model with Django’s assumptions.

That took years, and it is exactly the process this whole post is about. The accumulated knowledge is the product. It just accumulates slowly.

So before adopting any framework, do not look only at the complexity it removes. Ask what decisions it makes on your behalf, what assumptions are embedded in those decisions, and how painful things become when your application needs something outside them.

You can dislike the choices. You can replace some of them. You can decide the framework is wrong for you. What matters is understanding the bargain.

Every Platform Sells You Both

Managed platforms made this visible in a way frameworks alone did not.

Before them, deploying an application meant owning a considerable amount of infrastructure knowledge: somewhere to run it, a way to deploy it, process management, configuration, networking, logging, databases, scaling, and monitoring. Managed platforms did not make any of that cease to exist. They changed who had to own it.

What is easy to miss is that this was never a choice between vendors. It is a choice available inside every vendor. AWS will happily sell you App Runner, Elastic Beanstalk, Lambda, or Amplify, and it will just as happily sell you EC2 instances, a VPC, load balancers, autoscaling groups, and a pile of IAM policies to assemble yourself. Google Cloud offers Cloud Run and App Engine alongside Compute Engine and GKE. Azure has App Service and Container Apps on one side, virtual machines and AKS on the other.

Same provider. Same workload. Radically different amounts of responsibility.

The opinionated paths get you running quickly and constrain what you can do. The assembled paths let you build nearly anything and hand you an operational surface that keeps expanding for as long as the system exists. Most real architectures contain both, which is usually the right answer.

The constraint is real in either direction. If you need behavior outside the managed model, the abstraction becomes limiting, and there are plenty of workloads where owning the pieces makes more sense. That is not a failure of the abstraction. It is the trade the abstraction offered.

One asymmetry is worth pricing in advance: the managed path is cheap to enter and expensive to leave. Moving off it means rebuilding the machinery the platform was quietly providing, usually under time pressure, usually at the exact moment the constraint became intolerable. That is not an argument against starting there. It is an argument for knowing which constraint would force the move before you have to make it.

For most teams the question was never whether their engineers could build and operate infrastructure. It was whether infrastructure was what their customers were paying them to be good at.

Spend Your Complexity Budget Wisely

I think of this as a complexity budget.

Every team has finite attention. There are only so many engineers, so many hours, and so many systems a group can deeply understand and maintain. Complexity spends that budget.

Build your own authentication and you have spent some of it on authentication. Operate your own infrastructure and you have spent some of it on infrastructure. Build a custom persistence layer and you have spent some of it on persistence.

Any of those can be excellent investments when the capability differentiates your product or your requirements genuinely demand the control. Dan McKinley’s “Choose Boring Technology” makes a neighboring argument with innovation tokens: you get about three, so spend them where they matter. The complexity budget is the same instinct pointed at what you build rather than what you adopt.

“We could build it ourselves” does not establish anything. Engineers can build lots of things.

The better question is:

Is this where we want to spend our complexity budget?

Learn What’s Underneath Anyway

None of this argues against learning fundamentals. Quite the opposite.

Understanding HTTP makes you better at using a web framework. Understanding SQL makes you better at using an ORM. Understanding memory makes you better at diagnosing what a runtime is doing.

Every abstraction eventually leaks. When it does, knowing what is underneath tells you whether you are looking at a bug, a limitation, a bad assumption, or the consequence of a trade you made a year ago.

But there is a difference between understanding a layer and taking responsibility for operating it.

I do not need to fabricate a processor to understand how one works. I do not need to write an HTTP server in C to understand HTTP. I do not need to implement my own password hashing to understand why plaintext was a bad idea.

Sometimes understanding a problem thoroughly is precisely why you decide not to implement it yourself.

The Password Problem Never Really Went Away

Recently I had a coding agent implement password reset for a small application.

It built the feature in about five minutes. The email arrived. The link opened. The password changed. The user logged in with the new one.

Everything worked.

Except the reset link worked a second time.

The implementation satisfied the obvious behavior while missing the invariant underneath it: once the reset succeeds, the token has to become useless.

That felt familiar.

Forty years ago the question was:

Does the password let the right person log into the BBS?

Yes.

Then somebody asked:

Can the sysop read everyone’s password?

Oh.

Years later:

Is the stored password protected?

Yes.

Can the stored representation be reversed or cheaply cracked?

Oh.

And now:

Does the password reset feature work?

Yes.

Can I reuse the token?

Oh.

The technologies change. The pattern does not. We implement the requirements we know about, and experience introduces us to the ones we did not.

That is why mature abstractions matter. They carry some of that experience forward so the next developer inherits the lesson without personally reliving it. Somebody already hit the edge case. Somebody already found the vulnerability. Somebody already spent three days on the concurrency bug that only appears on Tuesdays.

Which leaves an open question I do not think we have answered yet.

A mature framework carries its institutional memory in its decisions. Sometimes the reasons stay attached through issues, commits, documentation, and design discussions. Often they do not, and only the resulting constraint survives. Either way, somebody encountered the problem and changed the system because of it.

That is the part worth noticing. The single-use token check runs whether or not anyone remembers why it was added. The lesson is enforced rather than remembered.

A model trained on a very large corpus of code has absorbed something that resembles institutional memory. But it learned from artifacts produced after those decisions were made, rather than from the decisions themselves. It can reproduce what surviving code looks like without inheriting anything that enforces why one implementation survived and another did not.

Which might explain why my agent wrote a flawless happy path and dropped the invariant.

Happy paths are abundant. Invariants live in the decisions.

Facebooktwitterredditlinkedinmail

Engineering Agent Memory

From Stateless Prompts to Persistent Intelligence

Where this fits: This article bridges two series. It closes out the themes introduced in The Backyard Quarry — a data engineering exploration using physical objects as a teaching domain — and sets the stage for Sovereign Synapse, an upcoming series on autonomous, memory-aware agentic systems. You can start either series independently, but the arc rewards reading in order.

Eight posts ago, we started with a pile of rocks.

By the end of that series, those rocks had become a recognizable system — a capture layer, an ingestion pipeline, structured records, indexed assets, and finally, applications on top. The architecture that emerged was surprisingly consistent with systems far beyond the backyard: manufacturing, archival, AI.

But there was something that architecture left unresolved.

The data flowed in. The data got indexed. Applications queried it. What the system didn’t do — couldn’t do — was remember across time. Each query was stateless. Each session started fresh.

That’s fine for rocks. Rocks don’t change. A granite specimen catalogued in October is the same granite specimen in March.

AI agents are different.

They’re everywhere right now. But most of them share the same architectural limitation:

They forget.

This is not because AI models are incapable or flawed. It’s because the
applications wrapping them are stateless. As developers, we’ve spent
years designing systems that persist state intentionally through
databases, caches, queues, event logs, etc. Many AI systems, though,
still rely on the simplest memory mechanism possible:

Append previous messages to the prompt and hope it fits.

In the world of demo and sample applications and presentations, this can
work. But it does not scale for production.

Several techniques are used to overcome this architectural limitation,
and the folks at Oracle have some interesting examples. Their GitHub
repo,
oracle-ai-developer-hub
showcases some different approaches. Through Jupyter notebooks like
memory_context_engineering_agents.ipynb
and RAG examples, Agent memory stops being a feature and becomes an
engineering discipline.

Let’s dive into why this shift towards Agent memory matters and how
developers can apply these patterns in real systems.

The Core Problem: Stateless by Default

Most Large Language Model (LLM) APIs operate in a stateless fashion,
such as this:

response = llm.generate(
     prompt = "User: What did I ask earlier? \n Assistant:"
)

If the application doesn’t include context from a previous interaction
explicitly, the model has no knowledge of it. A common workaround might
be something like:

conversation_history.append(user_message)
response = llm.generate(
    prompt="\n".join(conversation_history)
)

This seems like a reasonable approach, but there are some considerations
to keep in mind. What happens when:

  • The conversation exceeds token limits?
  • Retrieval becomes excessively expensive?
  • Cross-session persistence becomes complicated?
  • Irrelevant history pollutes reasoning?

The problem isn’t prompt size. The problem is a lack of a structured
memory architecture.

Memory as Architecture, Not Transcript

The Oracle AI Developer Hub notebook on memory engineering demonstrates
a critical shift:

Memory should be stored, indexed, and retrieved intentionally.

Instead of storing everything, we extract and persist what matters.

If we think in database terms and architecture:

  • We don’t index every column.
  • We index based on query patterns.
  • We normalize based on access needs.

Agent memory requires similar thinking.

Memory Types Developers Should Design For

When transitioning to an Agentic memory architecture, designing for and
considering different memory categories is critical.

  1. Working Memory (Short-Term)

Scope: current execution cycle

Examples:

  • Tool Outputs.
  • Active reasoning steps.
  • Immediate user goal.

Often held in a runtime state.

  1. Semantic Memory (Long-Term Knowledge)

Scope: cross-session persistence

Examples:

  • User preferences.
  • Stored documents.
  • Embedded knowledge fragments.

Often stored in:

  • Vector databases.
  • Relational databases.
  • Hybrid systems.
  1. Episodic Memory (Historical Experience)

Scope: prior actions and outcomes

Examples:

  • “User prefers JSON responses.”
  • “Last deployment failed due to timeout.”
  • “This customer escalated twice.”

Stored as structured events.

The Oracle AI Developer Hub repository’s notebook walks through how to
combine these into an integrated agent memory system rather than a
simple, flat transcript.

A Practical Memory Pattern

Let’s take a look at a simplified example inspired by patterns
demonstrated in the notebook.

Step 1: Extract Memory Worth Keeping

Instead of storing everything, summarize and structure

def extract_memory(interaction):
     return {
          "type": "preference",
          "content": interaction["assistant_summary"],
          "metadata": {
               "user_id": interaction["user_id"],
               "timestamp": interaction["timestamp"]
          }
     }

Step 2: Embed and Store

embedding = embed_model.encode(memory["content"])
vector_store.add(
     id=uuid4(),
     vector=embedding,
metadata=memory["metadata"]
)

Memory is now searchable, making it much more useful for the LLM. While
this example uses a generic vector store, Oracle Database
26ai
supports this storage and indexing
natively using the VECTOR data type.

Step 3: Retrieve When Relevant

query_vector = embed_model.encode(current_query)
relevant_memories = vector_store.search(
    vector=query_vector,
    top_k=3
)

Step 4: Inject Into Context Intentionally

memory_context = "\n".join(
     [m["content"] for m in relevant_memories]
)

prompt = f"""
Relevant prior context:
{memory_context}

User query:
{current_query}
"""

Notice what’s happening with this architectural design:

  • We are not replaying history.
  • We are retrieving relevance.
  • Memory becomes a queryable state.

That is a foundational shift.

Architecture Flow: Memory-Aware Agent

Architecturally, here’s what’s happening:

flowchart LR

    %% --- User Interaction ---
    U[User Input]

    %% --- Retrieval Layer ---
    subgraph Retrieval Layer
        E[Generate Embedding]
        R[Retrieve Relevant Memory]
    end

    %% --- Reasoning Layer ---
    subgraph Reasoning Layer
        LLM[LLM Processing]
        X[Extract New Memory]
    end

    %% --- Persistence Layer ---
    subgraph Persistence Layer
        V[(Vector Store / Database)]
    end

    %% --- Flow ---
    U --> E
    E --> R
    R --> LLM
    LLM --> X
    X --> V

    %% --- Feedback Loop
    V --> R

This becomes a lifecycle, not a static system, with the database not being the end of the pipeline but part of the reasoning cycle.

RAG is Memory

The Oracle AI Developer Hub also provides several examples of
Retrieval-Augmented Generation (RAG). Many developers think of RAG as
“document Q&A”. However, RAG has many architectural similarities to the
Agent Memory architecture we’ve outlined. RAG is semantic memory.

When used intentionally, RAG can become:

  • A recall function.
  • A knowledge retrieval system.
  • A memory lookup service.

The Oracle AI Developer Hub repository has some excellent examples
demonstrating how to:

  • Embed content.
  • Store vectors.
  • Retrieve context.
  • Inject selectively.

The key takeaway for developers:

RAG isn’t a feature. It’s a memory primitive

So far, we’ve looked at memory from an architectural standpoint. But
architecture only matters if it can survive production realities —
scale, concurrency, security, and governance. That’s where
infrastructure choices start to matter.

The 26ai Advantage: Memory at Scale

Transitioning from a notebook to production requires a database that
understands vectors as first-class citizens. Oracle Database 26ai serves
as the backbone for this architecture through AI Vector Search. By
utilizing the native VECTOR data type and specialized indexes like HNSW,
developers can execute similarity searches across millions of “memories”
in milliseconds — all while maintaining the security and ACID
compliance of an enterprise database. An example might look something
like:

CREATE TABLE agent_memory (
    id NUMBER GENERATED BY DEFAULT AS IDENTITY,
    user_id VARCHAR2(100),
    content CLOB,
    embedding VECTOR(1536),
    created_at TIMESTAMP
)

Memory Governance and Security

In an enterprise environment, “forgetting” isn’t the only risk.
“Remembering too much” or “remembering the wrong things for the wrong
user” is a critical security concern. As agents move from isolated demos
to multi-user production systems, memory governance becomes the
gatekeeper of data integrity.

Permissioned Recall with Row-Level Security (RLS)

One of the primary challenges in agentic architecture is ensuring that
an agent’s semantic memory doesn’t become a back channel for
unauthorized data access. Oracle AI Database 26ai addresses this through
native Row-Level Security (RLS).

By applying security policies directly to the VECTOR table, the database
ensures that when an agent queries for “relevant memories”, the result
set is automatically filtered based on the current user’s identity. The
agent never “sees” memory fragments it isn’t authorized to retrieve,
preventing privilege escalation at the prompt level.

Auditing the “Thought Process”

Governance also requires accountability. Because Oracle 26ai treats
memory as a queryable state, every retrieval action can be logged and
audited using standard database tools. Developers can track exactly
which memory fragments were injected into a prompt and when, providing a
transparent audit trail for compliance and debugging.

Quantum-Resistant Protection

As we look towards the future of computing, the security of stored
embeddings is paramount. Oracle 26ai
incorporates

quantum-resistant
algorithms

to protect data at rest and in transit, ensuring that even as decryption
technologies evolve, the proprietary knowledge stored in an agent’s
semantic memory remains secure.

Trade-Offs in Agent Memory Design

As with most things in system architecture, there are trade-offs. Let’s
look at some of the real-world considerations that developers must weigh
for Agent Memory systems.

Storage Strategy

Options Include:

  • Filesystem persistence.
  • Relational database.
  • Vector database.
  • Hybrid approach.

Each choice affects:

  • Durability.
  • Performance.
  • Query flexibility.
  • Operational complexity.
  • Cost.

Retrieval Precision vs Recall

If you retrieve too much:

  • Prompts get noisy.
  • Costs increase.
  • Responses degrade.

If you retrieve too little:

  • The agent forgets the important context.

Much like prompt engineering, memory engineering requires tuning.

Cost Implications

Embedding every interaction may be wasteful.

A better approach could be:

  • Extract structured summaries.
  • Store selectively.
  • Prune low-value memory.

Sound familiar? It mirrors many log retention policies in traditional
systems.

Multi-Agent Systems: Shared Memory as Coordination

As multi-agent systems become more common and refined, memory becomes
even more critical in multi-agent workflows:

Agent A: Research
Agent B: Plan
Agent C: Execute

Without a shared memory system in place:

  • Agents duplicate effort.
  • Decisions aren’t tracked.
  • Coordination becomes fragile.

With a structured memory architecture:

  • Agents retrieve shared state.
  • Decisions persist across steps.
  • Workflow continuity improves.

The Oracle AI Developer Hub repository’s patterns make this possible by
treating memory as infrastructure.

Memory Lifecycle Diagram

Let’s take a look at a sample memory lifecycle:

stateDiagram-v2
  [*] --> Input: User Query
  Input --> Retrieval: Vector Search (User-Scoped Semantic Memory)
  Retrieval --> Audit: Log Retrieval Event 
  Audit --> Reasoning: LLM Processing
  Reasoning --> Response: Deliver Answer
  Response --> Extraction: Extract Structured Memory
  Extraction --> Persistence: Store in Oracle 26ai
  Persistence --> Retrieval: Future Similarity Search

This lifecycle reinforces the iterative, evolving nature of memory.

Developer Adoption Path

As a developer or a development team building AI applications, where
should one start? Often, the progression is similar to:

  1. Prompt experimentation.
  2. Basic RAG integration.
  3. Tool-augmented agents.
  4. Memory-aware architecture.
  5. Production systems.

If we revisit the Oracle AI Developer
Hub
, we see
that it supports steps 2-4 particularly well.

Developers can:

  • Study memory notebooks.
  • Implement retrieval patterns.
  • Adapt reference applications.
  • Integrate with enterprise storage.

This accelerates the path from curiosity to capability.

Why This Matters

As we move into a more Agentic world and find ourselves leveraging
agents and LLMs for more and more tasks, we’re discovering that Agent
memory can’t be cosmetic. It becomes mission-critical and enables:

  • Personalization.
  • Long-running workflows.
  • Contextual automation.
  • Stateful enterprise systems.
  • Reduced recomputation.

Without memory, agents remain impressive demos.

With memory, they become systems.

Engineering the Future of Agents

As developers, we have long known that durable systems require, among
other things:

  • Intentional persistence.
  • Indexed retrieval.
  • Thoughtful lifecycle management.

Agent memory deserves the same rigor and, in fact, requires it.

The Oracle AI Developer Hub demonstrates that memory-aware agents are
not research curiosities. They are buildable today using structured
patterns. Patterns software developers have been using for years.

Ready to build a memory-aware agent?

For developers exploring the next phase of AI architecture, memory is
not optional.

It is foundational.

And the tools to engineer it are already available.

Final Thoughts

Agent memory isn’t a feature. It’s the foundation that separates impressive demos from systems that actually work across time.

We’ve spent considerable time in this series thinking about getting data into systems — capture, transformation, indexing, retrieval. Memory-aware agents flip that problem: now the system itself needs to accumulate, select, and retrieve what matters. The architecture looks familiar because it is familiar. Same instincts, new domain.

That instinct — treating intelligence as infrastructure — points toward something worth exploring next. What happens when agents aren’t just memory-aware, but sovereign? When they don’t just recall context, but maintain persistent goals, coordinate with other agents, and operate with a degree of autonomy that starts to look less like a tool and more like a collaborator?

That’s where we’re headed.

Facebooktwitterredditlinkedinmail