Your Metric Is Not Your State

What a refractometer taught me about observability

In July, I wrote about a farmer walking a vineyard row at dawn, crushing a grape onto a refractometer prism, and typing “13.5 Brix” into a chat window. The agent on the other end didn’t care how the number arrived. To the Digital Scribe, I wrote, a number is just a number.

In the vineyard, that’s a defensible position. Fresh grape juice is exactly what a refractometer is built to read.

This fall, I’ve been pointing the same kind of instrument at juice that’s fermenting. It turns out the agent should have cared.

Three batches and a prism

Over the last several weeks I’ve started three small batches: a blackberry wine that’s now bulk aging, a pear wine that began fermenting on September 24, and a fireweed honey mead that got its yeast two days later. They’re one-gallon batches, which matters for this story, because at that size every sample you pull is wine you don’t get to drink and oxygen you’ve let in.

So I track them with a refractometer. A few drops of liquid on a glass prism, close the cover, hold it up to the light, read a number off the scale. The number is Brix, roughly the percentage of dissolved sugar. It’s fast, cheap, and costs a few drops per reading. During the blackberry’s primary fermentation I took readings twice a day, every time I punched down the cap of fruit.

And once fermentation starts, the refractometer is wrong.

The instrument isn’t lying, exactly

A refractometer measures how much light bends as it passes through a liquid. Dissolved sugar bends light, so in fresh juice the amount of bending is a good proxy for the amount of sugar. The scale on the instrument is calibrated on that assumption.

Fermentation breaks the assumption. Yeast converts sugar into alcohol, and alcohol bends light too. A few days into primary, the refractometer is reporting the combined effect of the sugar that remains and the alcohol that’s been produced, and presenting all of it as sugar. The reading comes out higher than the real sugar content. Taken at face value, it says the fermentation is further behind than it actually is.

To get something usable, you run each reading through a correction formula. Most home winemakers use calculators built on formulas originally developed for brewing, and every one of them needs the same extra input: the original reading, taken before the yeast went in.

Here’s what that looked like on the blackberry:

Day Raw refractometer (Brix) Corrected value
08/29/2026 20.7 20.7
08/30/2026 18.4 16.5
08/30/2026 17.0 14.3
08/31/2026 13.2 8.1
08/31/2026 10.8 4.1
09/01/2026 8.7 0.7
09/01/2026 8.3 0.1

Nothing is malfunctioning. The instrument is doing exactly what it was built to do. What changed is the system it’s pointed at, and a number that was a reliable proxy in one state became a misleading one in the next.

Neither instrument measures sugar

The traditional alternative is a hydrometer, a weighted glass float. The deeper it sinks, the less dense the liquid. Sugar makes liquid denser, so falling specific gravity means sugar is being consumed.

Except the hydrometer doesn’t measure sugar either. It measures density, and alcohol is less dense than water, so as fermentation proceeds the alcohol pulls the reading down on its own. A finished dry wine routinely reads below 1.000, lower than plain water, which would be impossible if the hydrometer were really a sugar meter.

So the refractometer measures how light bends and the hydrometer measures how heavy the liquid is. Neither measures what I actually care about: how much sugar is left, whether the yeast is still working, whether this wine is done. I infer those. The instruments give me evidence.

Even a steady reading is ambiguous. The traditional sign that fermentation has finished is the same reading several days running. But a fermentation that has stalled also produces the same reading several days running. Mead is notorious for this: honey has very little natural buffering, the pH drifts down as fermentation proceeds, and the yeast can slow or stop well short of dry. A flat line can mean done or stuck, and the instrument can’t tell you which. You tell them apart with other evidence: where the line flattened, what the pH is doing, what you expected to see.

That distinction between evidence and state sounds pedantic until you notice it’s one we get wrong in software constantly.

Your dashboard has the same problem

CPU utilization isn’t health. A service at 15% CPU can be deadlocked, and one at 90% can be doing exactly what you want. An HTTP 200 isn’t correctness; it tells you the server returned a response, not that the response was right. A green health check tells you the health check endpoint answered. Model confidence isn’t truth; it’s a number the model produced about its own output.

Each of these started as a reasonable proxy under a particular set of conditions. Then the system changed, a new failure mode appeared, or someone started optimizing the number itself, and the proxy drifted away from the state it was meant to represent. The dashboard kept rendering it with exactly the same authority.

That’s the refractometer problem. The metric was calibrated for one state of the system and is now being read in another, and nothing on the display tells you so. And like the flat fermentation line, a steady metric can mean two opposite things: a quiet error rate might mean a healthy service, or one that stopped receiving traffic an hour ago.

The failure isn’t collecting the metric. It’s treating the metric as the state instead of as evidence about the state.

A reading needs its history

Back to that correction formula. To interpret today’s reading, you need the reading from before fermentation began. Without it, the current number is close to uninterpretable. The same Brix value could describe a fermentation that has barely started or one that’s nearly finished, depending entirely on where it began.

The meaning of a measurement depends on its lineage.

This is where I think observability practice most often falls short. We store the value and the timestamp and call it a record. What we usually drop is everything needed to interpret it later: which instrument produced it, under what conditions, what calibration assumptions it carried, what baseline it should be read against, and what state the system was believed to be in at the time.

My fermentation log keeps the raw reading and the corrected value side by side. The corrected value is what I act on. The raw value is what I re-derive from if I later learn the correction was off, find a better formula, or discover I misread the original. A corrected value on its own is a conclusion with its evidence thrown away.

That’s a pattern worth stealing. Store the observation separately from the interpretation. Keep the provenance that makes the observation meaningful. Let state be something you derive, with its evidence attached, rather than something you overwrite. It’s the same idea behind the forensic receipt work I’ve been doing: a claim should carry what it was based on.

Watching isn’t free

One more thing the one-gallon batches have taught me. I use a refractometer because a hydrometer needs a much larger sample, and in a small carboy that sample is a real fraction of the batch, and pulling it lets oxygen in. The act of measuring changes the system being measured.

It also means deciding how often to look. The blackberry had to be punched down twice a day anyway, so twice-daily readings were free. The pear and the mead don’t need that kind of handling, so I’ve settled on a reading every couple of days: often enough to catch a stall, rare enough to leave the batch alone. That’s a measurement policy, and it means my log has deliberate gaps in it. Those gaps are their own story, and I’ll come back to them.

Software has the same trade-off: tracing overhead, probes that add latency, sampling that shifts timing. Usually the effect is small. Sometimes it isn’t, and how often to look is a design decision with costs on both sides.

Evidence, then state

Here’s what I’ve taken from a few weeks of squinting at a prism.

Separate what you observed from what you concluded. “The refractometer read 9 Brix” and “fermentation is about two-thirds done” are different kinds of statement. They belong in different places, and they should be allowed to disagree.

Keep the raw reading. Corrections, normalizations, and aggregations are interpretations. If you keep only the interpreted value, you can never revisit the interpretation.

Record the conditions that make a reading meaningful. Instrument, baseline, calibration assumptions, the believed state of the system. A metric without its context is a number waiting to be misread.

Treat state as a derived claim. “Fermentation is complete” isn’t a reading. It’s a conclusion drawn from several readings over time, plus whatever evidence rules out “stuck,” and it should be traceable back to all of it.

Notice when your proxy stops being a proxy. Every metric was calibrated for some range of system behavior. When the system leaves that range, the metric keeps reporting with exactly the same confidence.

The agent in July was right about one thing: it shouldn’t matter whether a number comes from a clipboard or a five-thousand-dollar probe. Where it was wrong was in believing the number could travel without its history.

The pear wine is still in primary as I write this. The raw refractometer reading says it has a long way to go. The corrected number says otherwise, and the corrected number is only trustworthy because I wrote down what the juice read before the yeast went in.

The number on the instrument isn’t the system. It never was.

Facebooktwitterredditlinkedinmail

Frameworks Are Institutional Memory

I stored passwords in plaintext on a floppy disk in the 1980s. Recently, a coding agent made a version of the same mistake.

When I was running bulletin board systems in the 1980s, password management could be remarkably straightforward.

A user created an account. They chose a password. The BBS needed to determine whether the password they entered later was the same one they had chosen.

So you stored it.

In plaintext.

On a floppy disk.

Hard drives were expensive and hardly universal in the hobbyist computing world I inhabited, so there was nothing strange about application data living on floppies. The important thing was that the software could retrieve the password and compare it against whatever the user typed the next time they called in.

Something like this was perfectly understandable:

KEN|swordfish
SARAH|password123
MIKE|enterprise

There was, of course, a slight problem.

The person running the BBS could read everybody’s passwords.

So people started solving that. Maybe the password should not be stored exactly as the user entered it. A substitution cipher or some other homegrown transformation could at least stop someone from casually opening the user file and reading every credential.

Problem solved.

Well. One problem solved.

The transformation might be reversible. Two users choosing the same password produced the same stored value. A compromised file exposed everyone at once. Users reused those passwords elsewhere. Password recovery introduced an entirely separate collection of problems.

Each solution exposed another question.

Over the following decades, “store a password” accumulated an extraordinary amount of engineering knowledge.

Today, saying an application needs authentication describes far more than comparing one string against another. It means hashing, salts, password reset, expiring tokens, single-use tokens, session invalidation, account enumeration, brute-force protection, cookie attributes, CSRF, rate limiting, and a long list of other concerns depending on the threat model.

A developer can still build all of that from scratch.

The more interesting question is whether they should.

The Code You Don’t Know You Need

The first thing developers learn about frameworks is that they save us from writing code.

That is true, and it undersells them badly.

A mature framework does not merely contain code somebody else wrote. It contains decisions somebody else already had to make, edge cases somebody else already hit, vulnerabilities somebody else already discovered, and fixes somebody else already learned were necessary.

A mature framework is partly institutional memory encoded as software.

Take authentication. The happy path is not conceptually difficult:

User submits credentials
        ↓
Find account
        ↓
Check password
        ↓
Create session
        ↓
Return success

A relatively inexperienced developer can understand that flow and implement a version of it.

Production authentication is not hard because the happy path is hard. It is hard because of everything surrounding the happy path.

How should the password be stored? What happens after repeated failed attempts? Can an attacker determine whether a username exists by comparing error messages? What happens to existing sessions after a password change? How long should a reset token remain valid? What happens after it is used? Can it be replayed? What attributes belong on the session cookie?

The developer writing authentication for the first time does not necessarily know to ask any of that.

A mature framework often does.

That is a very different kind of value from saving keystrokes.

Abstractions Change Who Has to Think

Software has always progressed partly by taking things that required specialized knowledge and putting them behind abstractions.

Assembly gave me extraordinary control over what the processor did. It was also a tremendous pain. Higher-level languages let us express more sophisticated ideas without manually considering every instruction. C retained substantial control over memory and execution while being far more productive. Later languages and runtimes provided increasingly sophisticated abstractions for memory management, type safety, concurrency primitives, and networking. Libraries and frameworks moved the boundary again. Managed platforms moved it again.

None of those layers made the layer underneath disappear.

Your Python application still causes a processor to execute machine instructions. Your Django application still communicates over networks. Your application on a managed platform still runs on computers somewhere.

What the abstraction changes is who has to think about those things routinely.

Control and Responsibility Arrive Together

Developers sometimes discuss control as though it were an unqualified good.

C gives me more control over memory. Running directly on infrastructure gives me more control than a managed platform. Writing SQL gives me more control than an ORM. Building against browser automation primitives gives me more control than a higher-level testing abstraction.

All of those statements can be true.

But control has a twin that gets mentioned far less often: responsibility.

If you control memory allocation, you are responsible for memory allocation. If you control your infrastructure, you are responsible for configuring, securing, observing, updating, and troubleshooting it. If you control every selector in an end-to-end test suite, you own every selector when the application changes.

You could write your inventory API in C. Manage the networking, parse HTTP, handle allocation, implement routing, serialization, authentication, database connectivity, concurrency, and error handling yourself. You would have an enormous amount of control, and you would have volunteered for an enormous number of problems that Flask, FastAPI, Django, Rails, Spring, and others have spent years making uninteresting.

The trade is not:

abstraction versus control

It is closer to:

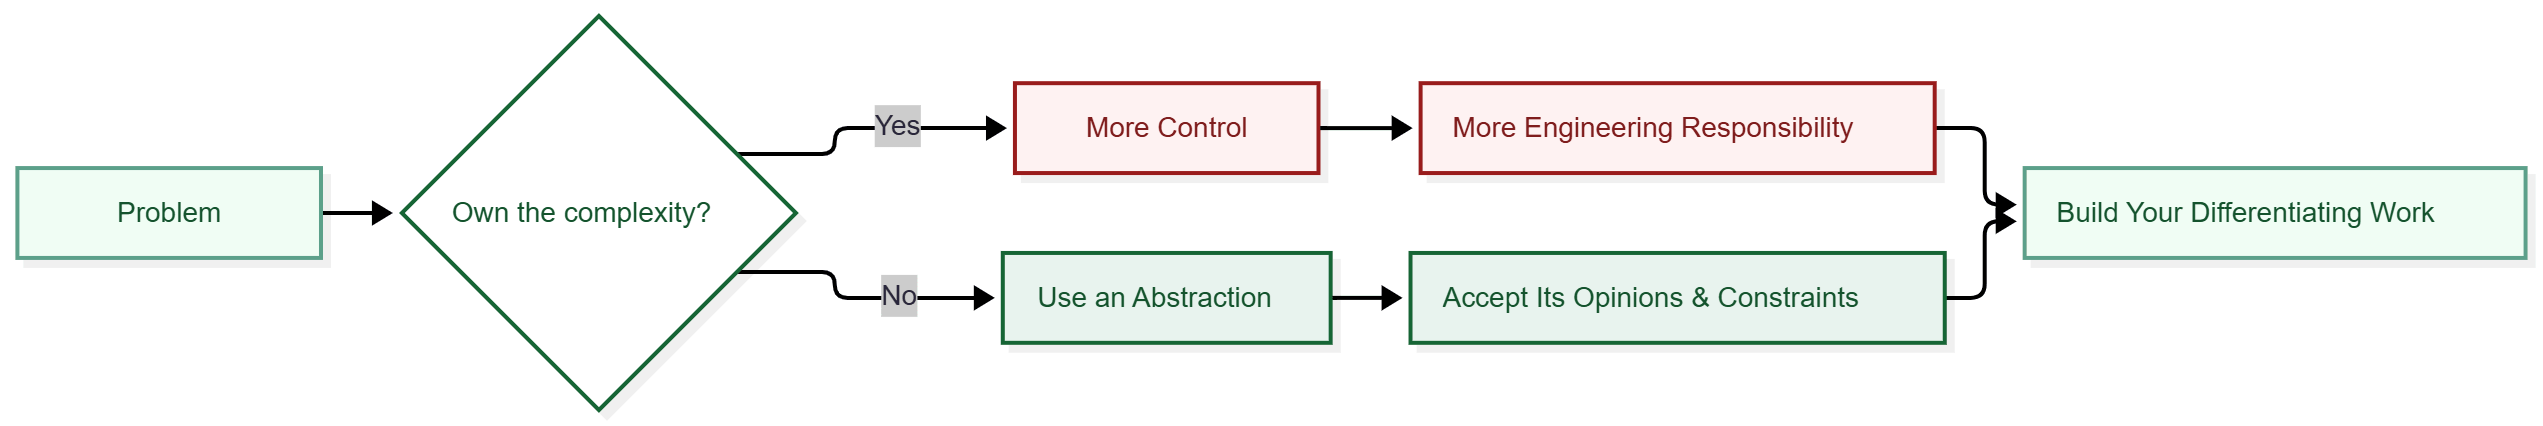
less control and less responsibility versus more control and more responsibility

Sometimes the additional control is worth the additional responsibility. Sometimes it is not.

Flowchart showing the choice between owning complexity for greater control and engineering responsibility, or using an abstraction while accepting its opinions and constraints. Both paths lead toward building the work that differentiates the product.

Using the abstraction does not make you less of an engineer. Building the lower layer yourself does not automatically make you a better one. The skill is recognizing which problems deserve your attention, while understanding what you surrendered to have the others solved for you.

Opinions Are Part of the Product

“Opinionated” sometimes gets used as a criticism.

It certainly can be one. If a framework’s opinions conflict with your application’s fundamental requirements, you will spend more time fighting it than benefiting from it.

But an opinion is also a decision you do not have to make. A framework with an established approach to authentication, migrations, forms, routing, validation, sessions, and project structure has removed that many questions from your team’s agenda, and mature defaults usually carry years of accumulated experience with them.

The other side of the bargain is that somebody else has partially decided what your options look like.

Using MongoDB with Django was a long-running example. Django’s data layer was built around assumptions that fit relational databases particularly well, and getting MongoDB underneath it was possible through various third-party approaches, though “interesting” would be a charitable description of that experience. You were making one architectural choice while using a framework whose opinions had been designed around another.

What happened next supports the argument better than the complaint did. MongoDB shipped an official Django backend in public preview in early 2025, and it now handles embedded models, queryable encryption, geospatial lookups, and most of what the third-party packages struggled with. The framework’s opinions were not overturned. They were extended, by people willing to do the work of reconciling the document model with Django’s assumptions.

That took years, and it is exactly the process this whole post is about. The accumulated knowledge is the product. It just accumulates slowly.

So before adopting any framework, do not look only at the complexity it removes. Ask what decisions it makes on your behalf, what assumptions are embedded in those decisions, and how painful things become when your application needs something outside them.

You can dislike the choices. You can replace some of them. You can decide the framework is wrong for you. What matters is understanding the bargain.

Every Platform Sells You Both

Managed platforms made this visible in a way frameworks alone did not.

Before them, deploying an application meant owning a considerable amount of infrastructure knowledge: somewhere to run it, a way to deploy it, process management, configuration, networking, logging, databases, scaling, and monitoring. Managed platforms did not make any of that cease to exist. They changed who had to own it.

What is easy to miss is that this was never a choice between vendors. It is a choice available inside every vendor. AWS will happily sell you App Runner, Elastic Beanstalk, Lambda, or Amplify, and it will just as happily sell you EC2 instances, a VPC, load balancers, autoscaling groups, and a pile of IAM policies to assemble yourself. Google Cloud offers Cloud Run and App Engine alongside Compute Engine and GKE. Azure has App Service and Container Apps on one side, virtual machines and AKS on the other.

Same provider. Same workload. Radically different amounts of responsibility.

The opinionated paths get you running quickly and constrain what you can do. The assembled paths let you build nearly anything and hand you an operational surface that keeps expanding for as long as the system exists. Most real architectures contain both, which is usually the right answer.

The constraint is real in either direction. If you need behavior outside the managed model, the abstraction becomes limiting, and there are plenty of workloads where owning the pieces makes more sense. That is not a failure of the abstraction. It is the trade the abstraction offered.

One asymmetry is worth pricing in advance: the managed path is cheap to enter and expensive to leave. Moving off it means rebuilding the machinery the platform was quietly providing, usually under time pressure, usually at the exact moment the constraint became intolerable. That is not an argument against starting there. It is an argument for knowing which constraint would force the move before you have to make it.

For most teams the question was never whether their engineers could build and operate infrastructure. It was whether infrastructure was what their customers were paying them to be good at.

Spend Your Complexity Budget Wisely

I think of this as a complexity budget.

Every team has finite attention. There are only so many engineers, so many hours, and so many systems a group can deeply understand and maintain. Complexity spends that budget.

Build your own authentication and you have spent some of it on authentication. Operate your own infrastructure and you have spent some of it on infrastructure. Build a custom persistence layer and you have spent some of it on persistence.

Any of those can be excellent investments when the capability differentiates your product or your requirements genuinely demand the control. Dan McKinley’s “Choose Boring Technology” makes a neighboring argument with innovation tokens: you get about three, so spend them where they matter. The complexity budget is the same instinct pointed at what you build rather than what you adopt.

“We could build it ourselves” does not establish anything. Engineers can build lots of things.

The better question is:

Is this where we want to spend our complexity budget?

Learn What’s Underneath Anyway

None of this argues against learning fundamentals. Quite the opposite.

Understanding HTTP makes you better at using a web framework. Understanding SQL makes you better at using an ORM. Understanding memory makes you better at diagnosing what a runtime is doing.

Every abstraction eventually leaks. When it does, knowing what is underneath tells you whether you are looking at a bug, a limitation, a bad assumption, or the consequence of a trade you made a year ago.

But there is a difference between understanding a layer and taking responsibility for operating it.

I do not need to fabricate a processor to understand how one works. I do not need to write an HTTP server in C to understand HTTP. I do not need to implement my own password hashing to understand why plaintext was a bad idea.

Sometimes understanding a problem thoroughly is precisely why you decide not to implement it yourself.

The Password Problem Never Really Went Away

Recently I had a coding agent implement password reset for a small application.

It built the feature in about five minutes. The email arrived. The link opened. The password changed. The user logged in with the new one.

Everything worked.

Except the reset link worked a second time.

The implementation satisfied the obvious behavior while missing the invariant underneath it: once the reset succeeds, the token has to become useless.

That felt familiar.

Forty years ago the question was:

Does the password let the right person log into the BBS?

Yes.

Then somebody asked:

Can the sysop read everyone’s password?

Oh.

Years later:

Is the stored password protected?

Yes.

Can the stored representation be reversed or cheaply cracked?

Oh.

And now:

Does the password reset feature work?

Yes.

Can I reuse the token?

Oh.

The technologies change. The pattern does not. We implement the requirements we know about, and experience introduces us to the ones we did not.

That is why mature abstractions matter. They carry some of that experience forward so the next developer inherits the lesson without personally reliving it. Somebody already hit the edge case. Somebody already found the vulnerability. Somebody already spent three days on the concurrency bug that only appears on Tuesdays.

Which leaves an open question I do not think we have answered yet.

A mature framework carries its institutional memory in its decisions. Sometimes the reasons stay attached through issues, commits, documentation, and design discussions. Often they do not, and only the resulting constraint survives. Either way, somebody encountered the problem and changed the system because of it.

That is the part worth noticing. The single-use token check runs whether or not anyone remembers why it was added. The lesson is enforced rather than remembered.

A model trained on a very large corpus of code has absorbed something that resembles institutional memory. But it learned from artifacts produced after those decisions were made, rather than from the decisions themselves. It can reproduce what surviving code looks like without inheriting anything that enforces why one implementation survived and another did not.

Which might explain why my agent wrote a flawless happy path and dropped the invariant.

Happy paths are abundant. Invariants live in the decisions.

Facebooktwitterredditlinkedinmail