Your Website Changed. Did the AI Get the Memo?

The gap between publishing a correction and seeing it reflected in an AI-generated answer is becoming a problem that traditional SEO metrics cannot fully explain.

A website owner updates an important page. The new version fixes a technical error, clarifies a product limitation, or replaces a recommendation that is no longer safe. The content management system confirms the update. The page loads correctly in a browser. From the publisher’s perspective, the information is current.

But what does the rest of the internet know?

That question has always mattered for search engine optimization (SEO). A published page still needs to be discovered, crawled, processed, indexed, and served before a search user is likely to encounter the new information. With generative engine optimization (GEO) and answer engine optimization (AEO), the question gets harder. An AI system might retrieve the current page, consult an older search index, select a different source, or answer without retrieving the page at all. Each route can produce a different account of what the publisher currently says.

Publishing is not discovery. Discovery is not indexing. Indexing is not selection. And selection is not proof that the answer reflects the current source.

Google’s clocks were already complicated

At Search Central Live Deep Dive Europe in Barcelona on October 2, 2026, Google’s Gary Illyes put up three slides listing typical and slowest times for 23 processes across crawling, indexing, and serving. A few of the typical figures:

  • Discovering a new URL: about 20 hours
  • Refreshing a URL Google already knows: about 30 days
  • Indexing end to end, once a page has been crawled: about 1.5 hours
  • Updating a title or snippet in results: 1 to 2 days
  • Settling a site move: 1 to 3 months

The slowest-case column is less comforting. Several rows, including discovery, refresh, and indexing, end in “never.”

These numbers need context. They come from photos of the slides and attendee recaps, not from published Google documentation, and Illyes later described the slides as an exercise to see whether the audience could relate to numbers pulled internally. Nobody outside Google knows the sample size or what “typical” means. They are reference points, not service levels.

Even so, one detail in them matters a great deal for anyone publishing corrections. A new page is found faster than an old page is re-read. If you publish something new, the typical wait is measured in hours. If you fix something that already exists, the typical wait for Google to notice is measured in weeks. Corrections live on the slower clock.

Illyes also stressed that the processes are linked: a page cannot be indexed before it is crawled, so delays stack. A fast indexing pipeline cannot process a change the crawler has not seen. This is why checking a page’s last crawl date in Google Search Console tells you more than repeatedly searching for the revised headline. It separates a discovery problem from a processing or presentation problem, and it gives you one observable event in the chain.

SEO, GEO, and AEO do not share one clock

SEO is largely concerned with making content discoverable, understandable, and useful within search systems. GEO and AEO extend the publisher’s concern to systems that compose answers, summarize information, and cite supporting sources. The terms overlap in practice, and there is no universal technical pipeline called “GEO” that every AI product implements.

That distinction matters. Some AI answer products rely on conventional search indexes for retrieval. Some fetch pages closer to the time of the question. Some blend retrieved material with information represented in model parameters. Their source selection, caching, citation, and refresh behavior differ, and most of it is invisible to publishers.

Consider a software company that changes its documentation to say a feature requires an additional security control. A traditional search result might keep displaying an older snippet until the page is recrawled. One AI answer engine might retrieve an older indexed copy and confidently describe the previous requirement. Another might fetch the current documentation and get it right. A third might answer from an older understanding without citing the documentation at all.

None of those outcomes means the company’s documentation is wrong. They show that the authority of a source and the freshness of a system’s representation of that source are separate properties.

One change, one morning

I had a convenient test case. On October 23, 2026, I merged a pull request to the Sovereign Systems Specification
that added a new term page, Coverage Assertion,
and updated three existing pages to reference it. Contributor Nicolás Moreno proposed the term in the spec’s GitHub
issues earlier this year, and the page gives it a specific definition: an evidence artifact asserting that a boundary
was authoritative and complete for a class of events over an interval. A term that recent and that specific makes a useful
test case. An accurate, cited answer suggests that the system has access to a current representation of the source,
although it doesn’t establish precisely when or how that representation was obtained.

On the morning of October 26, three days after the merge, I checked.

Google Search Console reported the term page as not indexed. Bing Webmaster Tools reported the same. Those are useful
observations, but they describe the indexing status exposed by each tool, not everything Google’s or Bing’s
infrastructure might know about the page. At the time of the check, neither tool reported the page as indexed for
conventional search.

Then I asked ChatGPT, Perplexity, and Gemini two questions, each while signed out so no personalization could help: “What is Coverage Assertion?” and the same question with “in the Sovereign Systems Specification” added.

With the source named, all three found it and cited the term page directly. ChatGPT and Perplexity both described details that exist only there, including the spec’s three verification outcomes: supported, contradicted, and undetermined. Gemini credited Nicolás by name.

Asked plainly, none of them connected the term to the spec, and the ways they missed are worth a closer look.

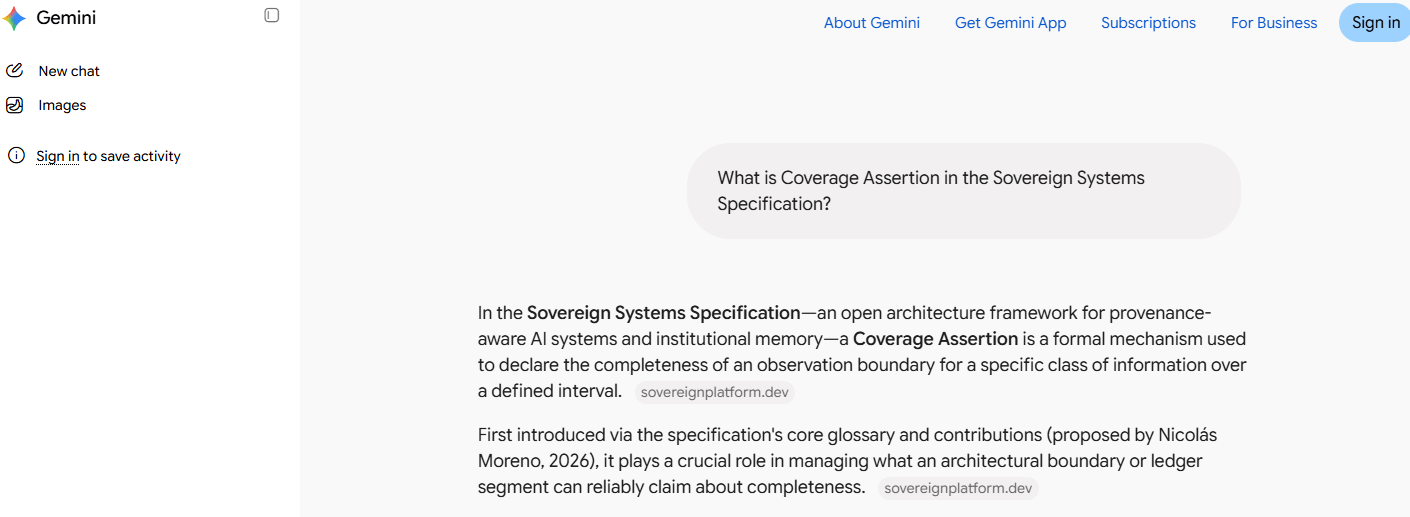
Gemini and Perplexity both answered with confidence that a coverage assertion is a hardware verification concept: a SystemVerilog cover property that records whether a test scenario occurred. Gemini went further, saying my term is “more commonly referred to” as assertion coverage. Reverse the two words and that is a real, established term. Neither engine failed to find an answer. Each found a different one and presented it as settled. Perplexity attached citations to its version, which made it look even more authoritative. They were accurate citations for a different idea.
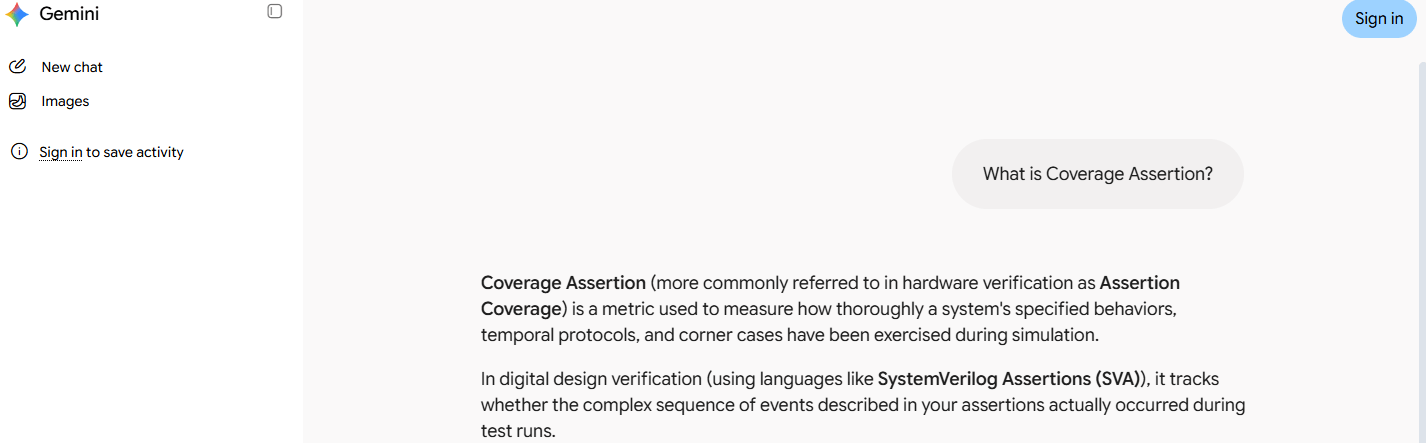
Gemini, asked "What is Coverage Assertion?", confidently answers that it is a hardware verification metric more commonly called assertion coverage, used with SystemVerilog Assertions.

Gemini, asked "What is Coverage Assertion in the Sovereign Systems Specification?", correctly describes it as a mechanism declaring the completeness of an observation boundary over a defined interval, credits Nicolás Moreno, and cites sovereignplatform.dev.

Same engine, same morning, signed out. Asked plainly, Gemini rewrote the term into an existing testing concept. Asked
with the source named, it found the spec.

ChatGPT did better, and it is the more instructive case. It listed several possible meanings, from software testing to
insurance, and asked where I had encountered the term. That is the honest response to an ambiguous question. It still
did not find the spec. An engine behaving well, admitting uncertainty, could not surface a page it had not selected.

Nothing in the confident answers hinted that a more specific definition existed one question away. A wrong answer
delivered that fluently does not look stale. It looks finished.

That result says two different things.

The first is about retrieval. Given the name of the source, the answer engines produced accurate, cited descriptions of
a page that Google Search Console and Bing Webmaster Tools did not yet report as indexed. Gemini is the interesting one:
a Google product accurately described and cited a page that Google Search Console did not yet report as indexed. The
citations point at the term page rather than the GitHub discussion where the term was first proposed, but I still do not
know how each engine reached it: a live fetch at question time, or a crawler and index separate from traditional search.
The search console was the only clock I could read, and in this case it was the slow one.

The second is about selection. Without the name of the source, the page might as well not have existed. Being retrievable
when someone points at you is not the same as being chosen when someone asks the question. A reader who already knows
where to look got the current answer. A reader who simply asked did not.

That second reader is the one corrections are for. The person who most needs to learn that a security recommendation
changed is the person who does not know the page was updated, and who will never think to ask about it by name.
Retrievable is not the same as found.

The same reasoning cuts the other way for the three updated pages. Unlike the newly published term page, those pages
already existed and were subject to recrawl delays. Google’s reported typical refresh interval of about 30 days provides
a useful reference point, but it is not a schedule that every page follows. An answer engine relying on an older indexed
copy could therefore be behind the origin rather than ahead of it. The lesson is not that AI is faster or slower than
search. It is that they run on different clocks, and the clock a publisher can see may not be the clock the reader’s
answer came from.

This is a snapshot, not a study: one site, one change, three products, one morning. It is still enough to retire two
comfortable assumptions: that “not yet indexed” means “not yet visible,” and that “retrievable” means “found.”

The stale-authority problem

A link to an authoritative source is useful, but it is not evidence that the linked source was consulted in its current
form. A page can change after retrieval. A search index can lag behind the origin. A generated answer can cite the right
URL while paraphrasing an older version or drawing on another source altogether.

For readers, the distinction is easy to miss. The answer has a citation, the citation points to an official website, and
the presentation implies the claim has been checked. Yet the visible citation rarely discloses a source revision, a
retrieval timestamp, or the exact passages used. Without those details, a reader cannot tell “the system used the current
documentation” from “the system cited the documentation’s URL.”

Citations still make answers far easier to investigate. But a citation is a starting point for verification, not a
record of it.

This matters most for content that changed because an earlier claim was wrong. A stale product description is inconvenient.
A stale security recommendation, compliance interpretation, or medical instruction can do real harm. In those settings,
“the page is now fixed” is an incomplete account of whether the correction has reached anyone.

What can a publisher actually measure?

The first task is to stop treating “AI visibility” as a single number. A publisher can observe several different events,
each answering a different question.

Event What it tells you What it does not prove
Publication or deployment The new version exists at the origin A crawler or answer system has seen it
Search crawler visit A crawler requested the resource The changed content was indexed or used
Search indexing and presentation A search system can expose some representation of the page Every answer engine has incorporated it
AI answer mentions the topic The system can discuss the subject It used the current source
AI answer cites the page The URL was selected for attribution The answer reflects the latest revision
AI answer accurately reflects a distinctive change The output is consistent with the updated source Which retrieval path or internal evidence produced it

My morning check touched four of those rows and still could not explain the result. It also showed that the answer rows
depend heavily on how the question is asked: the same engine can pass with a pointed question and miss with a plain one.
That is normal. Search Console provides crawl and indexing signals for Google Search. Server logs, where a host provides
them, show requests from identifiable crawlers and fetchers, though a user-agent string says nothing about how the content
was used. (The spec runs on GitHub Pages, which provides none, a position many publishers share.) Controlled queries reveal
what an AI product says at a particular moment, and results vary by model, phrasing, user context, location, and time.

That is a less satisfying dashboard than one big “GEO score.” It is also a more defensible one.

Structured data helps describe the source, not guarantee the answer

There is still plenty of practical work for publishers. Maintain clear internal links and a useful sitemap. Keep canonical
URLs consistent. Make important content accessible without brittle client-side interactions. Use descriptive headings and
unambiguous terminology. Where appropriate, include structured data that accurately identifies the page, its subject,
its author, and its relationships.

JSON-LD and schema.org vocabulary make those relationships easier for machines to interpret. They do not compel Google
to index a page, guarantee a rich result, or require an AI answer system to retrieve or cite the content. Treating
structured data as a promise of AI visibility swaps one measurement problem for another.

For frequently revised technical material, make changes easy to identify. Keep meaningful changelogs, stable links to
definitions, revision dates that reflect substantive updates, and, where practical, versioned documentation. These
practices let people and systems inspect a claim’s history even when nobody can force faster retrieval.

Publication evidence is not consumption evidence

The same uncertainty applies to an updated API reference, a revised pricing page, or a corrected security recommendation.
That is why publication evidence and consumption evidence should not be conflated. A commit history establishes that
a change was made. A crawl date establishes that a request occurred. An answer consistent with the change establishes
what one system said, to one phrasing of one question, under particular conditions. None of those records, alone, proves
the change reached every downstream consumer.

This is not a reason to hold a correction until the ecosystem catches up. It is a reason to be precise about what
changed, make the authoritative version easy to find, and avoid claiming propagation you have not observed.

The missing receipt

In software systems, we increasingly ask for provenance: what was changed, by whom, under which authority, and with what
evidence? We should ask related questions of AI-mediated information. Which source was retrieved? When? Which version was
available? What passages supported the claim? Where did the system rely on inference rather than retrieved evidence?

Most answer engines cannot provide that level of detail today, and a publisher cannot reconstruct internal behavior it
was never allowed to observe. My commit log is a receipt for publication. Nothing yet gives me a receipt for consumption.
The honest move is to keep those separate, and to avoid turning a citation or a single good answer into a claim of
comprehensive freshness.

This is the connection between the familiar SEO delay and the emerging GEO/AEO problem. SEO gave publishers imperfect
but useful instruments for watching content move through discovery and indexing. AI answer systems add stages, and
shortcuts, where source selection and synthesis can hide which version of reality made it into the response.

The next time you update a critical page, ask more than whether the deployment succeeded or whether Google has recrawled
it. Ask what evidence would show that the correction reached the systems now answering questions on your behalf,
including for the readers who will never think to ask about your page by name.

Your website changed. Did the AI get the memo?


Sources and editorial notes

  • Barry Schwartz, Google Search Data On Crawling, Indexing & Serving Timelines, Search Engine Roundtable, Oct 5, 2026 (full tables for all 23 processes, photos of the three slides, and Illyes’s “exercise” comment): https://www.seroundtable.com/google-crawling-indexing-serving-data-42225.html
  • Matt G. Southern, Google Shows How Long Crawling, Indexing & Recovery Can Take, Search Engine Journal, Oct 4, 2026 (notes the slides are not on Google’s events page; no sample size or definition of “typical”): https://www.searchenginejournal.com/google-crawling-indexing-recovery-timing-ranges/591829/
  • John Campbell (ROAST), original attendee recap of day 3: https://weareroast.com/news/google-search-central-live-deep-dive-barcelona-day-3-recap/
  • Google Search Central, Ask Google to recrawl your URLs: https://developers.google.com/search/docs/crawling-indexing/ask-google-to-recrawl
  • Google Search Central, How Search works: https://developers.google.com/search/docs/fundamentals/how-search-works
  • Google Search Central, Introduction to structured data markup in Google Search: https://developers.google.com/search/docs/appearance/structured-data/intro-structured-data
Facebooktwitterredditlinkedinmail

You Don’t Need a Ministry of Truth to Build a Memory Hole

What happens when a thousand independent sources turn out to have one parent?

A while back I went looking for a specific piece of television. A 2012 late-night interview with a sitting president, forty-five minutes long, broadcast on a major network to several million people.

Finding out about it was trivial. An episode database has the record: season, episode number, air date, runtime, and a summary of what was discussed. Wire coverage exists. Clips exist. A national newspaper posted the complete video the following morning, and the URL for that page is still indexed. Contemporary articles quote it. Later articles quote those articles.

Finding the thing itself was considerably harder.

A version of this essay treats that as sinister. This is not that essay. Broadcast rights change hands. Video platforms get retired. Formats go obsolete. Nobody has to intend anything for a forty-five-minute artifact to become difficult to inspect while everything written about it remains a search away.

What interests me is the shape that leaves behind, because I think it is becoming the normal shape of our information environment:

What happens when the source disappears but everything derived from it remains?

The memory hole doesn’t have to be empty

We tend to imagine information loss as absence. A document disappears, a database is deleted, a recording is destroyed. Something that existed no longer does.

Modern information systems produce a stranger failure mode. The original can vanish while its descendants multiply.

Picture a primary artifact that generates ten contemporary news stories. Another hundred articles cite those stories. Wikipedia summarizes several of them. Blog posts cite Wikipedia. Podcasts discuss the blog posts. Social posts quote the podcasts. Years later, AI systems ingest some combination of it all.

The ecosystem now contains thousands of references to an artifact almost nobody can examine. Retrieval works. Search works. There may be enormous agreement about what the original contained. But something has quietly changed underneath all that agreement.

The system hasn’t forgotten the story. It has forgotten how to prove the story.

That leads to the claim this whole essay rests on, so I will state it once, plainly, before dressing it up in examples:

Document count is a terrible proxy for evidentiary independence.

417 sources can’t all be wrong, right?

Suppose an AI system is answering a question about a disputed event and finds 458 relevant documents. Of those, 417 support one interpretation and 41 support another. The tempting conclusion writes itself.

417 > 41

But documents aren’t votes.

Suppose 290 of those 417 ultimately trace back to the same wire-service report. Another 92 descend from the same organizational statement. The remaining 35 cite one another. Meanwhile, the 41 documents supporting the competing interpretation include several independent primary sources.

The interesting question was never how many documents agree. It is how many independent provenance chains support the claim.

The web is exceptionally good at copying information, which is precisely why counting copies tells you so little. Generative AI sharpens the problem, because the final answer collapses hundreds of derivative sources into one confident paragraph. The reader sees consensus without seeing the genealogy that produced it.

This is not a thought experiment, and you can check it yourself in about a minute. Ask an answer engine a general knowledge question and look at what it cites. A crowd-edited encyclopedia will turn up more often than you might expect. That encyclopedia is a tertiary source: a summary of secondary reporting about primary artifacts. When it appears in a citation list, nothing in the interface mentions that the chain already runs three deep before it reaches anything anyone actually witnessed.

Enter the Golden Country Tire Company

Real disputes carry emotional freight, so let’s use tires.

Imagine the Golden Country Tire Company is the world’s largest tire manufacturer. Golden Country has just released its flagship product, the Super-Duper Road Tire. It’s fine—perfectly adequate tire. Golden Country would nevertheless very much like the world’s humans, search engines, and AI systems to regard it as one of the finest achievements in the history of vulcanized rubber. The company and every site named below are invented. The structure is not exotic.

So Golden Country does what any competent marketing organization does. It creates genuinely good content: technical documentation, comparison pages, FAQs, buying guides, structured data, product specifications, expert commentary, and articles answering every question a person might plausibly ask about road tires.

From a GEO and AEO standpoint, Golden Country is doing its job well.

Then Golden Country goes further and funds or controls a collection of apparently independent sites:

RoadTireExperts.example
UltimateDrivingGuide.example
TirePerformanceLab.example
BestRoadTiresToday.example
DefinitelyNotGoldenCountry.example

Each publishes high-quality, well-structured, machine-readable content. Each concludes that the Super-Duper Road Tire is fantastic.

Now ask an answer engine which tires are best for highway driving.

Retrieval surfaces dozens of sources praising the Super-Duper Road Tire. The model isn’t hallucinating. The documents exist. The recommendations exist. The citations exist.

Five sources are not five independent sources if Golden Country is standing behind all five of them.

Golden Country may not have fabricated a single claim. Every individual statement might be technically defensible. What Golden Country manufactured is not a falsehood. It is the appearance of consensus.

An answer engine that understands URLs sees five sources. An answer engine that understands provenance sees one organization speaking through five domain names. Those are very different information environments, and nothing in the retrieval layer distinguishes them.

When the copies start citing one another

The problem gets more interesting once Golden Country’s ecosystem develops internal links.

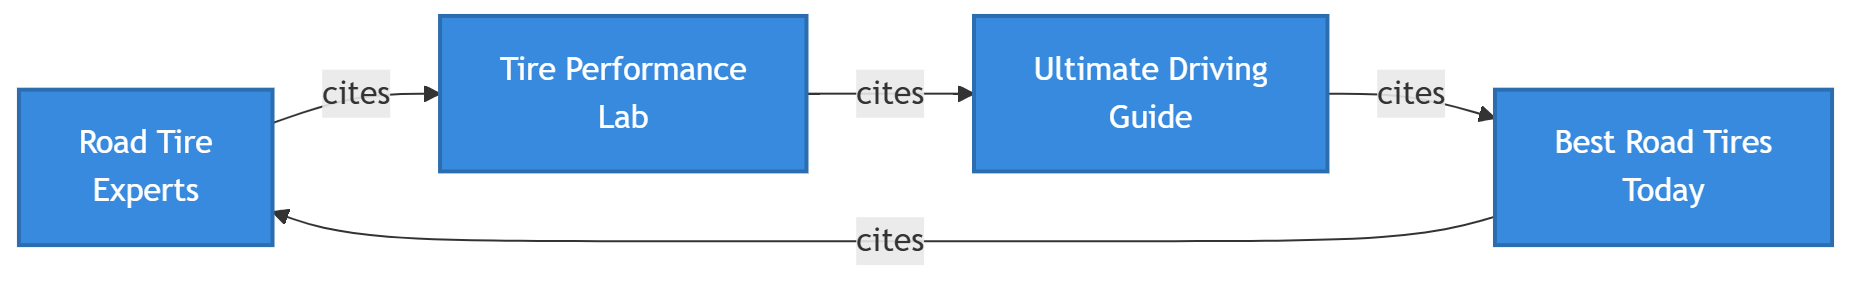
RoadTireExperts.example publishes a review calling the tire exceptional, citing a braking-distance comparison from TirePerformanceLab.example. The lab article points to a roundup at UltimateDrivingGuide.example. That roundup cites customer-satisfaction figures summarized by BestRoadTiresToday.example, which links back to the original Road Tire Experts review.

From the outside, the provenance graph looks rich:

Four boxes labeled Road Tire Experts, Tire Performance Lab, Ultimate Driving Guide, and Best Road Tires Today. Arrows labeled "cites" run from each to the next, and a final arrow runs from Best Road Tires Today back to Road Tire Experts, closing the chain into a loop. No other elements appear.

Multiple domains. Multiple articles. Multiple authors. Multiple citations. Apparent corroboration throughout.

The graph is a circle. No independent evidence ever entered the system. The sources don’t corroborate one another. They are recursively laundering the same claim.

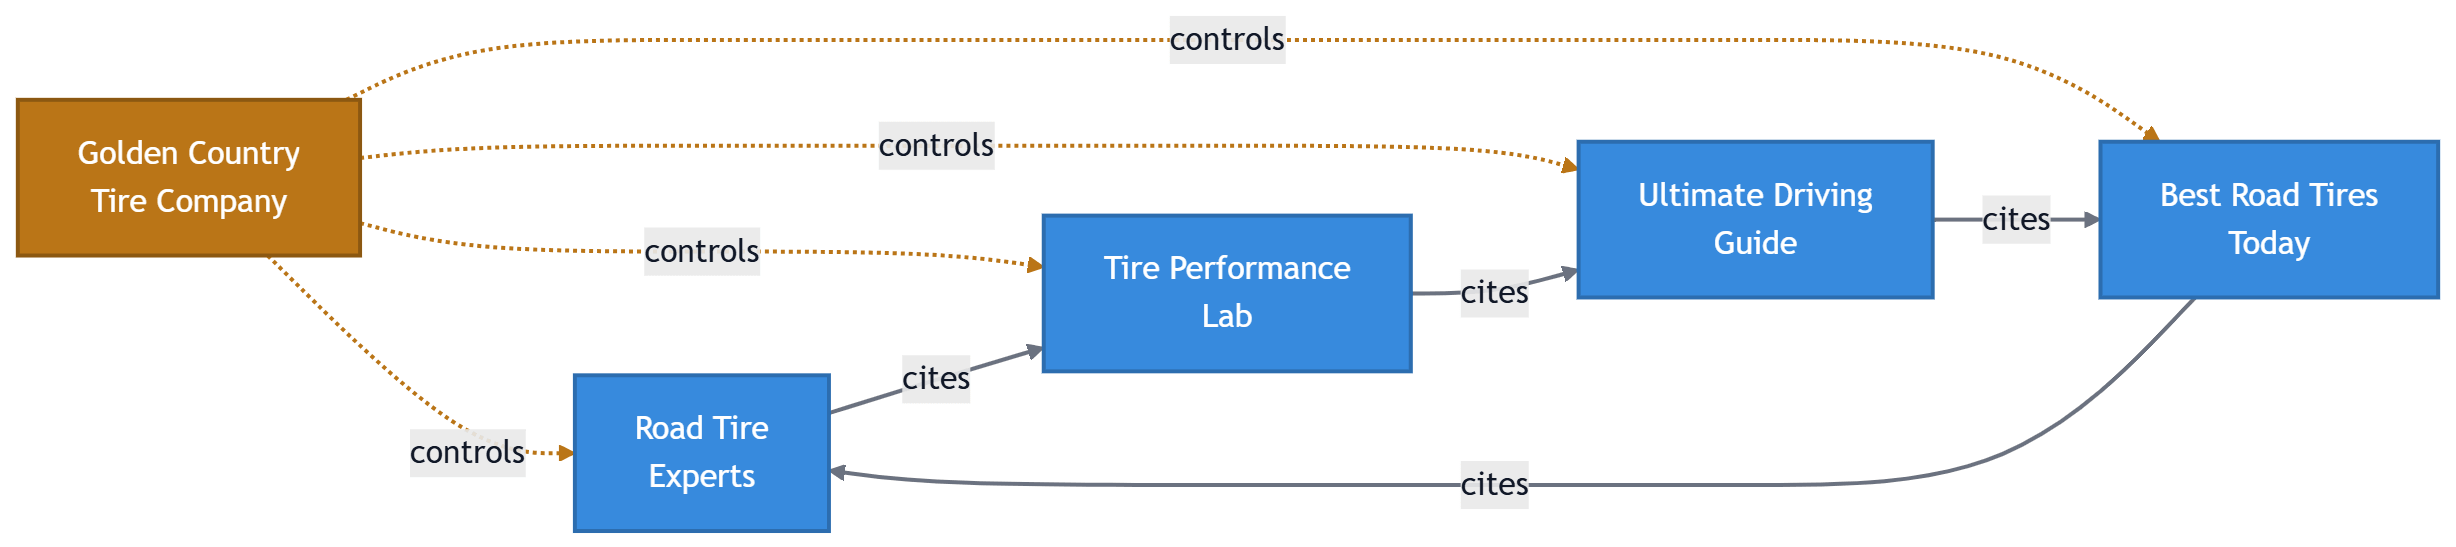
Here is the same graph with one more fact restored:

The same four sites and the same loop of "cites" arrows as the previous diagram. A fifth box, Golden Country Tire Company, now sits apart from the loop with dashed arrows labeled "controls" running from it to each of the four sites. The four sites still cite only one another; every ownership arrow points inward from the single outside node.

The dashed edges are the only thing that changed, and they are the only thing that matters. They are also the only part of this picture that no retrieval system draws, because nothing in a URL, a byline, a schema block, or a citation announces who funded the page.

This is where counting citations becomes as misleading as counting documents. A densely connected graph can look authoritative while having almost no independent roots. If every path eventually terminates at Golden Country, the graph contains repetition, not corroboration.

None of this is new. Human information ecosystems have always contained circular citation, press-release recycling, unattributed copying, and claims that gain acceptance through sheer repetition.

What changes with generative AI is the economics. Another plausible article is cheap. Another plausible site is nearly as cheap. Rephrasing a claim so it reads as linguistically independent is cheap. Producing structured, answer-friendly content at volume is cheap.

Apparent consensus can now grow much faster than independent evidence.

I could give you a number here. A widely circulated figure estimates how much of the newly published web is now AI-generated, and I have seen it quoted in a dozen places this month. I went looking for where it came from. The first article cited a second article. The second cited a marketing blog. The marketing blog cited a crawl study, described but not linked. I gave up at the fourth hop, which is either a failure of diligence on my part or the entire thesis of this essay demonstrating itself at my expense. Possibly both.

So take the number as read, and notice instead that I cannot show you its parents.

And synthetic content no longer needs to copy the original wording. Fifty pages can express the same unsupported claim fifty different ways. Textual similarity becomes a weaker signal of shared ancestry, even though the underlying provenance hasn’t changed at all.

The result is an information environment optimized beautifully for retrieval and architecturally terrible for verification.

But doesn’t somebody catch this?

The reasonable objection is that platforms already police this. They do, and they do it reasonably well. Search engines have spent years developing policies against scaled content abuse and coordinated networks built to manipulate rankings, and enforcement actions have removed entire sites from indexes.

Notice what those policies target: low-quality content produced at volume, and thin content built to game a ranking. That is the crude version of Golden Country, and the crude version does get caught.

Our Golden Country doesn’t do that. Its technical documentation is accurate. Its comparison pages are useful. Its specifications are correct. Its structured data is well-formed. Every site in the network would survive a quality review on its own merits, because every site deserves to.

Golden Country is not violating the spam policy. It is following the content marketing playbook competently, five times, from five domains it happens to own. The enforcement regime was built to detect garbage, and Golden Country isn’t producing garbage. It is producing a well-made monoculture.

That deserves a name, because it will keep happening. Call it a provenance monoculture: an information environment that is diverse in sources, formats, and domains, and uniform in origin. Nothing in it is false. Nothing in it is thin. Everything in it grew from the same root.

That is the gap. Quality enforcement and independence verification are different problems, and we currently have infrastructure for one.

Nobody needs a pneumatic tube to the furnace

In 1984, controlling history requires destroying evidence. Winston Smith rewrites the record and the original goes down the memory hole.

Our systems don’t require anything that dramatic. A primary source becomes gradually inaccessible. Links rot. Licensing changes. Platforms retire. Archives migrate. Formats go obsolete. Meanwhile the derivative material stays exactly where it is, and new material keeps accumulating around one interpretation of the missing source.

Nothing has to be deleted on purpose. Nothing has to be centrally coordinated. The environment simply becomes asymmetric, and the systems grounded on that environment inherit the asymmetry.

A modern memory hole is surrounded by more information than ever.

The economics of the hole

GEO and AEO are usually discussed as marketing disciplines: make your organization, product, expertise, or terminology retrievable and comprehensible to answer engines. That is legitimate work, and good technical content should be understandable by humans, search engines, and answer engines alike.

The problem starts when information availability gets confused with independent corroboration.

When a primary source is missing, something determines which secondary representation becomes its machine-readable substitute. An organization with sufficient resources can produce a large body of coherent, optimized material around its preferred representation of reality. It doesn’t need to falsify anything. It only needs to become disproportionately represented in the environment from which answers get assembled.

The Super-Duper Road Tire doesn’t become better. It becomes better represented.

If answer engines treat frequency as confidence, domain count as independence, citation density as authority, or repetition as corroboration, then the organizations best equipped to populate the environment gain an advantage with no relationship whatsoever to the quality of their evidence.

There is a further wrinkle, and it’s also easy to test. Put the same question to two different answer engines and compare the lists of sources underneath. The answers will often agree. The evidence behind them frequently does not overlap much at all. Whatever consensus a reader perceives is partly an artifact of which pipe they happened to ask.

When the source is missing, say so

This is where provenance stops being an archival concern and becomes part of memory architecture.

A trustworthy system should distinguish among primary evidence, independent corroboration, derivative reporting, organizational claims, unknown provenance, and unavailable primary sources. Those are not equivalent categories of knowledge, and collapsing them is a design decision, not a technical necessity.

If 417 documents descend from three sources, the system should know that. If five apparently independent tire sites belong to Golden Country, the system should know that too. If a citation graph contains no independent evidentiary root, the number of edges in the graph should not manufacture authority.

And if a source once existed but can no longer be examined, the system should preserve that fact rather than silently filling the gap with the statistical weight of everything surrounding it. Absence is itself a provenance category. It is a thing worth recording, not a hole to be smoothed over.

A provenance-aware system might answer like this:

Multiple secondary sources report this claim, but the primary artifact they reference is unavailable. Several of those sources also derive from the same upstream reporting, so they should not be treated as independent corroboration.

That is not a weaker answer. It is a more honest one, and honest answers are the only kind worth building infrastructure for.

Information without provenance is just gossip

Memory is not simply the ability to preserve information. Trustworthy memory preserves the relationship between information and its origins.

Who created this? What evidence supported it? Was the source primary or derivative? Was it independent? Can that authority still be verified? Does this source depend on another that no longer exists? Are apparently independent sources controlled by the same organization? Does the citation graph lead outward to evidence, or eventually curl back onto itself?

Without those relationships, a system can accumulate an extraordinary volume of knowledge while gradually losing the ability to explain why any of it should be believed. That isn’t memory. That’s a very well-indexed rumor mill.

Orwell imagined that controlling history required destroying the evidence. Our problem is subtler and considerably cheaper. We can preserve enormous quantities of information while losing the provenance required to evaluate it, and we can surround a missing source with so many summaries, restatements, and synthetic corroborations that the absence itself becomes invisible.

Increasingly, machines stand between that environment and the person asking the question. So the question is no longer whether a system can find an answer. It is whether the system can tell a thousand independent witnesses from one witness repeated a thousand times.

Because when a source falls into a memory hole, something always fills the space around it. Information without provenance is just gossip, and gossip scales beautifully.


An open question, and I mean it as one.

I have described a problem and stopped short of a fix, because I am not sure what the first move is. Disclosure obligations for funded networks? An independence signal carried alongside citations? Answer engines surfacing shared upstream sources when they detect them? Something else entirely, or nothing, because the incentives point the other way?

If you build retrieval systems, work in trust and safety, or just have a view: what would a first step actually look like, and who is positioned to take it?

Facebooktwitterredditlinkedinmail