Forensic Receipts: From Trusted to Proven

Part 6 of the Building the AI Memory Stack series

At the end of the last article, I left one question unanswered.

Can you prove this record is exactly what was written?

Write-Side Custody decides which writes are trustworthy enough to become memory. But a decision to trust something is not the same as being able to prove it later.

Picture that deployment record one more time. Custody examined it, judged it authoritative, and let it become institutional memory. Six months on, an auditor asks a harder question: how do you know it hasn’t changed since?

“We only accept trustworthy writes” is a policy.

It is not proof.

Trust Is a Claim. Proof Is Evidence.

Custody and receipts answer two different questions.

Write-Side Custody asks: should this be trusted?

A Forensic Receipt asks: can this be proven?

The first is a judgment made at the moment of the write. The second is a piece of evidence that outlives the judgment, so that anyone, later, can verify the record for themselves without having to trust the system that stored it.
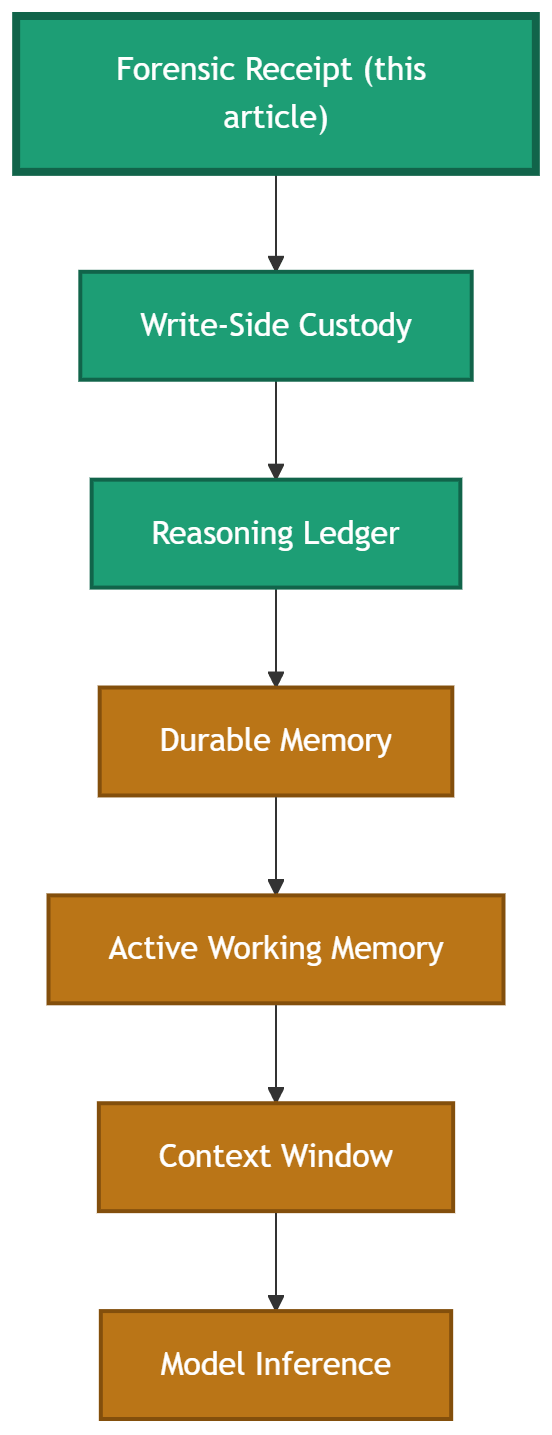
Diagram of the AI memory stack showing Forensic Receipt flowing through Write-Side Custody, Reasoning Ledger, Durable Memory, Active Working Memory, and Context Window to Model Inference. Forensic Receipt is highlighted as the focus of this article.

With that, the stack reaches bedrock. Every layer above now rests on a foundation that can be verified independently.

What a Forensic Receipt Is

The Sovereign Systems Specification calls this evidence a Forensic Receipt.

It is not a log entry. Log entries can be edited, reordered, or quietly rewritten. A Forensic Receipt is a cryptographic fingerprint of a record, captured and signed at the moment the record is written.

Change one character of the record, and the fingerprint no longer matches. The tampering isn’t hidden. It’s mathematically obvious.

In practice, a receipt might look like this:

forensic_receipt:
  record: reasoning_ledger/deploy-2026-03-14
  content_hash: sha256:3af9c1...e07b
  signed_at: 2026-03-14T09:22:07Z
  signature: ed25519:9d4a...c2
  signed_by: sovereign-node-07
  prior_receipt: sha256:8b21...44a

Two fields do most of the work.

The content hash binds the receipt to the exact bytes of the record. Nothing can be altered without breaking it.

The prior receipt links each record to the one before it, forming a chain. You cannot quietly remove or reorder history without every downstream receipt failing.

That is chain of custody, expressed as mathematics rather than as a promise.

Why Logs Aren’t Enough

Most systems already keep audit logs.

The problem is that an audit log is only as trustworthy as whoever controls it. If someone can write to the log, they can usually rewrite it, and a log that can be rewritten proves nothing about the past.

A Forensic Receipt inverts that. It doesn’t ask you to trust the operator, the database, or the backups. Verification depends on cryptography, not on authority, so the evidence speaks for itself.

That distinction is the whole point.

Custody earns trust. Receipts remove the need for it.

The Cost of Proof

None of this is free. Every receipt is a hash computed and a signature generated at write time, which is real work, paid on the write path, exactly where this series has argued trust belongs.

But the alternative is worse. A system that cannot prove its own memory is asking you to take its word for everything it claims to remember.

Proof is the price of being believed later.

The Stack Is Now Trustworthy and Provable

Step back and look at what the six layers guarantee together.

The Context Window executes. Active Working Memory assembles. Durable Memory preserves. The Reasoning Ledger explains. Write-Side Custody decides what to trust. Forensic Receipts prove it.

Execution, assembly, preservation, explanation, integrity, and evidence.

That is a complete architecture for trustworthy institutional memory.

Looking Ahead

We’ve built memory that is durable, explained, trustworthy, and provable.

But it is still sitting in cold storage.

None of it matters until it can return to active reasoning: verified, on demand, and paid for deliberately.

That is where the next article takes us, and where the promise from Part 1 is finally kept. It is the moment memory becomes voice.

Facebooktwitterredditlinkedinmail

The Guardian: Human-in-the-Loop AI Governance

The Guardian: Human-in-the-Loop AI Governance

We’ve built a system that is Reliable and Affordable. Our Forensic Team is accurate, and The Accountant ensures we aren’t wasting our cognitive budget.

But in the enterprise, “capable” is not enough. For high-stakes decisions—like a $50k rare book audit or a compliance check—fully autonomous AI is a Liability.

Today, we introduce The Guardian: The final phase of our Production-Grade AI trilogy. We are implementing a standardized Human-in-the-Loop (HITL) checkpoint, moving from “Autonomous Agents” to “Augmented Intelligence.”

1. The Autonomous Trap: Confident Hallucination

In the first post of this series, The Judge proved that even the best models can confidently hallucinate. In a forensic audit, an agent might identify a water damage pattern and declare: “CRITICAL: High probability of modern forgery.” If that finding is wrong, the reputational and financial damage is severe. The problem isn’t the AI’s capability; it’s the lack of authorization. The agent is a worker, not a partner.

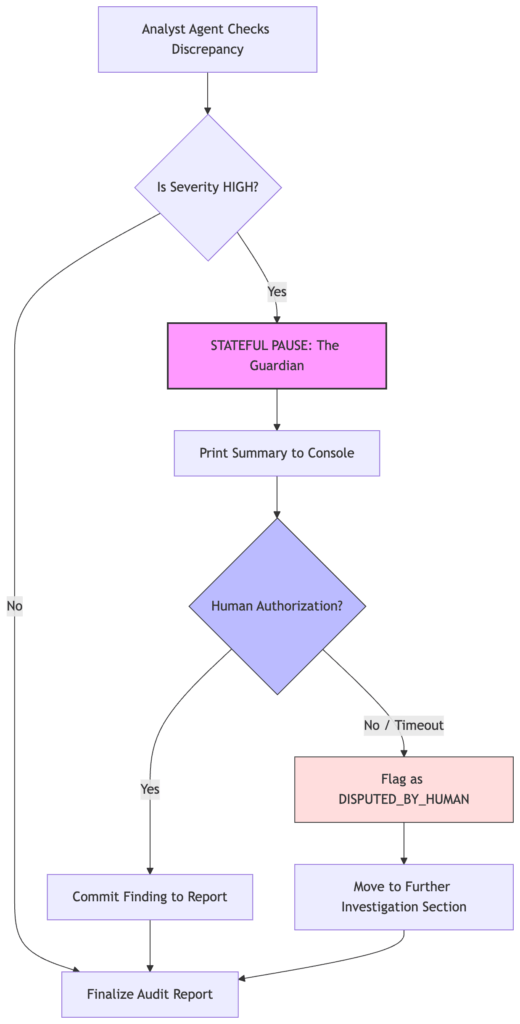
2. Implementing the “Governance Gate”

We need a way to “brake” the agent’s flow when it finds a high-severity issue. We’ve added the request_human_signature tool to our Forensic Analyzer MCP server project.

In orchestrator.py, we updated the logic. When the Analyst flags a “HIGH” severity discrepancy, the system performs a specialized handshake:

  1. Stateful Pause: The Python orchestrator interrupts the agent workflow.
  2. Authorization Prompt: It presents the evidence to the user via a CLI prompt.
  3. Cryptographic Signature: The user must authorize the finding before it’s committed to the final report.
# The Guardian's "Nuclear Key" moment in orchestrator.py
def _apply_guardian_handshake(analyst_result: dict) -> tuple[dict, list[dict]]:
    """
    Human-in-the-Loop: if Analyst has HIGH discrepancies, prompt for authorization.
    """
    disputed: list[dict] = []
    data = analyst_result.get("data") or {}
    disc = data.get("discrepancies", [])

    # Filter for the "High Stakes" findings
    high_disc = [d for d in disc if (d.get("severity") or "").upper() == "HIGH"]

    for d in high_disc:
        summary = f"[{d.get('severity')}] {d.get('field')}: {d.get('expected')} vs {d.get('observed')}"
        print(f"\n  Guardian: HIGH severity finding — {summary}")

        # THE STATEFUL PAUSE: The orchestrator stops and waits for a human
        answer = input("  Do you authorize this forensic finding? (yes/no): ").strip().lower()

        if answer != "yes":
            # Escalation: If not authorized, it's flagged as 'DISPUTED_BY_HUMAN'
            disputed.append({**d, "status": "DISPUTED_BY_HUMAN"})

    return analyst_result, disputed

By requiring a human to type ‘yes’, we are moving from Autonomous Assumption to Authorized Augmentation in the following ways:

  1. Severity-Based Intervention: “We don’t interrupt the user for every ‘Low’ or ‘Medium’ variance. We only trigger the Guardian for High-Severity findings—those that carry legal or financial liability. This preserves the ‘UX flow’ while maintaining safety.”
  2. The ‘Disputed’ State: “Notice that a ‘No’ from the human doesn’t just delete the finding. It moves it to a specialized ‘Requires Further Investigation’ section of the report. This ensures that the AI’s observation is preserved but clearly labeled as unauthorized.”
  3. Non-Interactive Fallback: “The code includes a check for EOFError (line 507). If the system is running in a non-interactive environment like a CI/CD pipeline, it defaults to ‘No’ (Dispute) for safety. Never default to ‘Yes’ for a high-risk authorization.”
Architectural diagram of a human-in-the-loop AI governance system called The Guardian. An agent workflow processes a task. When it detects a high-severity finding, it pauses and performs a stateful 'Authorization Handshake' with a Human Guardian. The human must sign or reject the finding before it proceeds to finalize the output report.
The Guardian Architecture—Moving from Autonomous Agents to Stateful, Authorized Human-AI Augmentation.

3. Beyond the CLI: The Enterprise Handshake

This reference implementation uses a CLI input() prompt for simplicity. However, the MCP tool is standardized. In a production environment, this tool wouldn’t pause a Python script; it would:

  • Trigger a Slack/Teams Alert to a senior auditor.
  • Open a Jira Ticket for manual review.
  • Request a Webauthn (Biometric) Signature in a web dashboard.

Summary: Building the Sovereign AI Stack

Across this series, we’ve moved from basic orchestration to a Production-Grade AI Mesh. We’ve proven that we can build systems that are:
1. Reliable: Audited by The Judge.
2. Sustainable: Optimized by The Accountant.
3. Safe: Governed by The Guardian.

The road to autonomous agents isn’t paved with more tokens; it’s paved with better guardrails.

What’s Next?

The code for the entire trilogy is available in the MCP Forensic Analyzer repository.

I’m currently working on Phase 3: The Sovereign Vault, where we will explore Local Multimodal Vision (processing artifact images without cloud egress) and PII Redaction to protect proprietary “Golden Data.”

Have questions about implementing these patterns in your own enterprise? Connect with me on LinkedIn or follow the blog for the next series.

The Production-Grade AI Series (Complete)

Looking for the foundation? Check out my previous series: The Zero-Glue AI Mesh with MCP.

Facebooktwitterredditlinkedinmail