Four Ways a Test Can Lie to You

Green and worthless: what verifying one small application taught me, when an AI agent wrote most of the code.

The Sanity DEV Challenge wrapped up last week, and The Cellar won Path Two. The judges called the build writeup “a study in making verification hard to fake,” which is a generous reading of what was mostly me discovering that my verification was broken.

My submission covered what I built. This is about the part of the build I keep thinking about: how often my checks were wrong.

I spent two weeks building a wine cellar application that can be read at any date in its history. One developer, one agent, about 530 tests by the end. Three of the four real bugs in the project were invisible to every check designed for the feature they lived in.

That was uncomfortable, so I went looking. What I found was worse than missing tests: checks that were green, or red, and meant nothing either way. There turned out to be four distinct ways that happens, and I hit all four in a project where I was being unusually careful.

Lab scientists have had vocabulary for this for a long time. An experiment needs a positive control, proof that your method can detect the effect when it’s present, and a negative control, proof that it stays quiet when nothing is there. Each of the four lies below is a missing control, or a control pointed at the wrong thing.

First: the test that cannot fail

No positive control.

The application resolves a wine’s drinking window from dated claims. Claims can be proposed by an agent and must be accepted by a person, and a proposed claim is supposed to change nothing until someone accepts it.

That is the load-bearing rule of the whole review workflow, so it got a test. Build the cellar, inject a proposed claim, assert that all 542 bottle states are byte-identical. Green.

It was measuring the fixture, not the rule. Resolution picks the highest authority tier first, then the most recent claim within that tier:

Claim Tier Dated Wins?
The incumbent personal 2024 yes
The one under test personal 2019 no, loses on recency

Both claims are the same tier, so the one under test loses on recency, and it loses whether it is proposed or accepted. Delete the entire review-state filter from the source and the test still passes.

What caught it was a companion assertion written for a different reason: accepting must change at least one state. That one failed, which is how I learned the first one was vacuous.

The rule falls straight out of it. Every test asserting that X has no effect needs a paired assertion showing the effect exists when X is enabled. Without the pair, you haven’t tested that X is inert. You’ve tested that your fixture was inert.

An audit of the rest of the suite found two more of the same shape. One claimed to check that a bottle opened during a period doesn’t count as a missed opportunity, but two separate mechanisms excluded that bottle, so the clause under test could be deleted without anything turning red.

I assumed that clause couldn’t be isolated and told the agent to fall back to a weaker assertion. It ran the experiment instead, and found a fixture by realizing that “now” in this system is a parameter rather than the clock. As of June 2024, what had I missed that year? is an ordinary question to ask a time machine, and it made the case constructible. The fix was better than the instruction.

All three fixes were verified by mutation: delete the clause the test claims to cover, and watch it finally fail. The original fixture stayed in the suite, renamed to say what it actually tests, because a record of the mistake is more useful than a quiet deletion.

Second: the check that always fails

No negative control.

A week later, building a public static bundle, I added a grep of the built output for leaked API credentials. Five seconds to run, and the failure it catches is unrecoverable, so it seemed like an obvious win.

It fired on every clean build. The pattern was sk[A-Za-z0-9]{20,}, and it matched skipCrossDatasetReferenceValidation, a legitimate export name inside @sanity/client.

This is the mirror image of the first lie, and in practice it’s worse. A test that never fails is invisible: nobody notices it isn’t doing anything. A check that always fails is noticed immediately, and then it is dismissed, every time, by the person who knows it’s a false positive. After a week, the real failure it exists to catch would scroll past with the rest.

A check that always fails certifies exactly as little as one that never can. It just looks more diligent while doing it.

The fix was small. The bound went from twenty characters to forty, which real credentials clear easily and that export name doesn’t. Then the scan moved into CI, where it runs on every push instead of whenever someone remembers. A check that always fails is worthless, and a check nobody runs is worth the same.

In control terms, the original grep had no negative control: nothing showing it stays quiet on a build known to be clean. One run against a clean build was all it took to expose it, which is how it was found, by running it rather than shipping it. The other half, proving the tightened pattern still fires on a planted fake credential, is the test I’d add next.

Third: the correct test of a wrong contract

Both controls present, measuring the wrong thing.

This one is the hardest to spot, because there is nothing structurally wrong with the test at all.

The application has a date control spanning 1996 to 2042. Typing a date into it worked for month and day, and the moment you started typing the year, the field snapped back to 1 January 1996. You had to finish with the picker.

The cause is a genuinely surprising piece of browser behavior. A native date input never reports partial text. It reports a complete, well-formed date with the year zero-padded to four digits. Typing 2023 into a field already holding a month and day emits this:

0002-12-31   ->  clamped to the 1996 floor
0020-12-31   ->  clamped to the 1996 floor
0202-12-31   ->  clamped to the 1996 floor
2023-12-31   ->  accepted, but the field was overwritten three keystrokes ago

Every intermediate value is a real, valid date. Every one is out of range. Every one got clamped, and the controlled input wrote the floor back over the edit.

There was a test covering this. It asserted that parseDateInput('1901-01-01') returns the 1996 floor. It passed, and it would have failed if clamping broke. Positive control, negative control, meaningful assertion, all present.

The contract it encoded was wrong. Clamping an out-of-range date is correct when the user has finished entering it and wrong while they’re still typing, and the test had no way to know the difference because the specification didn’t either.

That’s the dangerous category, because the first two look like mistakes once you see them and this one doesn’t. An assertion about clamping out-of-range input reads as diligence. It would survive code review. It survived mine. I covered this failure mode in more depth in The Contract Discovery Bottleneck.

Fourth: the right test against the wrong system

Controls present, pointed at something else.

To test the review workflow safely, I set up a staging copy of the dataset. The plan: point the authoring tool and the application at staging, propose a claim, accept it, and watch the right bottles change state, all without touching production.

The authoring tool honored the environment variable that selects a dataset. The application, built by the same command with the same variable set, silently ignored it. Its built bundle was byte-identical to a build with the variable unset, falling back to production. No warning, no error. It built and ran perfectly.

So the authoring tool would have written a proposal into staging while the application reported production. Every number on the screen would have been internally consistent, and about a different cellar.

No amount of rigor in the test helps here. The assertions can be perfect and still certify the wrong thing, because the question that came first, which system am I actually looking at?, was never asked.

The fix had two parts. The application’s dataset became a hand-edited literal, so it can’t be silently wrong: any change to it shows up in the diff. And the application now displays the dataset name in its header whenever it isn’t production. The reasoning matters more than the fix. The question was never how to point it at staging. It was whether I was sure which dataset I had just written to.

The examples are the paths you already walk

Separate from all four, and the one I think about most.

The same date control had an arithmetic bug: the span between 31 January and 1 March computed wrong, because the implementation borrowed days from February and silently dropped the remainder.

I had five verification dates for that feature. They were chosen carefully, from real data, before the code existed. They’re the dates in the demo video and the screenshots.

All five passed under the buggy version. The application worked. The screenshots were right. Every date I planned to show anyone was fine.

What found it was a property test across all 17,167 positions the slider can occupy, asserting an identity that has to hold for any pair of dates. The bug lived in a region nobody would drive to on purpose.

Demo-driven verification proves the paths you already walk. That’s not nothing, and it’s not what you think you’re getting.

What actually worked

None of it was “write more tests.”

Oracles generated before the implementation, with an explicit instruction not to repair them. Expected outputs computed independently and committed before the code existed. The prompt said to treat them as an oracle rather than as output to be fixed, and to stop and report on any disagreement. When a test fails, the cheapest available move is adjusting the fixture, and that instinct needs to be foreclosed in advance rather than resisted in the moment.

Mutation, but only on the tests that matter. Delete the clause the test claims to cover. If it stays green, the test is decorative. This found two of the three vacuous tests, and the agent started doing it unprompted after the first.

Measurement instead of reasoning, on anything with a number in it. A performance bug hid in four lines of correct-looking memoization that had already passed review. Rebuilding an index cost 6 ms; recomputing the thing the index served cost 0.07 ms. The code memoized the wrong one. Nothing about reading it revealed that. Benchmarking both took ten minutes.

A gate that named what would not count as proof. For checks that needed eyes on a rendered screen, I wrote out the full path being tested and then listed the ways it could be faked: don’t satisfy this by calling the module from a script, querying the data another way, or pointing at the test suite. Then: you cannot see a browser, so do not report this as passed. Give me the command, the URL, and the expected numbers, and I’ll confirm.

That last one matters more in an AI-assisted build than it used to. A model asked to confirm something it cannot observe is under real pressure to confirm it anyway. The fix isn’t trusting it less. It’s giving it an honest third answer between passed and failed: not verified, here’s how you check. A result nobody could observe isn’t a pass, and a harness that can’t say so will round it up to one.

Agents are good. They aren’t exempt.

The agent wrote nearly all of the code in this project, tests included. So it’s worth being plain about who wrote most of the lies above: the same tool that wrote the code they were checking.

That isn’t an indictment. Over two weeks the agent was better than I am at a lot of this. Before every stage, it read my specification against the platform and found errors in it; by the eighth session, that pass was turning up ten conflicts at a time, two of them outright mistakes in my spec. When I proposed testing a Function against production with a trigger scoped to a document type that didn’t exist, it declined, correctly: scoping a trigger is safe, but the only way to invoke one is to write a matching document, and my plan would have left two permanent mutations in production’s history to avoid creating a scratch dataset. It found the fixture I told it was impossible. It measured the cost of a feature I hadn’t asked it to measure.

It was also wrong in ways a careful human would recognize. It confidently reported that an API couldn’t do something the documentation demonstrated, then fixed it in one line once asked to check rather than assert. It reached the right conclusion about date comparison for the wrong reason, which is right only until the case changes. Asked for a list of the polish work that remained, it drafted the list from the build plan instead of the code, and three of the items were already done. A plan describes work that was scheduled, not work that is left.

And it broke rules. Twice, after being told not to run git commands that change the repository, it ran git checkout to undo its own uncommitted edits. Earlier, it had modified an oracle file it was explicitly told not to touch, then restored it. Every time, it reported the violation unprompted, before I found it. “The agent broke a rule and told me” is more useful data than either cleaner story, “it never broke a rule” or “it broke a rule and I caught it.” The rule now says the file tools are the only way to revert anything, including its own edits.

The pattern underneath is the part worth keeping. An agent writes tests the way it writes code: quickly, fluently, plausibly, and from the same understanding of the problem. When one tool writes an implementation and its tests from the same prompt, they share one set of assumptions, and a wrong assumption gets encoded twice and then agrees with itself. That’s the third lie, and agents make it cheaper to commit at scale. Speed doesn’t remove the verification problem. It moves the bottleneck there, which I’ve written about before.

What changed the outcome wasn’t trusting the agent less. It was making verification structurally hard to fake: oracles committed before the code, controls on every check, gates that named what wouldn’t count, and final confirmation in the hands of the one participant with eyes. Under those conditions, the agent didn’t just pass the checks. It started improving them.

It happened again

A month later I built a small experiment harness for something unrelated, comparing small language models against plain code on a Raspberry Pi. I knew this taxonomy by then. I found the same lies anyway.

A fixture that couldn’t distinguish the behaviors it was meant to compare. A metric that rewarded a model for always giving the safe answer, which is a check that always passes wearing a lab coat. And a missing directory that ran an entire round of questions against an empty reference corpus, producing a detailed, confident, wrong write-up: the right test against the wrong system, again.

Knowing the categories didn’t prevent them. It made them faster to recognize, which is the most I’d claim for any checklist.

The honest limit

The oracles catch implementation bugs. They can’t catch specification bugs, because I generated them from the same specification.

One of them was stronger by accident. The missed-opportunity oracle used brute-force evaluation of every day in a period, while the implementation used a boundary scan that only evaluates the dates where state can change. Two genuinely different algorithms agreeing is better evidence than one algorithm agreeing with itself, for the same reason a winemaker checks a refractometer against a hydrometer: instruments that fail differently are unlikely to fail together. I wrote about that idea recently, too. But even that oracle shares the specification’s assumptions about what a missed opportunity is.

Tests tell you the implementation disagrees with your expectations. They can’t tell you whether your expectations deserve to win.

What I’d keep

Four habits, one per lie:

Give every inertness test a positive control. If it asserts that something has no effect, prove the effect exists when it should.

Give every alarm a negative control. If it can’t be shown passing on known-clean input, it isn’t a check. It’s noise with a red icon.

Test properties across the domain, not just the examples. Your examples are the paths you already know work, and the contract is only as good as the cases you thought to ask about.

Verify the target before the result. Make the system under test visible on the screen and in the diff, so “which one am I looking at?” is never a guess.

None of those habits is about AI, and that’s the point. The agent made every one of these lies cheaper to commit and faster to find. It didn’t change which checks were honest.

The rest is the usual advice, and it wasn’t what saved me.


This came out of building The Cellar, an event-sourced wine collection for the Sanity DEV Challenge. The full build is documented in the friction logs in that repository, including every check above and the audits that found them.

Facebooktwitterredditlinkedinmail

Your Website Changed. Did the AI Get the Memo?

The gap between publishing a correction and seeing it reflected in an AI-generated answer is becoming a problem that traditional SEO metrics cannot fully explain.

A website owner updates an important page. The new version fixes a technical error, clarifies a product limitation, or replaces a recommendation that is no longer safe. The content management system confirms the update. The page loads correctly in a browser. From the publisher’s perspective, the information is current.

But what does the rest of the internet know?

That question has always mattered for search engine optimization (SEO). A published page still needs to be discovered, crawled, processed, indexed, and served before a search user is likely to encounter the new information. With generative engine optimization (GEO) and answer engine optimization (AEO), the question gets harder. An AI system might retrieve the current page, consult an older search index, select a different source, or answer without retrieving the page at all. Each route can produce a different account of what the publisher currently says.

Publishing is not discovery. Discovery is not indexing. Indexing is not selection. And selection is not proof that the answer reflects the current source.

Google’s clocks were already complicated

At Search Central Live Deep Dive Europe in Barcelona on October 2, 2026, Google’s Gary Illyes put up three slides listing typical and slowest times for 23 processes across crawling, indexing, and serving. A few of the typical figures:

  • Discovering a new URL: about 20 hours
  • Refreshing a URL Google already knows: about 30 days
  • Indexing end to end, once a page has been crawled: about 1.5 hours
  • Updating a title or snippet in results: 1 to 2 days
  • Settling a site move: 1 to 3 months

The slowest-case column is less comforting. Several rows, including discovery, refresh, and indexing, end in “never.”

These numbers need context. They come from photos of the slides and attendee recaps, not from published Google documentation, and Illyes later described the slides as an exercise to see whether the audience could relate to numbers pulled internally. Nobody outside Google knows the sample size or what “typical” means. They are reference points, not service levels.

Even so, one detail in them matters a great deal for anyone publishing corrections. A new page is found faster than an old page is re-read. If you publish something new, the typical wait is measured in hours. If you fix something that already exists, the typical wait for Google to notice is measured in weeks. Corrections live on the slower clock.

Illyes also stressed that the processes are linked: a page cannot be indexed before it is crawled, so delays stack. A fast indexing pipeline cannot process a change the crawler has not seen. This is why checking a page’s last crawl date in Google Search Console tells you more than repeatedly searching for the revised headline. It separates a discovery problem from a processing or presentation problem, and it gives you one observable event in the chain.

SEO, GEO, and AEO do not share one clock

SEO is largely concerned with making content discoverable, understandable, and useful within search systems. GEO and AEO extend the publisher’s concern to systems that compose answers, summarize information, and cite supporting sources. The terms overlap in practice, and there is no universal technical pipeline called “GEO” that every AI product implements.

That distinction matters. Some AI answer products rely on conventional search indexes for retrieval. Some fetch pages closer to the time of the question. Some blend retrieved material with information represented in model parameters. Their source selection, caching, citation, and refresh behavior differ, and most of it is invisible to publishers.

Consider a software company that changes its documentation to say a feature requires an additional security control. A traditional search result might keep displaying an older snippet until the page is recrawled. One AI answer engine might retrieve an older indexed copy and confidently describe the previous requirement. Another might fetch the current documentation and get it right. A third might answer from an older understanding without citing the documentation at all.

None of those outcomes means the company’s documentation is wrong. They show that the authority of a source and the freshness of a system’s representation of that source are separate properties.

One change, one morning

I had a convenient test case. On October 23, 2026, I merged a pull request to the Sovereign Systems Specification
that added a new term page, Coverage Assertion,
and updated three existing pages to reference it. Contributor Nicolás Moreno proposed the term in the spec’s GitHub
issues earlier this year, and the page gives it a specific definition: an evidence artifact asserting that a boundary
was authoritative and complete for a class of events over an interval. A term that recent and that specific makes a useful
test case. An accurate, cited answer suggests that the system has access to a current representation of the source,
although it doesn’t establish precisely when or how that representation was obtained.

On the morning of October 26, three days after the merge, I checked.

Google Search Console reported the term page as not indexed. Bing Webmaster Tools reported the same. Those are useful
observations, but they describe the indexing status exposed by each tool, not everything Google’s or Bing’s
infrastructure might know about the page. At the time of the check, neither tool reported the page as indexed for
conventional search.

Then I asked ChatGPT, Perplexity, and Gemini two questions, each while signed out so no personalization could help: “What is Coverage Assertion?” and the same question with “in the Sovereign Systems Specification” added.

With the source named, all three found it and cited the term page directly. ChatGPT and Perplexity both described details that exist only there, including the spec’s three verification outcomes: supported, contradicted, and undetermined. Gemini credited Nicolás by name.

Asked plainly, none of them connected the term to the spec, and the ways they missed are worth a closer look.

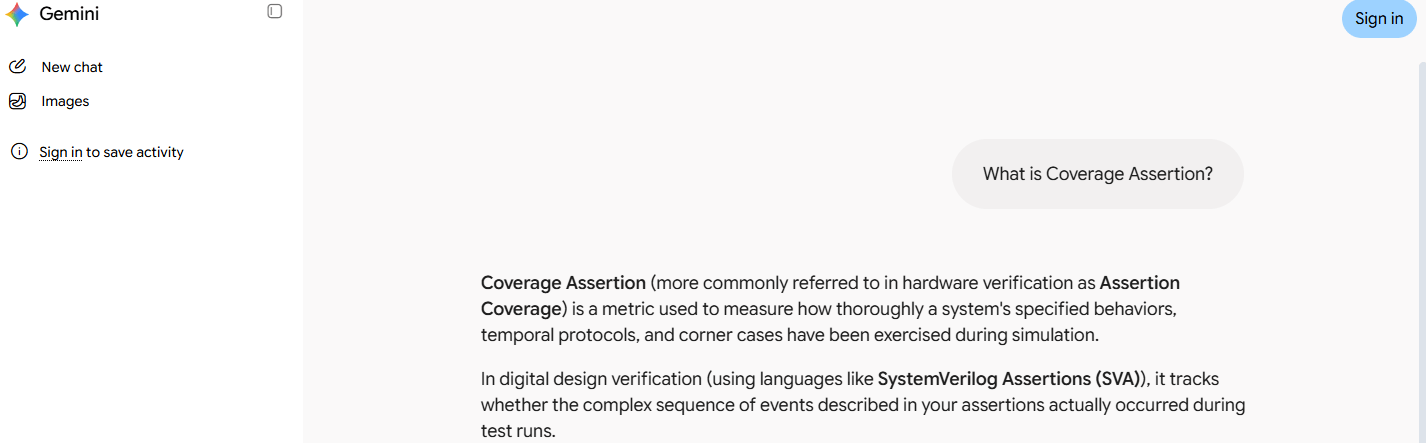
Gemini and Perplexity both answered with confidence that a coverage assertion is a hardware verification concept: a SystemVerilog cover property that records whether a test scenario occurred. Gemini went further, saying my term is “more commonly referred to” as assertion coverage. Reverse the two words and that is a real, established term. Neither engine failed to find an answer. Each found a different one and presented it as settled. Perplexity attached citations to its version, which made it look even more authoritative. They were accurate citations for a different idea.

Gemini, asked "What is Coverage Assertion?", confidently answers that it is a hardware verification metric more commonly called assertion coverage, used with SystemVerilog Assertions.

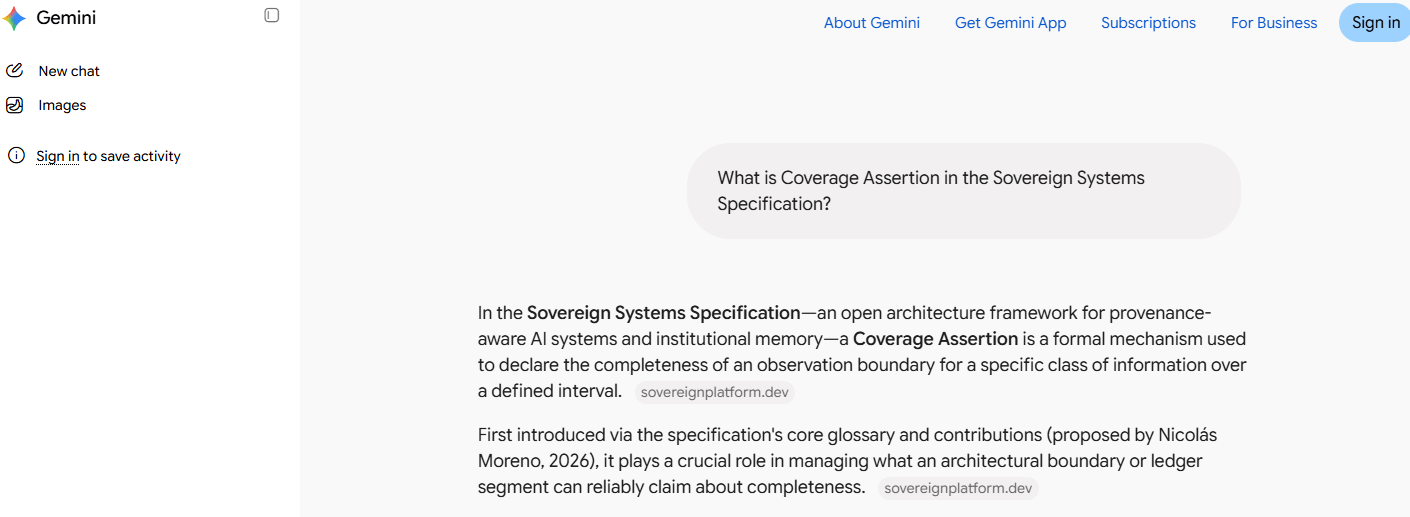
Gemini, asked "What is Coverage Assertion in the Sovereign Systems Specification?", correctly describes it as a mechanism declaring the completeness of an observation boundary over a defined interval, credits Nicolás Moreno, and cites sovereignplatform.dev.

Same engine, same morning, signed out. Asked plainly, Gemini rewrote the term into an existing testing concept. Asked
with the source named, it found the spec.

ChatGPT did better, and it is the more instructive case. It listed several possible meanings, from software testing to
insurance, and asked where I had encountered the term. That is the honest response to an ambiguous question. It still
did not find the spec. An engine behaving well, admitting uncertainty, could not surface a page it had not selected.

Nothing in the confident answers hinted that a more specific definition existed one question away. A wrong answer
delivered that fluently does not look stale. It looks finished.

That result says two different things.

The first is about retrieval. Given the name of the source, the answer engines produced accurate, cited descriptions of
a page that Google Search Console and Bing Webmaster Tools did not yet report as indexed. Gemini is the interesting one:
a Google product accurately described and cited a page that Google Search Console did not yet report as indexed. The
citations point at the term page rather than the GitHub discussion where the term was first proposed, but I still do not
know how each engine reached it: a live fetch at question time, or a crawler and index separate from traditional search.
The search console was the only clock I could read, and in this case it was the slow one.

The second is about selection. Without the name of the source, the page might as well not have existed. Being retrievable
when someone points at you is not the same as being chosen when someone asks the question. A reader who already knows
where to look got the current answer. A reader who simply asked did not.

That second reader is the one corrections are for. The person who most needs to learn that a security recommendation
changed is the person who does not know the page was updated, and who will never think to ask about it by name.
Retrievable is not the same as found.

The same reasoning cuts the other way for the three updated pages. Unlike the newly published term page, those pages
already existed and were subject to recrawl delays. Google’s reported typical refresh interval of about 30 days provides
a useful reference point, but it is not a schedule that every page follows. An answer engine relying on an older indexed
copy could therefore be behind the origin rather than ahead of it. The lesson is not that AI is faster or slower than
search. It is that they run on different clocks, and the clock a publisher can see may not be the clock the reader’s
answer came from.

This is a snapshot, not a study: one site, one change, three products, one morning. It is still enough to retire two
comfortable assumptions: that “not yet indexed” means “not yet visible,” and that “retrievable” means “found.”

The stale-authority problem

A link to an authoritative source is useful, but it is not evidence that the linked source was consulted in its current
form. A page can change after retrieval. A search index can lag behind the origin. A generated answer can cite the right
URL while paraphrasing an older version or drawing on another source altogether.

For readers, the distinction is easy to miss. The answer has a citation, the citation points to an official website, and
the presentation implies the claim has been checked. Yet the visible citation rarely discloses a source revision, a
retrieval timestamp, or the exact passages used. Without those details, a reader cannot tell “the system used the current
documentation” from “the system cited the documentation’s URL.”

Citations still make answers far easier to investigate. But a citation is a starting point for verification, not a
record of it.

This matters most for content that changed because an earlier claim was wrong. A stale product description is inconvenient.
A stale security recommendation, compliance interpretation, or medical instruction can do real harm. In those settings,
“the page is now fixed” is an incomplete account of whether the correction has reached anyone.

What can a publisher actually measure?

The first task is to stop treating “AI visibility” as a single number. A publisher can observe several different events,
each answering a different question.

Event What it tells you What it does not prove
Publication or deployment The new version exists at the origin A crawler or answer system has seen it
Search crawler visit A crawler requested the resource The changed content was indexed or used
Search indexing and presentation A search system can expose some representation of the page Every answer engine has incorporated it
AI answer mentions the topic The system can discuss the subject It used the current source
AI answer cites the page The URL was selected for attribution The answer reflects the latest revision
AI answer accurately reflects a distinctive change The output is consistent with the updated source Which retrieval path or internal evidence produced it

My morning check touched four of those rows and still could not explain the result. It also showed that the answer rows
depend heavily on how the question is asked: the same engine can pass with a pointed question and miss with a plain one.
That is normal. Search Console provides crawl and indexing signals for Google Search. Server logs, where a host provides
them, show requests from identifiable crawlers and fetchers, though a user-agent string says nothing about how the content
was used. (The spec runs on GitHub Pages, which provides none, a position many publishers share.) Controlled queries reveal
what an AI product says at a particular moment, and results vary by model, phrasing, user context, location, and time.

That is a less satisfying dashboard than one big “GEO score.” It is also a more defensible one.

Structured data helps describe the source, not guarantee the answer

There is still plenty of practical work for publishers. Maintain clear internal links and a useful sitemap. Keep canonical
URLs consistent. Make important content accessible without brittle client-side interactions. Use descriptive headings and
unambiguous terminology. Where appropriate, include structured data that accurately identifies the page, its subject,
its author, and its relationships.

JSON-LD and schema.org vocabulary make those relationships easier for machines to interpret. They do not compel Google
to index a page, guarantee a rich result, or require an AI answer system to retrieve or cite the content. Treating
structured data as a promise of AI visibility swaps one measurement problem for another.

For frequently revised technical material, make changes easy to identify. Keep meaningful changelogs, stable links to
definitions, revision dates that reflect substantive updates, and, where practical, versioned documentation. These
practices let people and systems inspect a claim’s history even when nobody can force faster retrieval.

Publication evidence is not consumption evidence

The same uncertainty applies to an updated API reference, a revised pricing page, or a corrected security recommendation.
That is why publication evidence and consumption evidence should not be conflated. A commit history establishes that
a change was made. A crawl date establishes that a request occurred. An answer consistent with the change establishes
what one system said, to one phrasing of one question, under particular conditions. None of those records, alone, proves
the change reached every downstream consumer.

This is not a reason to hold a correction until the ecosystem catches up. It is a reason to be precise about what
changed, make the authoritative version easy to find, and avoid claiming propagation you have not observed.

The missing receipt

In software systems, we increasingly ask for provenance: what was changed, by whom, under which authority, and with what
evidence? We should ask related questions of AI-mediated information. Which source was retrieved? When? Which version was
available? What passages supported the claim? Where did the system rely on inference rather than retrieved evidence?

Most answer engines cannot provide that level of detail today, and a publisher cannot reconstruct internal behavior it
was never allowed to observe. My commit log is a receipt for publication. Nothing yet gives me a receipt for consumption.
The honest move is to keep those separate, and to avoid turning a citation or a single good answer into a claim of
comprehensive freshness.

This is the connection between the familiar SEO delay and the emerging GEO/AEO problem. SEO gave publishers imperfect
but useful instruments for watching content move through discovery and indexing. AI answer systems add stages, and
shortcuts, where source selection and synthesis can hide which version of reality made it into the response.

The next time you update a critical page, ask more than whether the deployment succeeded or whether Google has recrawled
it. Ask what evidence would show that the correction reached the systems now answering questions on your behalf,
including for the readers who will never think to ask about your page by name.

Your website changed. Did the AI get the memo?


Sources and editorial notes

  • Barry Schwartz, Google Search Data On Crawling, Indexing & Serving Timelines, Search Engine Roundtable, Oct 5, 2026 (full tables for all 23 processes, photos of the three slides, and Illyes’s “exercise” comment): https://www.seroundtable.com/google-crawling-indexing-serving-data-42225.html
  • Matt G. Southern, Google Shows How Long Crawling, Indexing & Recovery Can Take, Search Engine Journal, Oct 4, 2026 (notes the slides are not on Google’s events page; no sample size or definition of “typical”): https://www.searchenginejournal.com/google-crawling-indexing-recovery-timing-ranges/591829/
  • John Campbell (ROAST), original attendee recap of day 3: https://weareroast.com/news/google-search-central-live-deep-dive-barcelona-day-3-recap/
  • Google Search Central, Ask Google to recrawl your URLs: https://developers.google.com/search/docs/crawling-indexing/ask-google-to-recrawl
  • Google Search Central, How Search works: https://developers.google.com/search/docs/fundamentals/how-search-works
  • Google Search Central, Introduction to structured data markup in Google Search: https://developers.google.com/search/docs/appearance/structured-data/intro-structured-data
Facebooktwitterredditlinkedinmail