Living a Colorful Life in a Black-and-White ATS World

A career has edges. The schema only stores nodes.

I spent years in commercial kitchens and over a decade running a one-man construction business before I ever shipped software professionally. Here is what those years look like inside an applicant tracking system:

Sous Chef, Illahe Hills Country Club, 1996-1997
Owner, Alger Construction, 2006-2018

Two rows. Six fields. Everything that made those years worth putting on a resume in the first place lives in the space between them, and there is no field for the space between them.

That is not a bug in any particular vendor’s product. It is what happens when a career gets stored.

Compression Is the Point, and Compression Has a Cost

A resume is already a lossy representation of a working life. An applicant tracking system compresses it again into titles, employers, dates, skills, and years of experience. Recruiter searches narrow it further. Screening criteria narrow it again. By the time a hiring manager sees a candidate, a great deal of what made that person worth meeting has been discarded by systems doing exactly what they were built to do.

Hiring at scale requires structure. Nobody sensible is arguing otherwise.

But compression is only lossless when the thing being compressed matches the schema. Software engineer becomes senior software engineer becomes staff software engineer. The titles line up. The keywords line up. The progression survives the trip through the pipeline nearly intact.

For a career that moved sideways, the same pipeline behaves very differently. It preserves the least interesting facts and drops the reason those facts belong on the same page.

The Resume Contains the Nodes. Something Has to Explain the Edges.

Running a construction business teaches you schedules, budgets, vendors, dependencies, unhappy customers, and what it costs to discover a problem after the wall is closed. Working a station on a busy line teaches you sequencing, preparation, and how to communicate when six things are failing at once and none of them are your fault. Managing a distributed technical team a decade later draws on both, whether or not the job description has a checkbox for it.

Systems fail. Priorities collide. Resources are finite. People misunderstand each other. Plans meet reality. Learning to operate under those conditions is transferable, and it is the actual content of a nonlinear career.

A person reading a resume can sometimes reconstruct those connections. A parser has a harder problem, because almost everything it has been given is categorical. It is very good at representing what fits in a field. It has nowhere to put “running a small business taught me something about operational risk that later made me better at managing engineers.”

The information exists. The schema has no column for it.

This is why the quiet disappearance of the cover letter is more consequential than it looks. I understand why nobody misses them. Most were three paragraphs about being passionate about synergizing solutions in a fast-paced environment, and they earned their reputation. But the format was carrying a load that nothing replaced. The more nonlinear the candidate, the more of their value lives in relational information, and the application form keeps getting narrower precisely where that information needs to go.

We tell people to bring their whole selves to work while steadily reducing the bandwidth available to transmit one through the front door.

The Strongest Objection Is Not Efficiency

The honest counterargument to everything above is not that narrative is slow to read. It is that narrative is where bias lives.

Structured screening was partly a correction. Unstructured hiring, the kind that runs on interesting backgrounds and good conversations and a hiring manager’s instinct about fit, has a well documented tendency to favor candidates who resemble the person doing the evaluating. “This person’s unusual path is fascinating” has historically meant “this person reminds me of me.” Fields, rubrics, and consistent criteria were a response to a real failure, not an accident of software convenience.

So the argument cannot be that we should bring back the cover letter and read it with an open heart. That is a request to reopen a door that was closed for a reason.

The argument is narrower, and I think it survives the objection: the correction discarded a category of information instead of evaluating it consistently. Those are different problems with different fixes. Consistency is achievable for prose. Ask every candidate the same question. Score the answers against the same rubric. Read them at the same stage. That is structured data that happens to arrive as sentences.

What we built instead was a process that solved the bias problem by deleting the input.

The Keyword Arms Race Is a Symptom of the Deletion

The predictable response has been optimization on both sides. Candidates tailor resumes to postings. Tools score keyword alignment. Generative models rewrite bullets in the vocabulary of the job description, while recruiters deploy increasingly sophisticated matching and ranking on the other end.

None of that is unreasonable in isolation. If a company says “developer enablement” and my resume says “developer education,” making that equivalence explicit helps humans and machines alike.

Taken far enough, though, the process gets strange. One model rewrites a person’s career into the vocabulary most likely to satisfy another model deciding whether a human being should ever see it. We have built a translation layer between two parties who could have had a conversation.

And the translation runs in one direction only. Optimizing for machine legibility strips out exactly the information companies claim to be looking for. Adaptability is messy. Cross-disciplinary experience is messy. Pivots are messy. That messiness is usually where the signal is.

A Hiring Process Is a Statement of What an Organization Preserves

It is easy to blame the ATS, because it is the visible machinery. It is also the least interesting part of the story.

Someone decides which fields matter. Someone writes the screening questions. Someone marks a qualification as required rather than preferred. Someone chooses how recruiters query the pool, and whether a hiring manager sees fifty candidates, ten, or only the five that most closely resemble the profile used to write the posting. And someone decides you will never be told which of those things happened to you.

The resulting process is not neutral. It is a record of what an organization decided was worth keeping.

A process that preserves titles, years, and exact skills while discarding explanation will reliably favor careers legible through titles, years, and exact skills. A process that rewards similarity to a predefined profile will filter out candidates whose value comes from unusual combinations, because unusual combinations are by definition dissimilar.

For plenty of roles that is fine. Nobody wants an airline hiring pilots because the career story was compelling.

It is harder to defend when the same organization says it is looking for adaptable leaders, systems thinkers, creative problem solvers, and people who challenge established assumptions. Those are all contextual qualities. Context is the first thing lossy compression throws away.

We Do Not Need Better Resume Optimizers

I have not solved hiring, and candidates still have to operate inside the system that exists. Make transferable skills explicit. Describe outcomes in the language of the role. Find a human being when you can. A nonlinear career does not become legible because we insist it deserves to be.

But another generation of tools that help candidates compress themselves more efficiently is not a fix. It is better compliance with the thing causing the problem.

The smaller fix is available today and costs almost nothing. One field, asked of every applicant, scored the same way: what connects these experiences, and what did you carry from one to the next? Two hundred words. Read before the rejection, not after the offer. It is consistent, it is auditable, and it gives relational information somewhere to exist inside a structured process rather than outside it.

If an organization genuinely believes that unconventional backgrounds and adaptable thinkers create value, its hiring process needs a place to put them. Not in the culture page. In the schema, where decisions actually get made.

Otherwise, “bring your whole self to work” carries an undocumented prerequisite:

First, make sure your whole self fits in the fields.


P.S. I have also prepared my curriculum vitae in Latin. Thirty-five years of experience, zero recoverable keywords, and one very specific classics-major-turned-recruiter out there who will open it and say: hic est candidatus quem exspectabam.

Facebooktwitterredditlinkedinmail

The Contract Discovery Bottleneck

AI can generate the code. We can verify the behavior. But who decides
what correct means?

I wrote recently about a coding agent that built me a password reset
flow with a reset link that worked more than once.

The bug survived because nobody had written down that a reset link
should be single use. It was obvious right up until it wasn’t.

My argument was that as AI makes implementation cheaper, verification
becomes the bottleneck. The feature request said “build password reset.”
The agent built password reset. The happy path worked. The tests passed.
The implementation looked finished.

What nobody had asked was whether the same reset link should work twice.

So I added an independently written behavioral specification. The agent
implemented against it. The verifier rejected the reusable token. The
agent fixed the implementation. The verifier passed it.

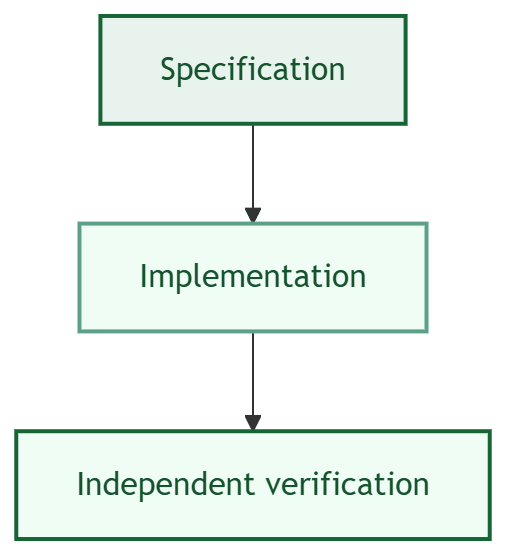
That seemed like a useful pattern:

Flowchart showing three sequential stages: a specification leads to an implementation, which leads to independent verification.

Then I published the article, and the comments started finding things my
specification didn’t say. That exposed a harder problem.

The specification wasn’t finished either

One reader asked what would happen if two password reset requests using
the same token arrived at the same time.

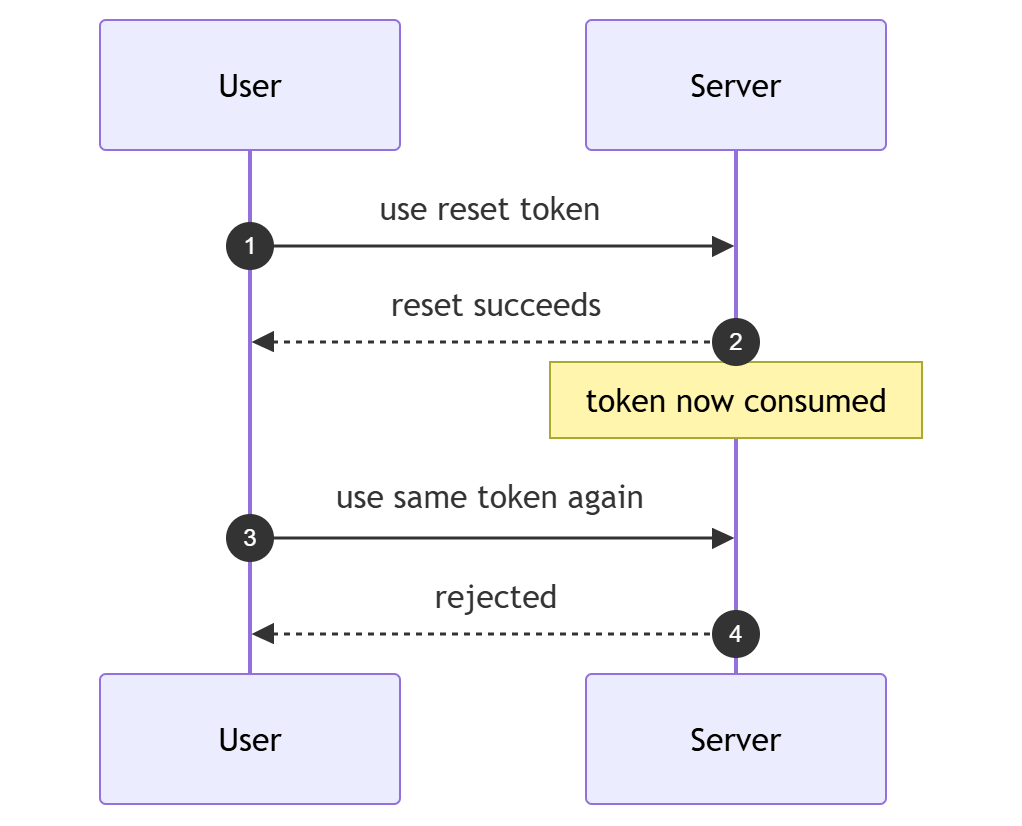
I hadn’t tested that. My test covered sequential reuse:

Sequence diagram showing a user using a password reset token successfully, the server marking the token consumed, and a second attempt with the same token being rejected.

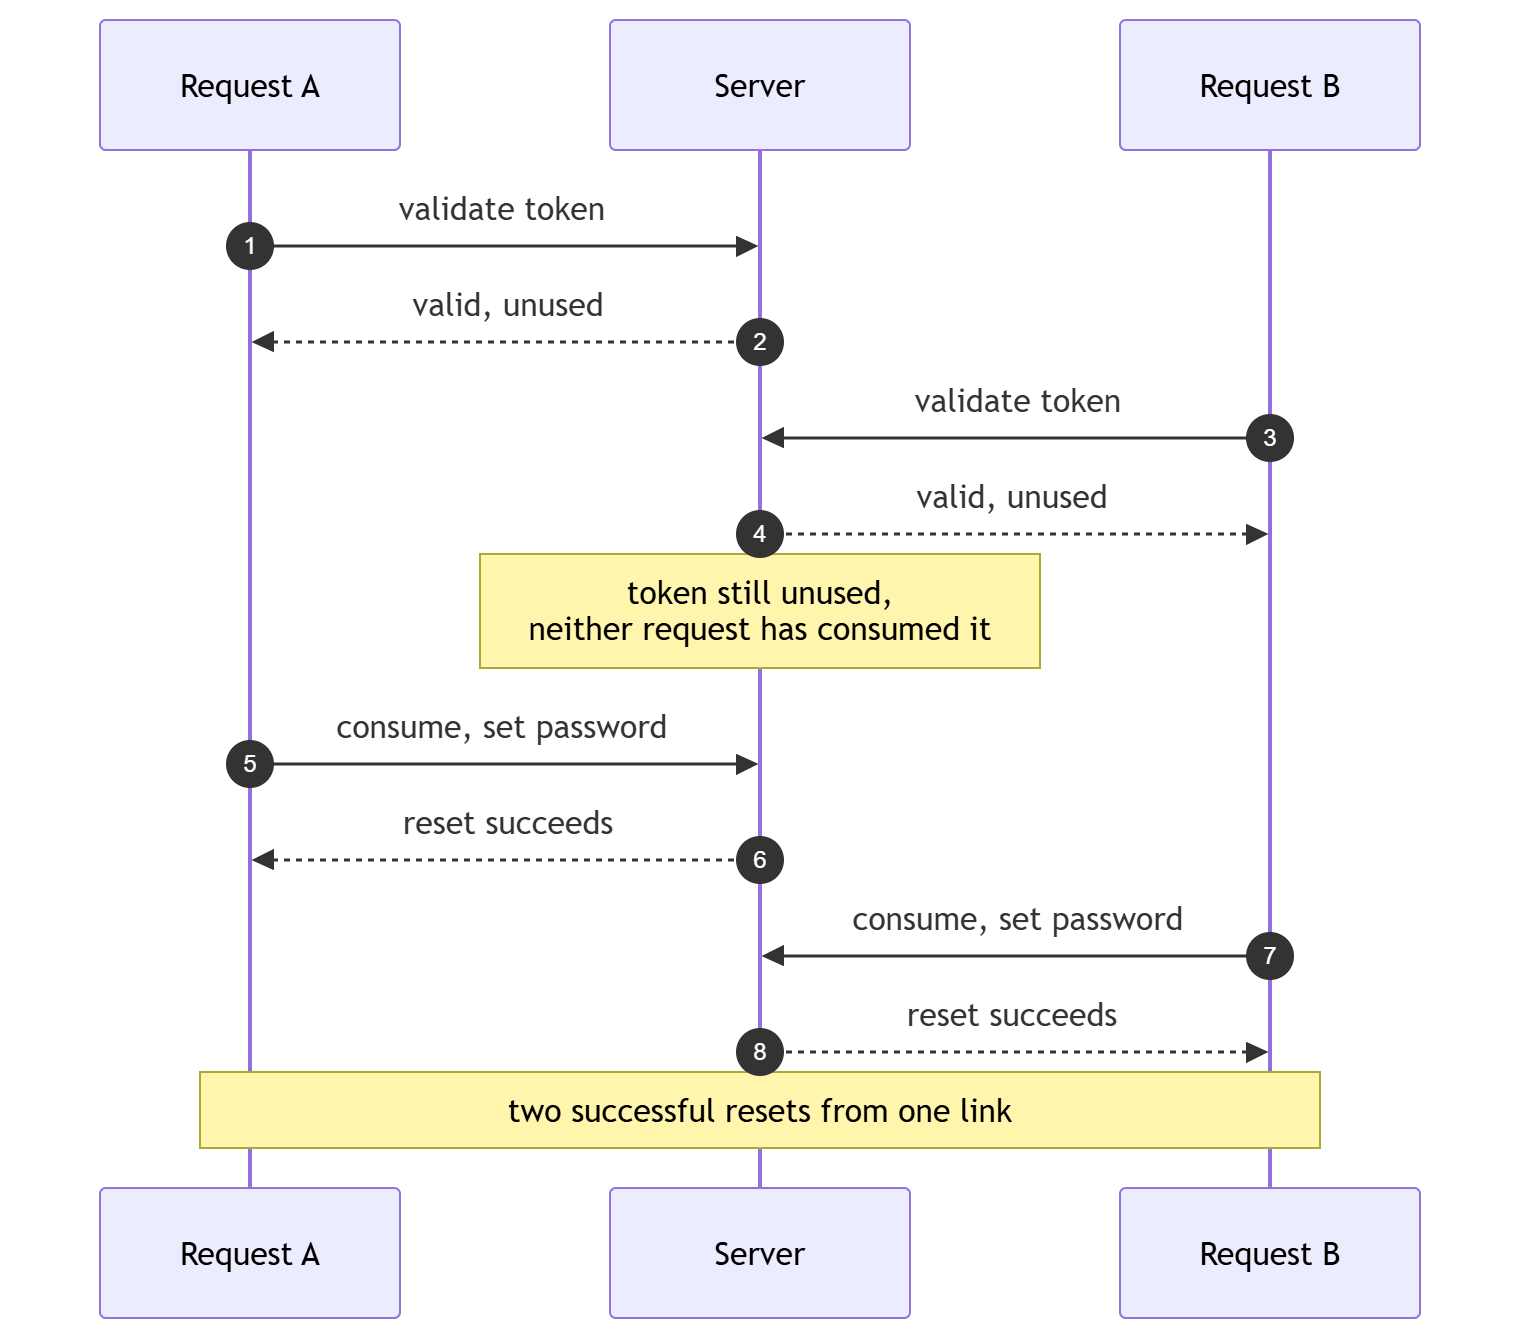
But concurrent reuse is different:

Sequence diagram showing two concurrent password reset requests. Request A validates the token and the server reports it unused. Request B validates the same token before A has consumed it, and the server again reports it unused. Both requests then consume the token and both resets succeed, producing two successful resets from a single link.

Both requests check the token while it is still unused. Both proceed.
If validation and consumption are not a single atomic operation, “single
use” can still produce two successful resets.

The original invariant was incomplete.

That doesn’t make the specification useless. It makes the specification
provisional.

The interesting part is where the new knowledge goes.

Once somebody discovers that “single use” also means competing attempts
cannot both succeed, that should stop being knowledge held by the person
who noticed it. It belongs in the durable definition of correct
behavior.

The specification changes.

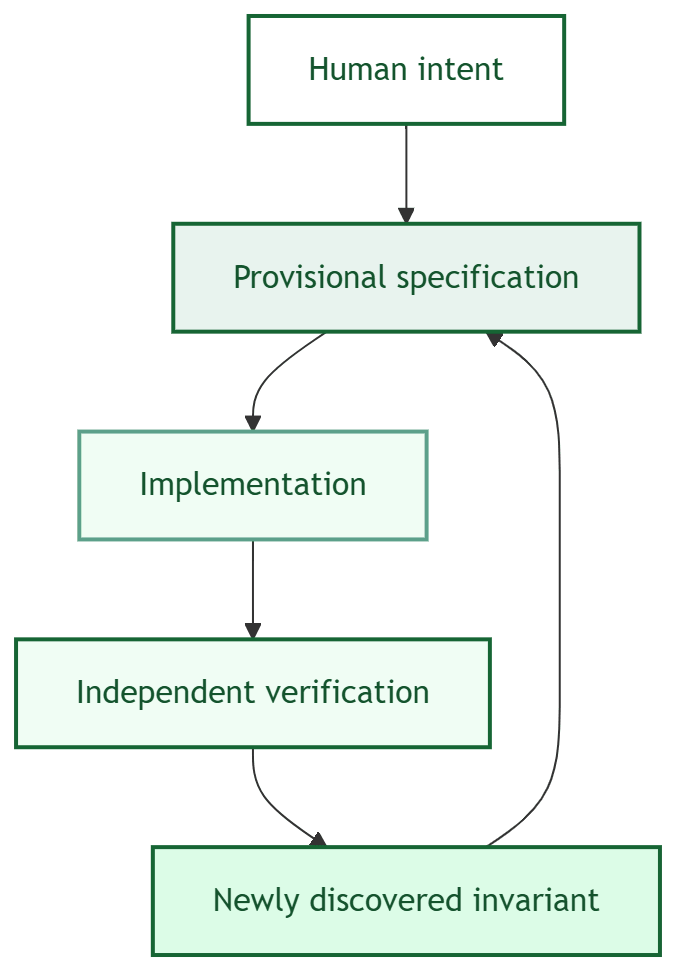
Which means the loop is really closer to this:

Flowchart showing a cycle. Human intent produces a provisional specification, which leads to an implementation, then to independent verification. Verification surfaces a newly discovered invariant, which feeds back into the specification, and the cycle repeats.

That is messier than the first diagram.

It is also much closer to engineering.

Separate tests can share the same mistake

Another reader described an integration builder where an agent wrote
both a connector and the tests for that connector.

Everything passed.

Both were wrong.

The connector and its tests encoded the same incorrect assumption about
OAuth token refresh. The mistake only surfaced when a customer’s token
expired during a live session.

The implementation and test suite were separate artifacts. They were not
independent in the way that mattered.

They shared an assumption.

That distinction matters because “independent verification” can sound
like an organizational property:

  • different file
  • different test suite
  • different agent
  • different step in the pipeline

None of those necessarily provides independence.

If the implementation and verifier derive their definition of correct
behavior from the same incomplete prompt, they can agree perfectly and
still be wrong.

The student is no longer literally grading the same exam.

Two students have simply studied from the same incorrect answer key.

Generating more tests doesn’t discover the missing rule

Another commenter asked whether property-based testing or giving an
agent an adversarial security persona might do a better job uncovering
these unstated constraints.

I think both are interesting, but they expose the same boundary.
Property-based testing can explore a stated invariant extremely well.

If I tell a framework:

A successfully consumed reset token must never produce another
successful reset.

it can generate combinations and sequences I would never think to
hand-author.

But it cannot tell me that single use was a requirement if nobody
expressed it.

An adversarial agent has a similar problem. Asking a model to “try to
break this” may produce better tests than asking it to “write tests for
this feature.” But if the adversary shares the same context, model
assumptions, and incomplete understanding of the requirement, how
independent is it really?

The question starts shifting from who writes the tests? to a more
difficult one: where does the definition of correct behavior come
from?

The verifier can be wrong too

One of the most interesting examples in the discussion came from a
verification harness rather than generated application code.

A capability test timed out.

The harness recorded the result as a failure.

But a timeout did not establish that the capability failed. It
established that the harness did not obtain a result within the allotted
time.

Those are different claims.

FAILED

and

NOT TESTED

are not interchangeable.

The verifier had turned an observation failure into an assertion about
capability.

That’s a useful warning for any architecture built around deterministic
verification: deterministic does not mean correct.

A verifier can enforce the wrong invariant with absolute consistency.

So can a specification.

The goal isn’t to replace an unreliable agent with an infallible
verifier. There is no infallible verifier.

The goal is to make the definition of correctness explicit enough that
it can be inspected, challenged, tested, and revised independently of
the implementation.

So who writes the contract?

This was the question that pushed the argument furthest for me.

If humans have to write complete behavioral specifications before agents
can implement anything, haven’t we simply moved the bottleneck back to
humans?

Probably.

And worse, the concurrency example demonstrates that humans don’t
necessarily know the complete specification beforehand either.

So “humans write the contract” isn’t much of an answer.

An agent could propose it.

That sounds circular at first. If the agent proposes the implementation
and proposes the contract, aren’t we back to the student grading the
exam?

Only if proposing the contract and accepting the contract are the same
operation.

They don’t have to be.

An agent might generate a candidate operating contract:

reset token:
  may be used once
  competing attempts cannot both succeed
  expires after N minutes
  cannot authorize a different account

A human, another system, or some combination can then challenge that
much smaller artifact.

The question being reviewed becomes:

Is this an adequate definition of correct behavior?

rather than:

Is this entire implementation correct?

That doesn’t solve the trust problem, but it reduces its surface area.
Reviewing four lines is a different activity than reviewing four hundred.
One is a conversation about intent. The other is an audit.

But this runs straight back into the answer key problem.

If the same model that will implement the feature also proposes the
contract, they share assumptions. An agent that doesn’t know single use
matters won’t propose single use as an invariant. It will produce a
confident, well-formatted contract with the same hole in it, and now the
hole has been written down and approved.

So accepting a contract has to do more than approve it. It has to
introduce something the proposing agent didn’t have.

That might be a person who has debugged this class of bug before. It
might be a genuinely different model, though I’m unsure how much
independence that buys. It might be a checklist derived from past
incidents, which is really institutional memory in a form an agent can
read. For a reset token, somebody’s list somewhere already says: single
use, expiry, no account substitution, no concurrent success, session
invalidation.

The value comes from the independence of the source, not from the
ceremony of the review.

That may be a more tractable thing to build tooling around than
verification itself.

Maybe verification isn’t the deepest bottleneck

This is where the comments changed my framing.

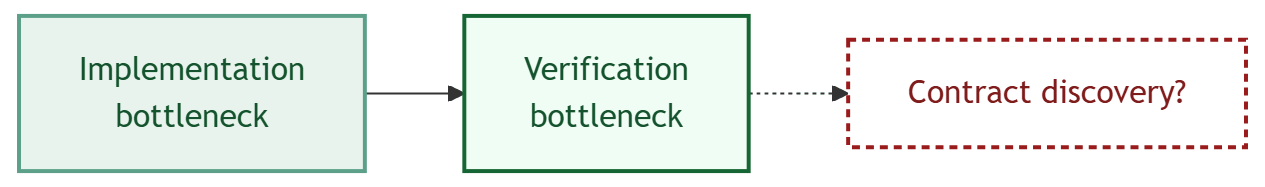
I started with:

Flowchart showing the implementation bottleneck leading to the verification bottleneck, with a dashed arrow to a third stage labeled contract discovery, marked as an open question.

I’m less sure that’s where it stops.

Once implementation is cheap and verification is increasingly
automatable, the harder problem may become discovering the invariants
worth verifying.

Call it contract discovery.

The requirement says:

Reset my password.

Somebody has to discover:

The link works once.

Then:

Two concurrent attempts cannot both succeed.

Then perhaps:

The token cannot authorize a different account.

A token issued before another successful reset may no longer be valid.

A reset invalidates existing sessions.

Some of those are product decisions. Some are security properties. Some
are implementation-independent behavioral invariants. Some may not apply
at all.

The difficult work is deciding which ones belong to the definition of
correct.

AI can help propose them.

Property-based testing can explore them.

Deterministic systems can enforce them.

Production incidents will unfortunately discover some of them for us.

But none of those eliminates the need to decide which claims actually
define correctness.

This gets harder when agents start acting

There is another reason I think this matters beyond generated code:
agents don’t just write things anymore. They call things.

An agent calls an API. The response is 200. The agent moves on.

But a 200 says the request was processed. It doesn’t say the
constraint the agent’s plan depended on was enforced. Maybe the call
timed out after the write succeeded, so the retry performed the effect
twice. Maybe the operation was legitimate the first time and should have
been rejected the second.

That second one should look familiar. It’s the reset link, one layer
out.

A bad implementation leaves an artifact somebody can inspect later.

A bad tool call already happened.

It sent the email. Charged the card. Revoked the access. Posted the
message.

There is no diff to read.

This is where the contract-discovery problem becomes more consequential.
The system needs some definition of what the agent is permitted to cause
and what evidence would establish that the intended effect actually
happened.

I don’t think I have the architecture for that yet, but one boundary is
becoming clearer:

The specification can be agent-readable without being agent-owned.

The agent should be able to see the invariant. Withholding the
requirement only makes the work guesswork.

But the agent shouldn’t be able to quietly redefine the invariant when
satisfying it becomes inconvenient.

Whatever accepts, stores, and evaluates the contract needs some
independence from the reasoning that produced the implementation or
action.

Where that boundary belongs remains a harder question.

The specification is durable because it can change

Calling the specification a durable artifact can sound like calling it
an immutable one.

I don’t mean that.

A durable specification should change when we learn something about what
correct behavior actually requires.

What makes it durable is that the knowledge survives the implementation
that taught us the lesson.

The reset implementation may be rewritten next month.

The framework may change.

The agent may change.

The database may change.

But once we’ve established that two competing reset attempts cannot both
succeed, that invariant should survive all of them.

The same applies to an integration. Once a production failure teaches us
what token refresh must guarantee, that knowledge should not remain
attached to the incident report or the engineer who debugged it.

It should become part of what “correct connector” means.

The implementation may be disposable. The accumulated definition of
correctness is not.

I still don’t think this is solved

There are plenty of uncomfortable questions left.

How independent does a verifier have to be?

Can two agents using different prompts but the same underlying model
provide meaningful independence?

Who accepts an agent-proposed contract?

How do you distinguish a genuine product invariant from an
implementation detail that shouldn’t survive the current code?

What happens when two valid invariants conflict?

How do contracts evolve without quietly weakening previous guarantees?

And how do we verify effects in external systems where state is delayed,
partially observable, or distributed?

I don’t have good answers to all of those. That’s partly why I don’t
think the answer is simply “write better tests.” The tests are
downstream of the harder question.

Write down what you mean by correct

The original password-reset bug happened because a rule existed in
someone’s head and nowhere else.

The comments on that experiment showed the next problem: writing down
one rule doesn’t mean you’ve found all the others.

That’s fine. The specification doesn’t have to arrive complete. It has
to provide somewhere for discovered invariants to go, and that somewhere
has to be a place with a history: versioned, reviewable, and attached to
the behavior rather than to the incident that revealed it.

Maybe an agent proposes them. Maybe a human notices them. Maybe
property-based testing exposes them. Maybe an independent reviewer asks
the annoying question nobody else asked. And sometimes production will
teach us the expensive way.

The important part is that each discovery makes the durable definition
of correct behavior better.

AI is making it remarkably cheap to turn an instruction into working
code.

Verification asks whether the code did what we said. Contract discovery
asks whether we said enough. I’m starting to think that’s the harder
problem.

Facebooktwitterredditlinkedinmail