Your AI Agent Shouldn’t Be Allowed to Write Whatever It Wants

Building a Write-Side Custody gate in Go

AI memory systems spend most of their design budget on retrieval. Which vector database? How should we chunk? Which embedding model? What should top_k be?

Those are useful questions, but they all arrive after something more consequential has already happened: the system decided that some piece of information deserved to become memory.

Consider an agent researching vendors for regulated workloads. It finds this statement:

Vendor X is approved for regulated workloads.

The source is Vendor X’s own marketing site.

The statement might be true. It might even be current. But the source does not have the authority to establish organizational security policy. If our agent writes it directly into durable memory, better retrieval will not save us. We have only made questionable evidence easier to find.

The problem is not storage. It is admission.

I’ve been calling the architectural boundary responsible for that decision Write-Side Custody. Let’s build a small one in Go.

What Write-Side Custody Does

A storage API answers a mechanical question:

Can I persist this object?

Write-Side Custody asks a different set:

  • Who is trying to write this?
  • Where did the information come from?
  • What authority is being claimed?
  • Is that source allowed to establish that authority?
  • Does policy permit this class of information to become durable?
  • What evidence should survive the decision?

Only after those are answered should storage become involved.
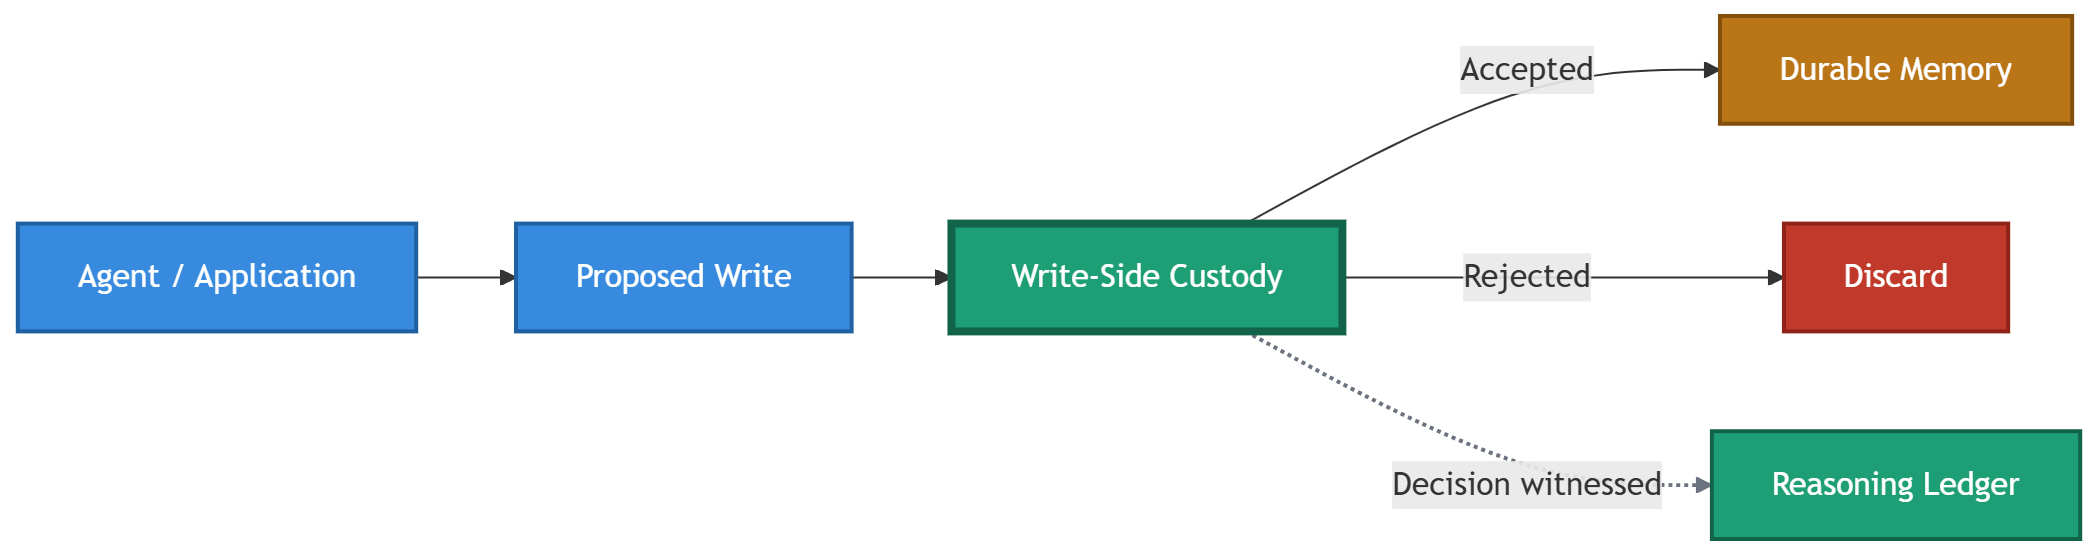
Flowchart showing a proposed write travelling from an agent or application into a Write-Side Custody gate. The gate routes accepted writes to durable memory and rejected writes to discard, while a dotted line records the decision in a Reasoning Ledger.

Note that the Reasoning Ledger does not make the decision. Custody enforces. The ledger witnesses. That separation matters a great deal once these systems have to be examined later.

Start With the Proposed Write

Go gives us a useful property for this experiment: we can make the things crossing our boundary explicit.

type ProposedWrite struct {
    Content          string
    Source           string
    ProducedBy       string
    ClaimedAuthority string
}

Our research agent might produce:

write := ProposedWrite{
    Content:          "Vendor X is approved for regulated workloads.",
    Source:           "https://vendorx.example.com/why-vendorx",
    ProducedBy:       "research-agent-run-4471",
    ClaimedAuthority: "security-policy",
}

Nothing in this structure says the statement is false, and that’s intentional. Write-Side Custody is not a universal truth detector. It determines whether a proposed write satisfies the rules governing this particular memory system.

For this system, a vendor marketing page cannot establish internal security policy. So we need policy.

Make Authority Explicit

First, two types. Authorities and source classes are different kinds of thing, and there is no situation in which we want to accidentally use one where the other belongs:

type Authority string
type SourceType string

Now we can define which source classes may establish which authorities:

type Policy struct {
    AuthoritySources map[Authority][]SourceType
}

var policy = Policy{
    AuthoritySources: map[Authority][]SourceType{
        "security-policy": {
            "internal-security-policy",
            "security-authority",
        },
        "user-preference": {
            "user",
        },
        "application-state": {
            "application",
            "runtime",
        },
    },
}

In production this comes from a policy service or configuration layer rather than a Go literal. The important part is that the relationship exists independently of whatever the agent claims. The agent does not get to decide that a marketing page constitutes security authority simply because it found one saying something useful.

Give the Gate a Verdict

type Verdict string

const (
    Allow Verdict = "ALLOW"
    Deny  Verdict = "DENY"
)

type CustodyDecision struct {
    Verdict   Verdict
    Reason    string
    Timestamp time.Time
}

Now the gate itself:

func EvaluateWrite(
    write ProposedWrite,
    sourceType SourceType,
    policy Policy,
) CustodyDecision {
    allowedSources, ok :=
        policy.AuthoritySources[Authority(write.ClaimedAuthority)]

    if !ok {
        return CustodyDecision{
            Verdict:   Deny,
            Reason:    "unknown claimed authority",
            Timestamp: time.Now().UTC(),
        }
    }

    for _, allowed := range allowedSources {
        if sourceType == allowed {
            return CustodyDecision{
                Verdict:   Allow,
                Reason:    "source may establish claimed authority",
                Timestamp: time.Now().UTC(),
            }
        }
    }

    return CustodyDecision{
        Verdict:   Deny,
        Reason:    "source cannot establish claimed authority",
        Timestamp: time.Now().UTC(),
    }
}

Two decisions in there are worth surfacing.

The first is that conversion on the map lookup. ProposedWrite holds plain strings because that’s what arrives over the wire, deserialized from JSON we did not write. Authority(write.ClaimedAuthority) is the moment an untrusted string becomes a term in our governance vocabulary, and it happens inside the gate rather than at the edge of the process. That’s the right place for it. Custody is precisely the layer where foreign input earns domain meaning.

The second is that sourceType is a separate parameter. It is not a field on ProposedWrite.

That is deliberate. Source classification is a judgment about the write, not a property the writer gets to assert about itself. If sourceType lived on the struct, our agent could label its own marketing page internal-security-policy and the gate would cheerfully agree. The classifier belongs to the custody layer, or to a runtime component that can independently observe where the content came from.

Small signature choice. Most of the security property.

Our vendor claim now reaches the boundary:

decision := EvaluateWrite(write, "vendor-marketing", policy)

fmt.Println(decision.Verdict)
fmt.Println(decision.Reason)

And receives:

DENY
source cannot establish claimed authority

The statement never becomes durable memory. We did not store questionable evidence and hope retrieval would eventually sort things out. We governed the write while the evidence and its provenance were still in hand.

The full gate, the policy, and a table-driven test suite covering the cases above are in memory-stack-patterns. Standard library only, so go test ./... and go run ./cmd/demo work on a clean checkout with nothing to install.

Don’t Throw Away the Rejection

Rejecting a write does not make the decision useless.

Imagine someone asks six months later:

Why doesn’t the system remember that Vendor X was approved?

“I don’t know” is not a satisfying answer, and in a regulated environment it isn’t an acceptable one either.

The custody decision is observable system behavior, which makes it a candidate for a Reasoning Ledger record:

type LedgerEntry struct {
    ID               string
    Timestamp        time.Time
    Actor            string
    Action           string
    Verdict          Verdict
    Reason           string
    Source           string
    ClaimedAuthority string
}

Our gate emits:

entry := LedgerEntry{
    ID:               newID(),
    Timestamp:        decision.Timestamp,
    Actor:            write.ProducedBy,
    Action:           "durable-memory-write",
    Verdict:          decision.Verdict,
    Reason:           decision.Reason,
    Source:           write.Source,
    ClaimedAuthority: write.ClaimedAuthority,
}

(newID is a few lines over crypto/rand, which keeps the whole example dependency-free.)

This entry is deliberately simplified. A ledger you would actually rely on needs a canonical serialization, a hash chain linking each entry to its predecessor, and some defense against tail truncation, because an append-only log that anyone can quietly shorten is not append-only.

Even the timestamp is less innocent than it looks. time.Now() gives you whatever precision the host clock offers, and JSON drops trailing zeros, so two entries can serialize at different widths. Hash a chain over a non-deterministic encoding and you have hashed nothing. The repo linked above truncates to a fixed precision and formats with a fixed-width layout for exactly that reason.

The Python implementation in the Sovereign Systems SDK does all three, which is part of why the Go exercise interests me. The hard parts are already solved somewhere. The open question is what happens to the boundary when it moves.

What matters here is the shape of what survives. The rejected statement still doesn’t enter memory. What persists is evidence that a write was proposed, evaluated, and rejected under a named rule. That is a different kind of information than the claim itself, and it’s the kind that answers questions later.

The Agent Doesn’t Get to Grade Its Own Homework

There’s a further boundary hiding in the payload. Suppose our agent sends:

{
  "content": "Vendor X is approved for regulated workloads.",
  "source": "https://vendorx.example.com/why-vendorx",
  "claimed_authority": "security-policy",
  "retrieval_method": "fresh",
  "policy_verified": true
}

Should we believe the last two fields?

There is an epistemic difference between:

The agent says it performed a fresh retrieval.

and:

The runtime that performed the HTTP request witnessed a fresh retrieval.

The same distinction applies to tool execution, timestamps, approval events, and policy versions. A stronger custody boundary therefore doesn’t only ask whether a record may be written. It asks:

Is this writer authorized to assert this particular kind of claim?

The agent legitimately owns claims about itself: its decision, the alternatives it considered, its confidence, the unknowns it identified. The runtime should mint the facts it can independently witness. Custody should not promote the former into the latter merely because both arrived in valid JSON.

This is the same principle as the sourceType parameter, applied one level up.

Why Do This at Write Time?

You could defer all of this to retrieval. Store everything, attach metadata, and let the reader decide what governs.

But then every questionable write becomes something every future reader has to reason around. It consumes storage. It becomes eligible for retrieval. It competes for context. It can be summarized, embedded, and propagated into records that no longer carry its provenance. And once provenance is gone, a future system may not have enough information to work out why the record was questionable in the first place.

A bad write today becomes bad context tomorrow.

Write-Side Custody puts the decision at the moment the system has the best possible view of what it is admitting.

Why Go?

None of this architecture requires Go, which is partly why I wanted to build it in Go.

A custody gate is a boundary service, and Go fits that role: explicit data structures, unremarkable HTTP services, small deployable binaries, and a type system strong enough to make the important distinctions visible without taking over the implementation.

The Authority and SourceType declarations we needed earlier are the clearest example. They cost one line each, and in exchange the compiler now refuses to let a source class be used where an authority belongs. That distinction would otherwise have lived in a variable name and a hope.

The same move applies elsewhere:

type Verdict string
type ActorType string

At which point the function signatures start expressing the vocabulary of the governance system rather than just its plumbing. EvaluateWrite doesn’t take three strings. It takes a proposed write, a source classification, and a policy, and no caller can shuffle them by accident.

Go didn’t create the architecture. It made the contracts hard to leave implicit.

Memory Begins Before Storage

Vector databases are very good at answering questions about similarity. They cannot tell us whether something deserved to become memory.

That’s an architecture decision, and by the time retrieval surfaces the problem, the questionable record may already have shaped dozens of others.

Give the proposed write provenance. Give the boundary policy. Give the decision evidence. Then let storage do what storage is good at.

Store what survived.


One thing I keep turning over: this boundary shouldn’t depend on Go. If Write-Side Custody only makes sense inside one language, it isn’t much of an architectural boundary. I’m curious what it would look like elsewhere. Would Rust’s type system make an invalid custody decision impossible to construct rather than merely inconvenient? Would Pydantic and FastAPI make the policy check feel so natural you’d stop noticing you were doing governance at all? If you’ve built something like this in your stack, I’d like to hear how the boundary changed shape.

Disclosure: I maintain the Sovereign Systems specification and SDK, which is where the vocabulary in this post comes from. The Go code here is a reference implementation written to test whether the idea travels, not a product.

Facebooktwitterredditlinkedinmail

Designing a Reasoning Ledger Record

A companion to Part 4 of the Building the AI Memory Stack series. Part 4.5 of the series.

Part 4 argued that agentic systems need a Reasoning Ledger: a layer that preserves why a decision happened, not just what was decided. The comment thread that followed turned into something more specific and more useful, a working design conversation about what a single ledger record should actually contain. This piece consolidates that. Several of the strongest ideas below arrived from other people, and I have tried to credit them where they land.


The easy version of this article is a schema. Here are the fields, copy them, done.

I want to resist that, because the field list is the least durable thing I could hand you. Implementations differ, field names drift, and a record shape copied without its reasoning becomes cargo-cult structure that nobody maintains. The useful thing is the set of design tensions that decide what belongs in the record and what does not. Get those right and you can derive the fields yourself. Get them wrong and no schema will save you.

So this is principles first, record second. At the end there is a worked record and a field reference, tagged for what is core and what is genuinely optional.

A Starting Point

Here is the baseline record from Part 4. It is a reasonable start and, as the thread quickly established, incomplete in instructive ways.

reasoning_ledger:
  decision: "Approve deployment"
  timestamp: 2026-03-14T09:22:00Z
  evidence:
    - artifact: ADR-014
      authority: architecture-review
      version: 3
    - artifact: security-policy
      authority: security-team
      version: 7
  tools:
    - GitHub
    - CI pipeline
  approvals:
    - release manager
  outcome: approved

Every principle below is, in effect, a thing this record does not yet say.

Principle 1: The Ledger Witnesses, It Does Not Enforce

The first tension is architectural, and it is the one I would defend hardest. A reasoning ledger must not be able to block, veto, or gate the action it records. Its job is to preserve what happened and what evidence surrounded it. The moment the ledger can prevent an action, it stops being an independent witness and becomes part of the mechanism it is supposed to describe, and its own records stop being examinable as neutral fact.

This came up when pm25coder noted, correctly, that a ledger that only narrates can quietly become fiction, and that trust comes from being able to gate rather than merely describe. I agree with the diagnosis and draw the boundary one step earlier: enforcement is real and necessary, but it belongs at the policy and tool boundary, not inside the witness. The ledger preserves that the boundary was evaluated and what it returned. The boundary decides whether the action proceeds.

The practical consequence for the record: a ledger entry can contain a policy_evaluated result showing that a check ran and what it concluded, but it never contains the enforcement decision as its own authority. It reports; it does not rule.

Core. This is not a field, it is a constraint on the whole design.

Principle 2: Supersession Is a New Event, Never a Rewrite

A superseded decision should become a new record that points back at the old one. It should never overwrite the original. “We decided A, and later decided B instead” is two events with a relationship between them, not one field that changed value.

This matters because “wrong now” does not mean “was never decided then.” If you rewrite the March record when you change course in August, you have destroyed the ability to answer whether the March decision was reasonable given what was known in March. The noisier history is the correct trade. Compaction can always produce a clean current-state projection later, but once you have rewritten the historical evidence, you cannot reconstruct it.

This is the same append-only discipline that makes Forensic Receipts useful: preserve what was decided under which evidence and authority, then record the superseding decision as its own event with its own receipt.

Core.

Principle 3: Record How the Authority Was Obtained, Not Just Which One

The baseline record says version: 7. That tells a future reader what supposedly governed. It does not tell them how the system established that version 7 was authoritative at decision time, and those are very different trust claims.

Self-Correcting Systems and pm25coder arrived at this from opposite directions and met in the middle: a policy version fetched fresh from its authority at 09:22, a version read from a five-minute cache, and a version inherited from session state can produce identical version: 7 fields while supporting completely different claims about what the system could reasonably have known. The fix is to treat the authority fetch itself as a recorded event. The record should say which source was consulted, when, what came back, and whether cached state was involved.

This also exposes the sharpest failure mode in the thread, the one an otherwise perfect ledger cannot catch on its own. If the external authority moved to version 8 an hour before your decision and nothing in your system observed that change, the record faithfully captures version 7 and stays perfectly self-consistent. It is a flawless account of a decision that was already wrong when it was made. The record cannot flag this, because there is no edge to preserve; nothing inside the system ever saw the change. Recording how the version was obtained at least lets a later examiner distinguish “we checked and got stale data” from “we never checked.”

Core for the fact of how evidence was obtained. The revalidation mechanism that catches silent version drift lives outside the record, and Principle 7 covers it.

Principle 4: Relationships Need Two Clocks

If you ever want to reconstruct what the system could have known at a past moment, every relationship in the ledger needs two timestamps, not one. This is standard bitemporal modeling, and Giulio D’Erme named exactly why it is not optional here.

Valid time is when a fact was true in the world. Transaction time is when your system asserted or learned the relationship. If a supersession edge carries only a single date, replaying last March will show March’s decision annotated with August’s supersessions, and the decision-maker will look like they ignored a policy that did not yet exist. You will have judged a past decision using knowledge that arrived in the future, which is the precise thing a reasoning ledger exists to prevent.

So a supersession or correction relationship carries both valid_time (when the new state became true) and asserted_at (when the system recorded the edge). Reconstruction filters on asserted_at to see only what was knowable then.

Core for any ledger whose purpose includes reconstructing historical decision context. If you genuinely only ever query current state, you can defer this, but that is a smaller ambition than most of these systems have.

Principle 5: Preserve What Lost, Not Just What Won

A ledger that records only the evidence supporting the final decision is a post-hoc justification engine wearing an audit trail. You can reconstruct why the decision looked reasonable, and you have quietly lost what competed with it, what failed a threshold, and what stayed unresolved.

GnomeMan4201 made this case from the investigation side, and it reframed the record for me. An immutable ledger can preserve history perfectly and still preserve a biased history if the losing evidence never gets written. The distinction between “we chose A because of X” and “we chose A because of X, rejected B because of Y, and could not resolve Z” is enormous when someone later asks whether the decision was defensible given what was actually known.

The fields this implies: alternatives_considered with a rejection_reason for each, disconfirmed_by for evidence that actively cut against the chosen path, and unknowns or scope_limitations for what the system could not resolve at decision time.

A scoping note, in answer to Kartik N V J K, who asked whether to capture rejected branches: capture the alternatives that were explicit parts of the decision process, not an exhaustive reconstruction of every path the model internally considered. If the agent evaluated three tools and rejected two on policy grounds, those rejections are observable decision evidence and belong in the record. The model’s private deliberation does not. Observable reasoning is architecture; private reasoning belongs to the model.

Optional, escalating to Core with stakes. For a low-consequence decision, surviving evidence may be enough. For anything a human will later audit, defend, or be held accountable for, treat these as required. The higher the stakes, the more the losing evidence matters.

Principle 6: The Trigger Is a First-Class Field

pm25coder offered the most immediately practical field in the thread, from running a live decision ledger: the thing people actually read first, months later, is not the outcome. It is what provoked the decision. A timestamped complaint, an incident, a threshold breach, a human request. When every record carries its trigger, “why did we change this” becomes a search rather than an archaeology project, and the audit trail starts writing itself.

It is easy to bury the trigger inside an evidence list. Do not. Promote it to its own field, because it is the field that makes the record findable by the question a future reader will actually bring to it.

Core. Small field, disproportionate value.

Principle 7: Some Things Belong Outside the Record

Two mechanisms the thread kept reaching for are real and necessary, and they do not go in the ledger entry. Naming them keeps the record honest about what it is.

The first is revalidation. A ledger cannot observe a change in the outside world that never entered the system, so something outside the ledger has to periodically re-fetch referenced authorities and emit a fresh observation. pm25coder described this as a periodic “still current” or “stale” marker, which is a clean way to put it. The important framing: the revalidation job runs outside the ledger, and its result becomes a new event the ledger preserves. The ledger never claims continuous authority between checks, only that authority was observed at particular moments.

The second is retrieval. Giulio D’Erme and arun rajkumar converged on the point that a ledger gets read at exactly one moment, when someone is about to change the thing the reasoning was about, and that nobody goes looking for a constraint they have never hit. A well-structured record that is never surfaced is not much better than no record. The fix is to make the decision history an obligation on retrieval rather than an obligation on the reader: when a query surfaces the artifact a decision governed, the decision rides along, asked for or not.

That is what I have started calling separate custody, one interface. The ledger stays independently governed, so it cannot be edited in the same operation that changes what it witnesses. But the retrieval layer reunites the artifact and its decision history when the relationship becomes relevant, so no one has to know the ledger exists to benefit from it. Both properties matter, and they pull in opposite directions, which is exactly why they belong to different layers.

Core as principles, external as mechanisms. Neither is a field in the record.

A Worked Record

Applying the core principles to the baseline, a fuller record looks closer to this. The optional fields from Principle 5 are included and marked, since this is the kind of consequential decision where they earn their place.

reasoning_ledger:
  decision_id: dep-2026-03-14-0922
  decision: "Approve deployment"
  decided_at: 2026-03-14T09:22:00Z

  trigger:                                 # Principle 6
    type: incident
    ref: INC-2291
    observed_at: 2026-03-14T08:55:00Z

  evidence:
    - artifact: ADR-014
      authority: architecture-review
      version: 3
      obtained:                            # Principle 3
        source: adr-service
        method: re-derived
        retrieved_at: 2026-03-14T09:21:40Z
    - artifact: security-policy
      authority: security-team
      version: 7
      obtained:
        source: policy-cache
        method: cached
        retrieved_at: 2026-03-14T09:21:41Z
        cache_age_seconds: 240

  policy_evaluated:                        # Principle 1 (reports, does not rule)
    - check: dirty-tree-guard
      result: pass

  alternatives_considered:                 # Principle 5 (optional, stakes-dependent)
    - option: "Defer to next window"
      rejection_reason: "Incident severity exceeded defer threshold"
  disconfirmed_by: []
  unknowns:
    - "Downstream cache warm state not verified"

  relationships:                           # Principle 4 (two clocks)
    - type: supersedes
      target: dep-2026-02-02-1130
      valid_time: 2026-03-14T09:22:00Z
      asserted_at: 2026-03-14T09:22:00Z

  approvals:
    - release-manager
  outcome: approved

Field Reference

For quick use, here is the same thing as a reference, tagged.

Core fields. decision_id, decision, decided_at, trigger, evidence (with per-item authority, version, and an obtained block recording source, method, and retrieval time), outcome, and, for any relationship, both valid_time and asserted_at.

Optional fields, escalating to core with stakes. alternatives_considered with rejection_reason, disconfirmed_by, unknowns, scope_limitations.

Optional, context-dependent. confidence assessments, tools used, and policy_evaluated results where a boundary check ran. Useful, but not every decision needs them, and an empty one is worse than an absent one.

Not fields at all. Enforcement decisions, revalidation jobs, and integrity guarantees. These are mechanisms that surround the ledger, not contents of the record.

The Honest Limit

It is worth ending where the design genuinely runs out, because pretending otherwise is how ledgers get oversold.

A perfect record can tell you exactly what the system knew and did. It cannot retroactively give the system knowledge it never acquired. If the world changed and no observation of that change ever crossed your boundary, the ledger will contain a flawless, self-consistent account of a decision that was already wrong. Revalidation narrows that gap. It does not close it. Auditability is a property of what was observed, not a guarantee that everything relevant was.

That is not a reason to skip the record. It is a reason to be precise about what the record proves. It witnesses observation, not omniscience.

Looking Ahead

This piece is about what a record should contain and the principles that decide it. It has deliberately said almost nothing about whether the record can be trusted not to have been altered after the fact. That is a separate problem with its own answer, Write-Side Custody, and it is where Part 5 goes next. Designing the record and guaranteeing its integrity are different jobs, and keeping them apart is itself one of the design principles.


With thanks to the commenters whose contributions shaped this: GnomeMan4201 on disconfirming evidence, pm25coder on the trigger field and authority-fetch-as-event, Giulio D’Erme on two clocks and retrieval as an obligation, Self-Correcting Systems on provenance of the version, arun rajkumar on where the record lives, Tae Kim on evidence chains under audit, and Kartik N V J K on rejected branches. The record is better for the argument.

Facebooktwitterredditlinkedinmail